Scrapers / Developer & File Tools
Line Deduplicator, Sorter & Shuffler
hipersoft/line-dedup-sort
Clean big text and list files: remove duplicate lines, sort alphabetically or numerically, reverse, shuffle and trim blanks — handles lists too large for a desktop editor.
Total users
2Monthly users
1Total runs
78Per list processed
$0.005Last rebuilt
Oct 26, 2026Overview
Clean big text and list files in one run — remove duplicate lines, sort, reverse, shuffle, trim whitespace and drop blank lines. Handles keyword lists, URL lists and wordlists far too large for a desktop text editor, and returns a ready-to-download cleaned file.
What it does
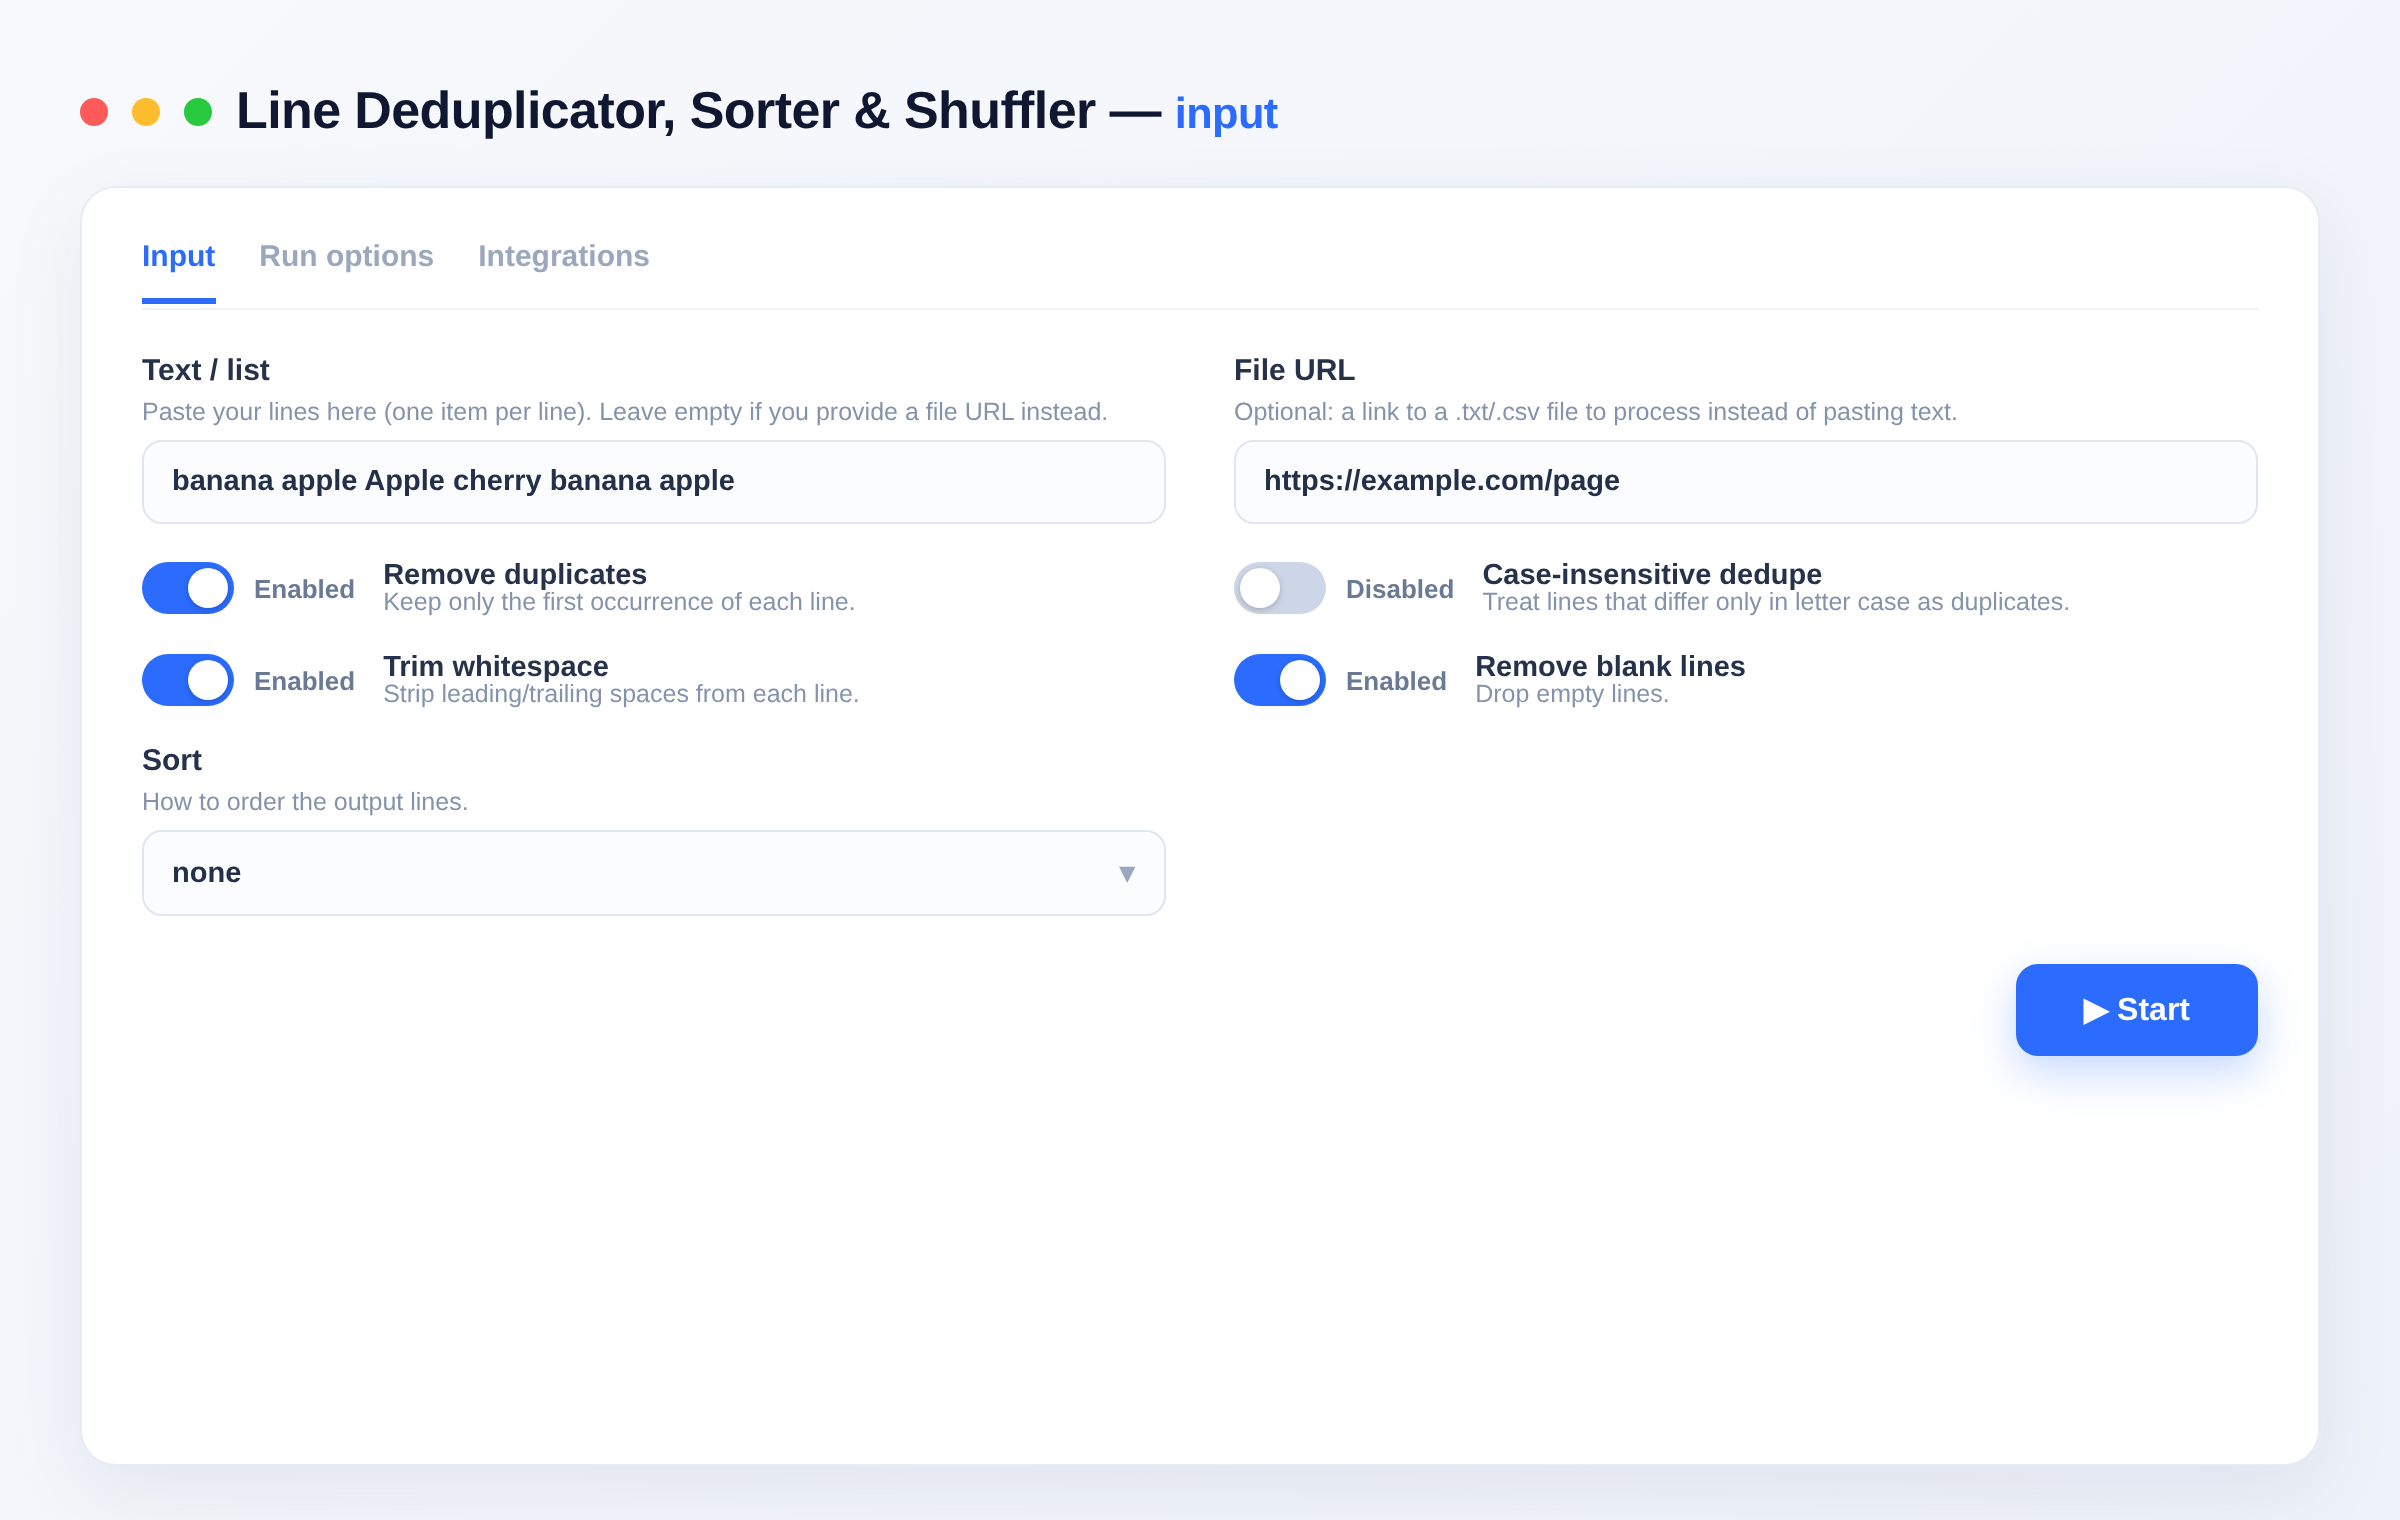
- Deduplicate lines (optionally case-insensitive).
- Sort A→Z, Z→A, natural (numbers-aware), reverse, or shuffle.
- Trim whitespace and remove blank lines.
- Returns counts (in/out, duplicates, blanks) + the cleaned file.
Use cases
- SEO / PPC — dedupe and sort huge keyword lists.
- Data cleaning — tidy URL lists and exports before import.
- Security / research — process large wordlists that choke local editors.
Input
Paste text, or point to a file URL.
{ "text": "banana\napple\nApple\ncherry\nbanana", "dedupe": true, "caseInsensitiveDedupe": false, "trim": true, "removeBlankLines": true, "sort": "asc" }
| Field | Type | Description |
|---|---|---|
text |
string | Lines to process (one per line). |
fileUrl |
string | Optional link to a .txt/.csv file instead of pasting. |
dedupe |
boolean | Remove duplicate lines. Default true. |
caseInsensitiveDedupe |
boolean | Treat case-different lines as duplicates. |
trim |
boolean | Strip leading/trailing spaces. Default true. |
removeBlankLines |
boolean | Drop empty lines. Default true. |
sort |
string | none, asc, desc, natural, reverse, shuffle. |
Output
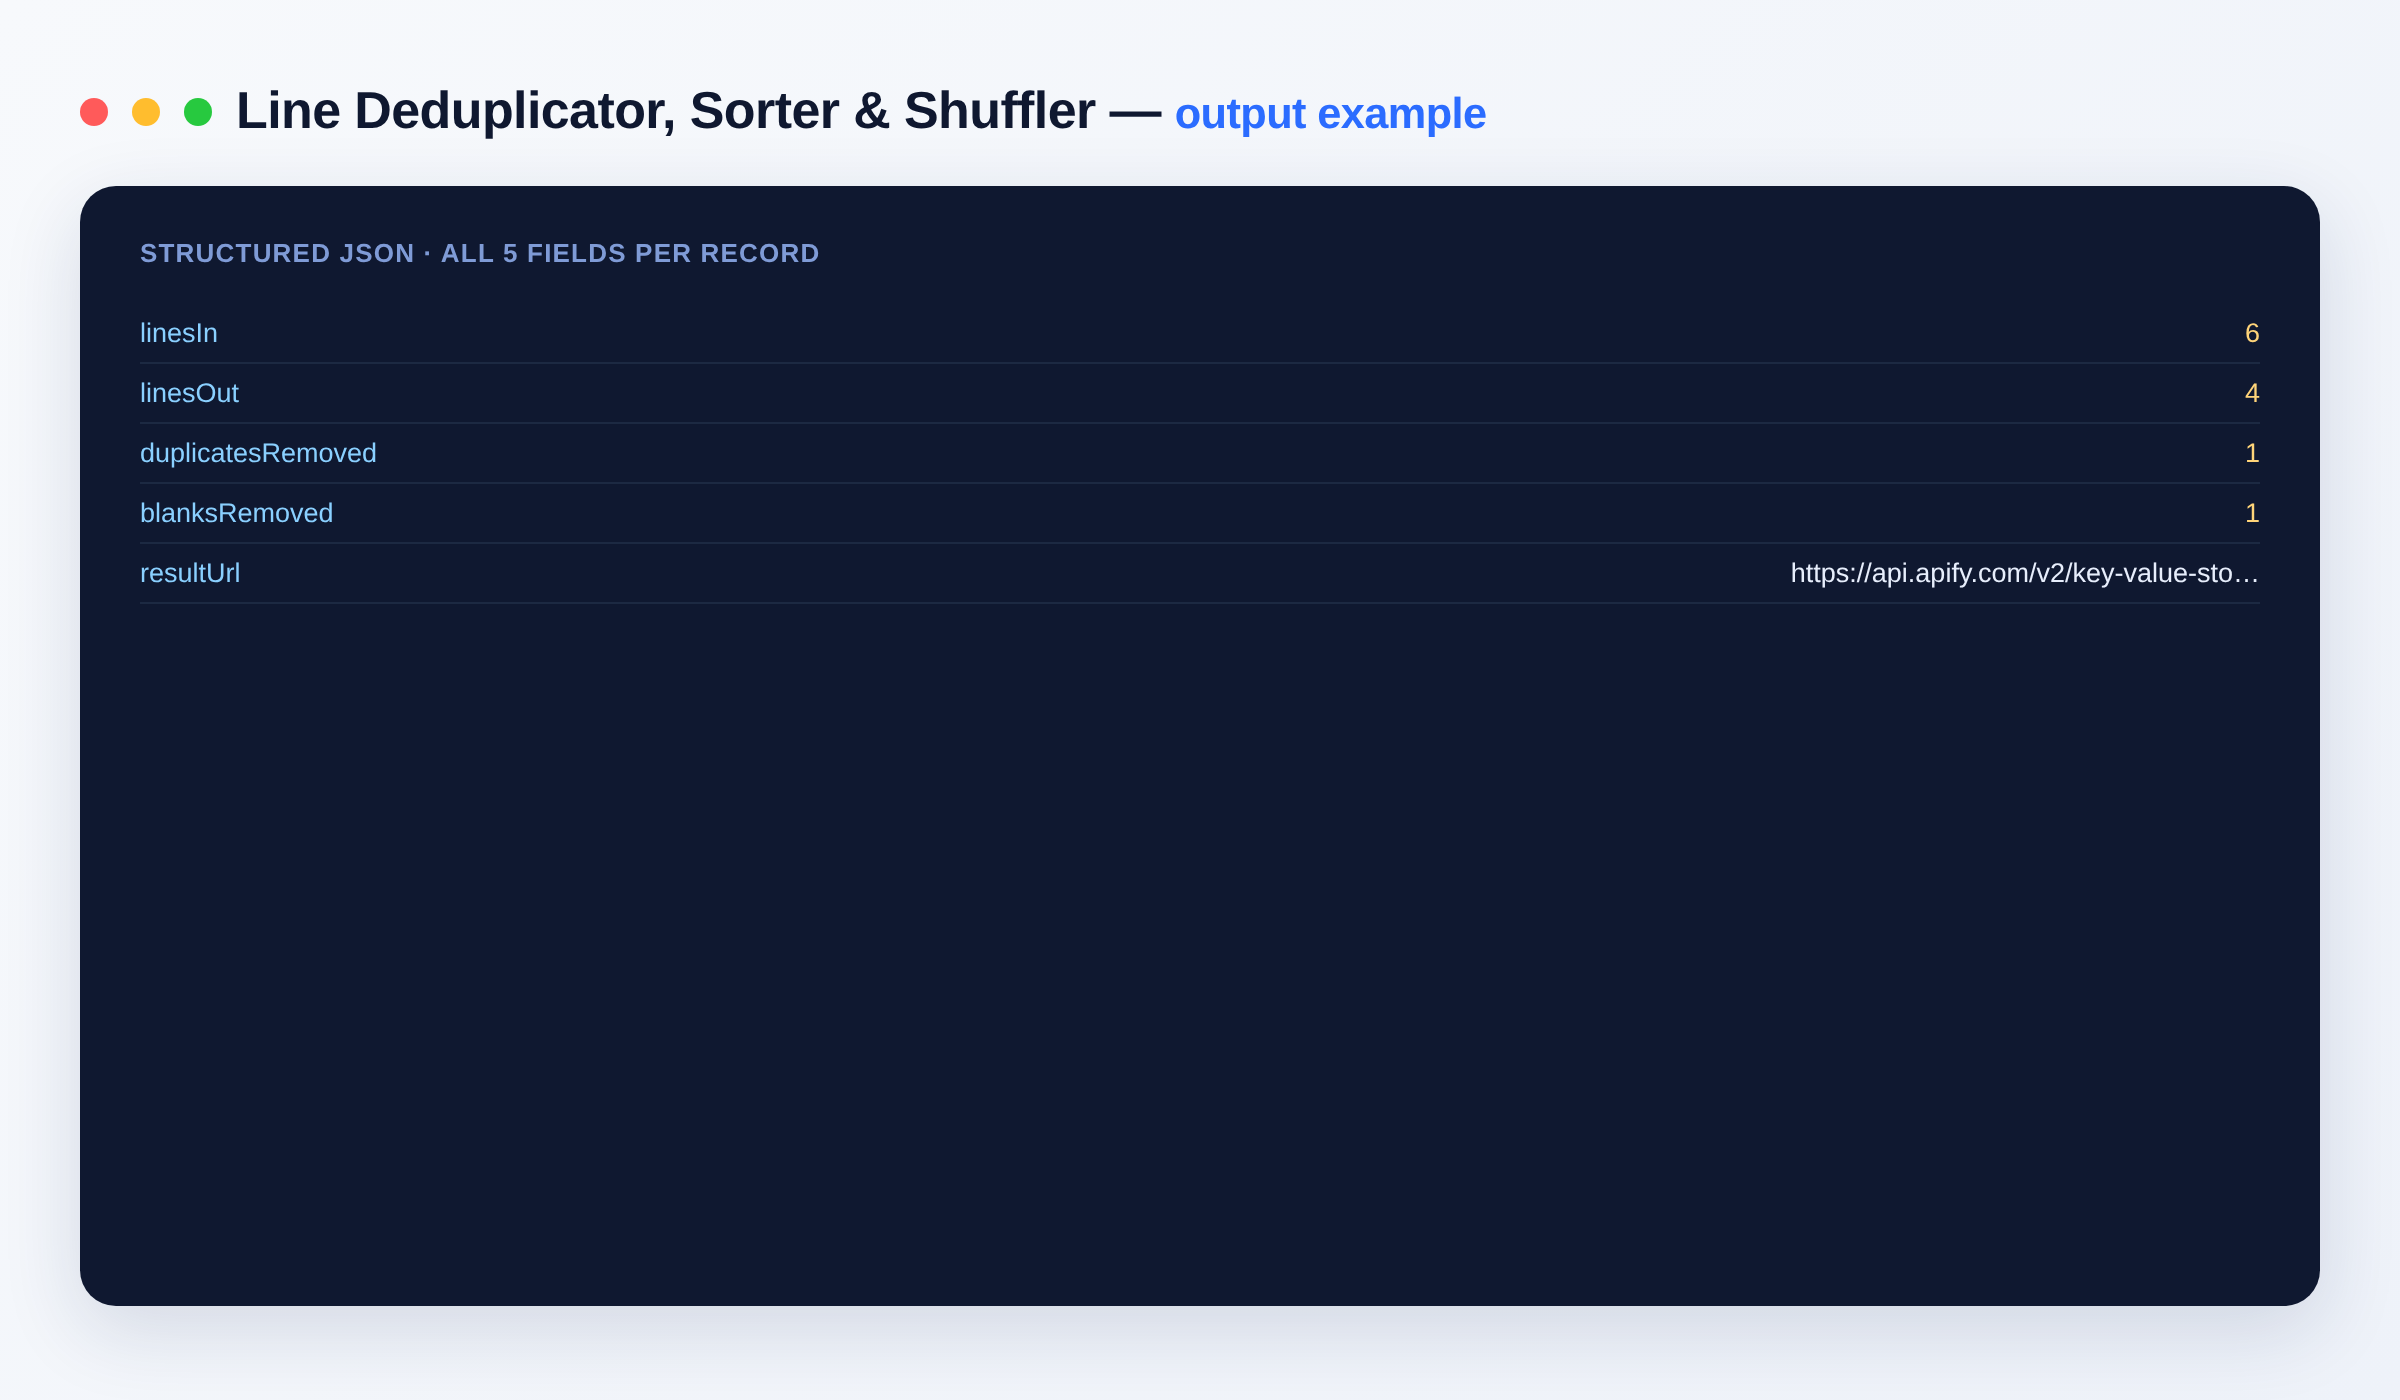
A summary row, plus the cleaned file at result.txt in your key-value store.
{ "linesIn": 5, "linesOut": 3, "duplicatesRemoved": 1, "blanksRemoved": 0, "resultUrl": "https://api.apify.com/v2/key-value-stores/.../records/result.txt" }
Output schema
| Field | Type | Description |
|---|---|---|
linesIn |
integer | Lines in the input. |
linesOut |
integer | Lines after processing. |
duplicatesRemoved |
integer | Duplicate lines removed. |
blanksRemoved |
integer | Blank lines removed. |
resultUrl |
string (URL) | Link to the cleaned text file. |
FAQ
How big a list can it handle? Very large — it streams the file into memory and processes in one pass.
Can I automate it? Yes — via integrations on the Apify platform and the Apify API.
Notes
Original clean-room implementation.
Input
| Field | Type | Description |
|---|---|---|
textText / list | string | Paste your lines here (one item per line). Leave empty if you provide a file URL instead. |
fileUrlFile URL | string | Optional: a link to a .txt/.csv file to process instead of pasting text. |
dedupeRemove duplicates | boolean | Keep only the first occurrence of each line. Default: true |
caseInsensitiveDedupeCase-insensitive dedupe | boolean | Treat lines that differ only in letter case as duplicates. Default: false |
trimTrim whitespace | boolean | Strip leading/trailing spaces from each line. Default: true |
removeBlankLinesRemove blank lines | boolean | Drop empty lines. Default: true |
sortSort | string · none, asc, desc, natural, reverse, shuffle | How to order the output lines. Default: "none" |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~line-dedup-sort/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "text": "banana\napple\nApple\ncherry\n\nbanana\n  apple  "
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/line-dedup-sort").call(run_input={
"text": "banana\napple\nApple\ncherry\n\nbanana\n apple "
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/line-dedup-sort').call({
"text": "banana\napple\nApple\ncherry\n\nbanana\n apple "
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| List processed One list/text file cleaned, deduped and sorted | $0.005 | $0.0025 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scrapedSend the site and the fields. We build it and you get it first.