Twitch Scraper
hipersoft/twitch-scraper
Scrape Twitch channels (followers, partner status, description, live status, last broadcast) and browse live streams globally or by game (title, viewers, streamer, game). Fast clean HTTP via Twitch's public GraphQL. For streaming analytics and creator discovery.
Total users
5Monthly users
4Total runs
112Per item scraped
$0.0085Last rebuilt
Oct 28, 2026Overview
Scrape Twitch channels and live streams into clean structured JSON: followers, partner status, description, live status, and last broadcast for any channel — plus a browse of currently-live streams globally or by game. Fast and clean, with no login or API key. Built for streaming analytics, creator discovery, and esports monitoring.
Features
- 📺 Channel profiles —
followers,isPartner,isAffiliate,description,createdAt, andprofileImage. - 🔴 Live status —
isLive,liveViewers,liveTitle,liveGame, andliveStartedAtin every channel record. - ⏮️ Last broadcast —
lastBroadcastAtandlastBroadcastTitlefor channels that are currently offline. - 🎮 Browse live streams — enable
includeTopStreamsfor global top streams, or setstreamsGameto filter by category. - 🔗 Flexible input — accepts channel logins (
shroud) ortwitch.tv/...URLs. - ⚡ No key, no login — just pass channel logins or URLs, no setup required.
- 🧹 Tidy records — normalized text and a ready-to-use channel
urlon every row.
What you get
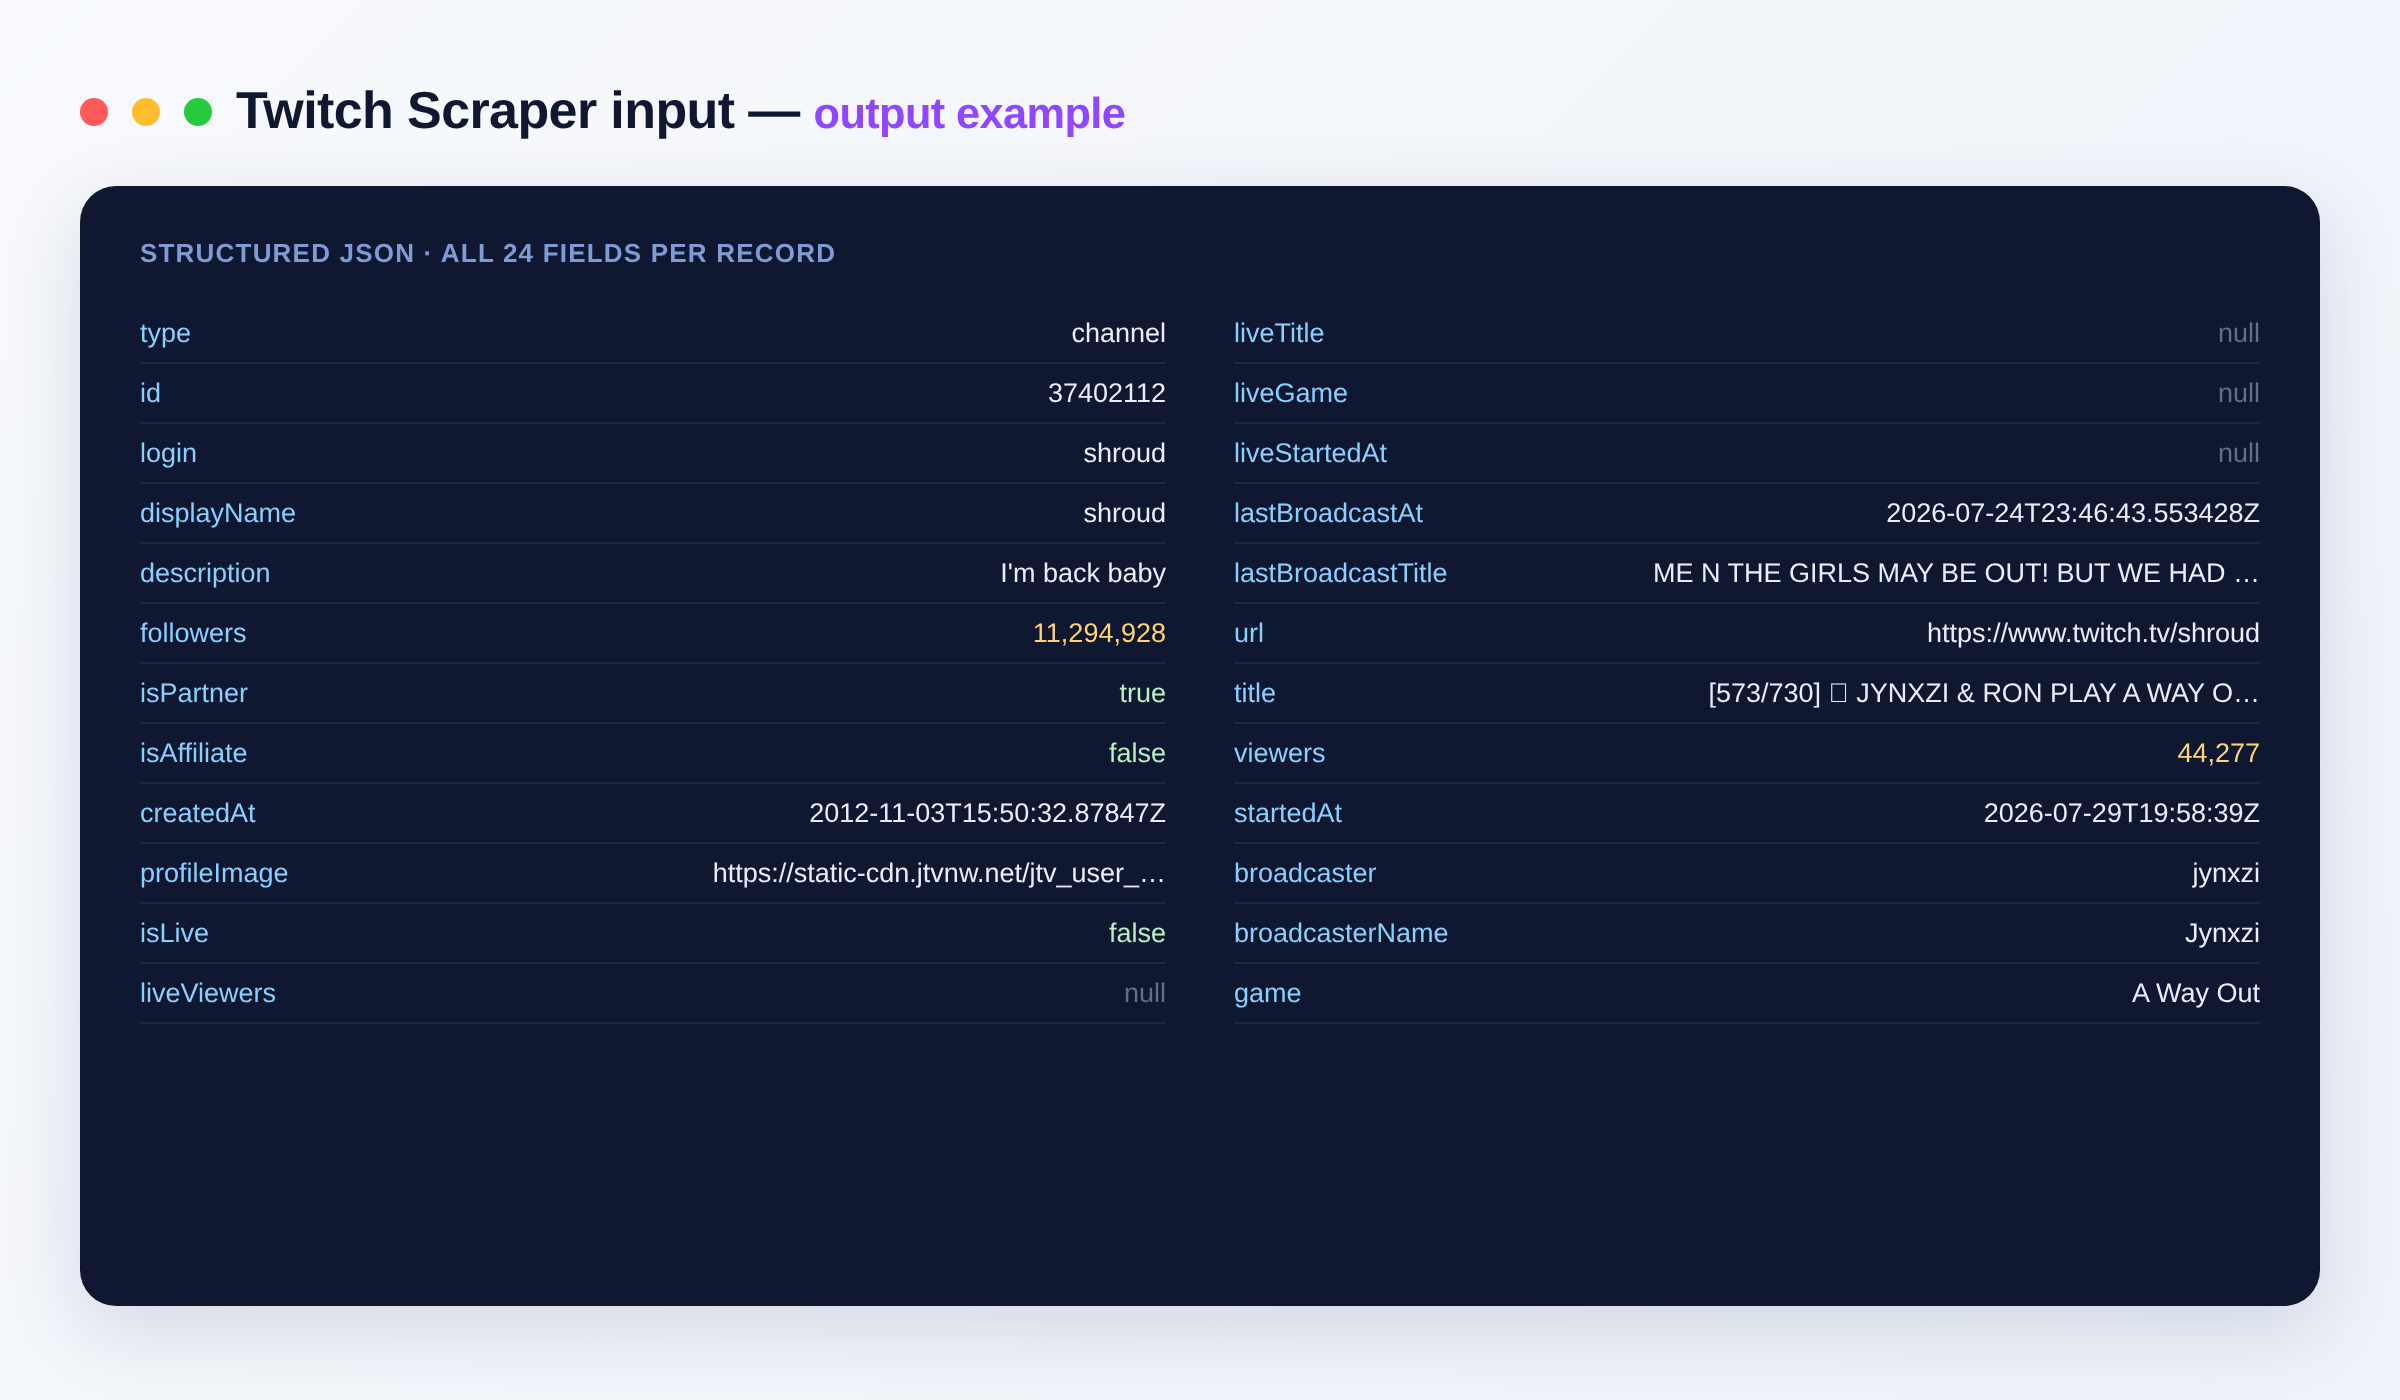
Each channel is one clean JSON record:
{
  "type": "channel",
  "id": "37402112",
  "login": "shroud",
  "displayName": "shroud",
  "description": "Professional gamer",
  "followers": 10500000,
  "isPartner": true,
  "isAffiliate": false,
  "createdAt": "2012-10-08T20:16:52Z",
  "profileImage": "https://static-cdn.jtvnw.net/.../profile.png",
  "isLive": true,
  "liveViewers": 24500,
  "liveTitle": "ranked grind",
  "liveGame": "VALORANT",
  "liveStartedAt": "2026-07-23T18:02:00Z",
  "lastBroadcastAt": "2026-07-22T21:10:00Z",
  "lastBroadcastTitle": "chill stream",
  "url": "https://www.twitch.tv/shroud"
}
Live streams (when includeTopStreams is on) come as type: "stream" records with id, title, viewers, startedAt, broadcaster, broadcasterName, game, and url.
Output schema
Channel records and stream records share the type, id and url fields; the rest are specific to one record type, as noted.
| Field | Type | Description |
|---|---|---|
type |
string | Record type — channel or stream. |
id |
string | Twitch ID of the channel or stream. |
login |
string | Channel login/username (channel). |
displayName |
string | Channel display name (channel). |
description |
string | Channel bio/description (channel). |
followers |
integer | Follower count (channel). |
isPartner |
boolean | Whether the channel is a Twitch Partner (channel). |
isAffiliate |
boolean | Whether the channel is a Twitch Affiliate (channel). |
createdAt |
string (ISO date) | When the channel was created (channel). |
profileImage |
string (URL) | Channel profile image URL (channel). |
isLive |
boolean | Whether the channel is currently live (channel). |
liveViewers |
string | Current live viewer count (channel, when live). |
liveTitle |
string | Title of the current live broadcast (channel, when live). |
liveGame |
string | Game/category of the current live broadcast (channel, when live). |
liveStartedAt |
string | When the current live broadcast started (channel, when live). |
lastBroadcastAt |
string (ISO date) | When the channel last broadcast (channel, when offline). |
lastBroadcastTitle |
string | Title of the channel's last broadcast (channel, when offline). |
title |
string | Stream title (stream). |
viewers |
integer | Current viewer count of the stream (stream). |
startedAt |
string | When the stream started (stream). |
broadcaster |
string | Login of the streaming channel (stream). |
broadcasterName |
string | Display name of the streaming channel (stream). |
game |
string | Game/category being streamed (stream). |
url |
string (URL) | Link to the channel or stream on twitch.tv. |
Input
{
  "channels": ["shroud", "twitch.tv/pokimane"],
  "includeTopStreams": true,
  "streamsGame": "Just Chatting",
  "maxStreams": 30
}
| Field | Description |
|---|---|
channels |
Channel logins or twitch.tv/... URLs. |
includeTopStreams |
Also fetch currently-live streams. |
streamsGame |
Filter live streams to a game; empty = global top. |
maxStreams |
Max live streams (Twitch caps anonymous browse at 30). |
proxyConfiguration |
Optional proxy configuration. |
Use cases
- Track follower growth and live status for a roster of creators.
- Discover currently-live streamers in a specific game category.
- Monitor viewer counts for esports and marketing analytics.
- Verify partner/affiliate status across a set of channels.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need a Twitch account or API key?
No. Just pass channel logins or twitch.tv/... URLs — no login, key, or setup is required.
Can I get currently-live streams, not just channels?
Yes. Turn on includeTopStreams for global top streams, or set streamsGame to filter live streams by category.
In what format is the data returned? Every run produces a clean dataset you can export to JSON, CSV, Excel, or pull via the Apify API.
Can I connect the Twitch Scraper to other tools? The Twitch Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
This Actor reads only public channel and stream data — no login or key. It is an independent tool and is not affiliated with, endorsed by, or connected to Twitch Interactive, Inc. Scrape public data only.
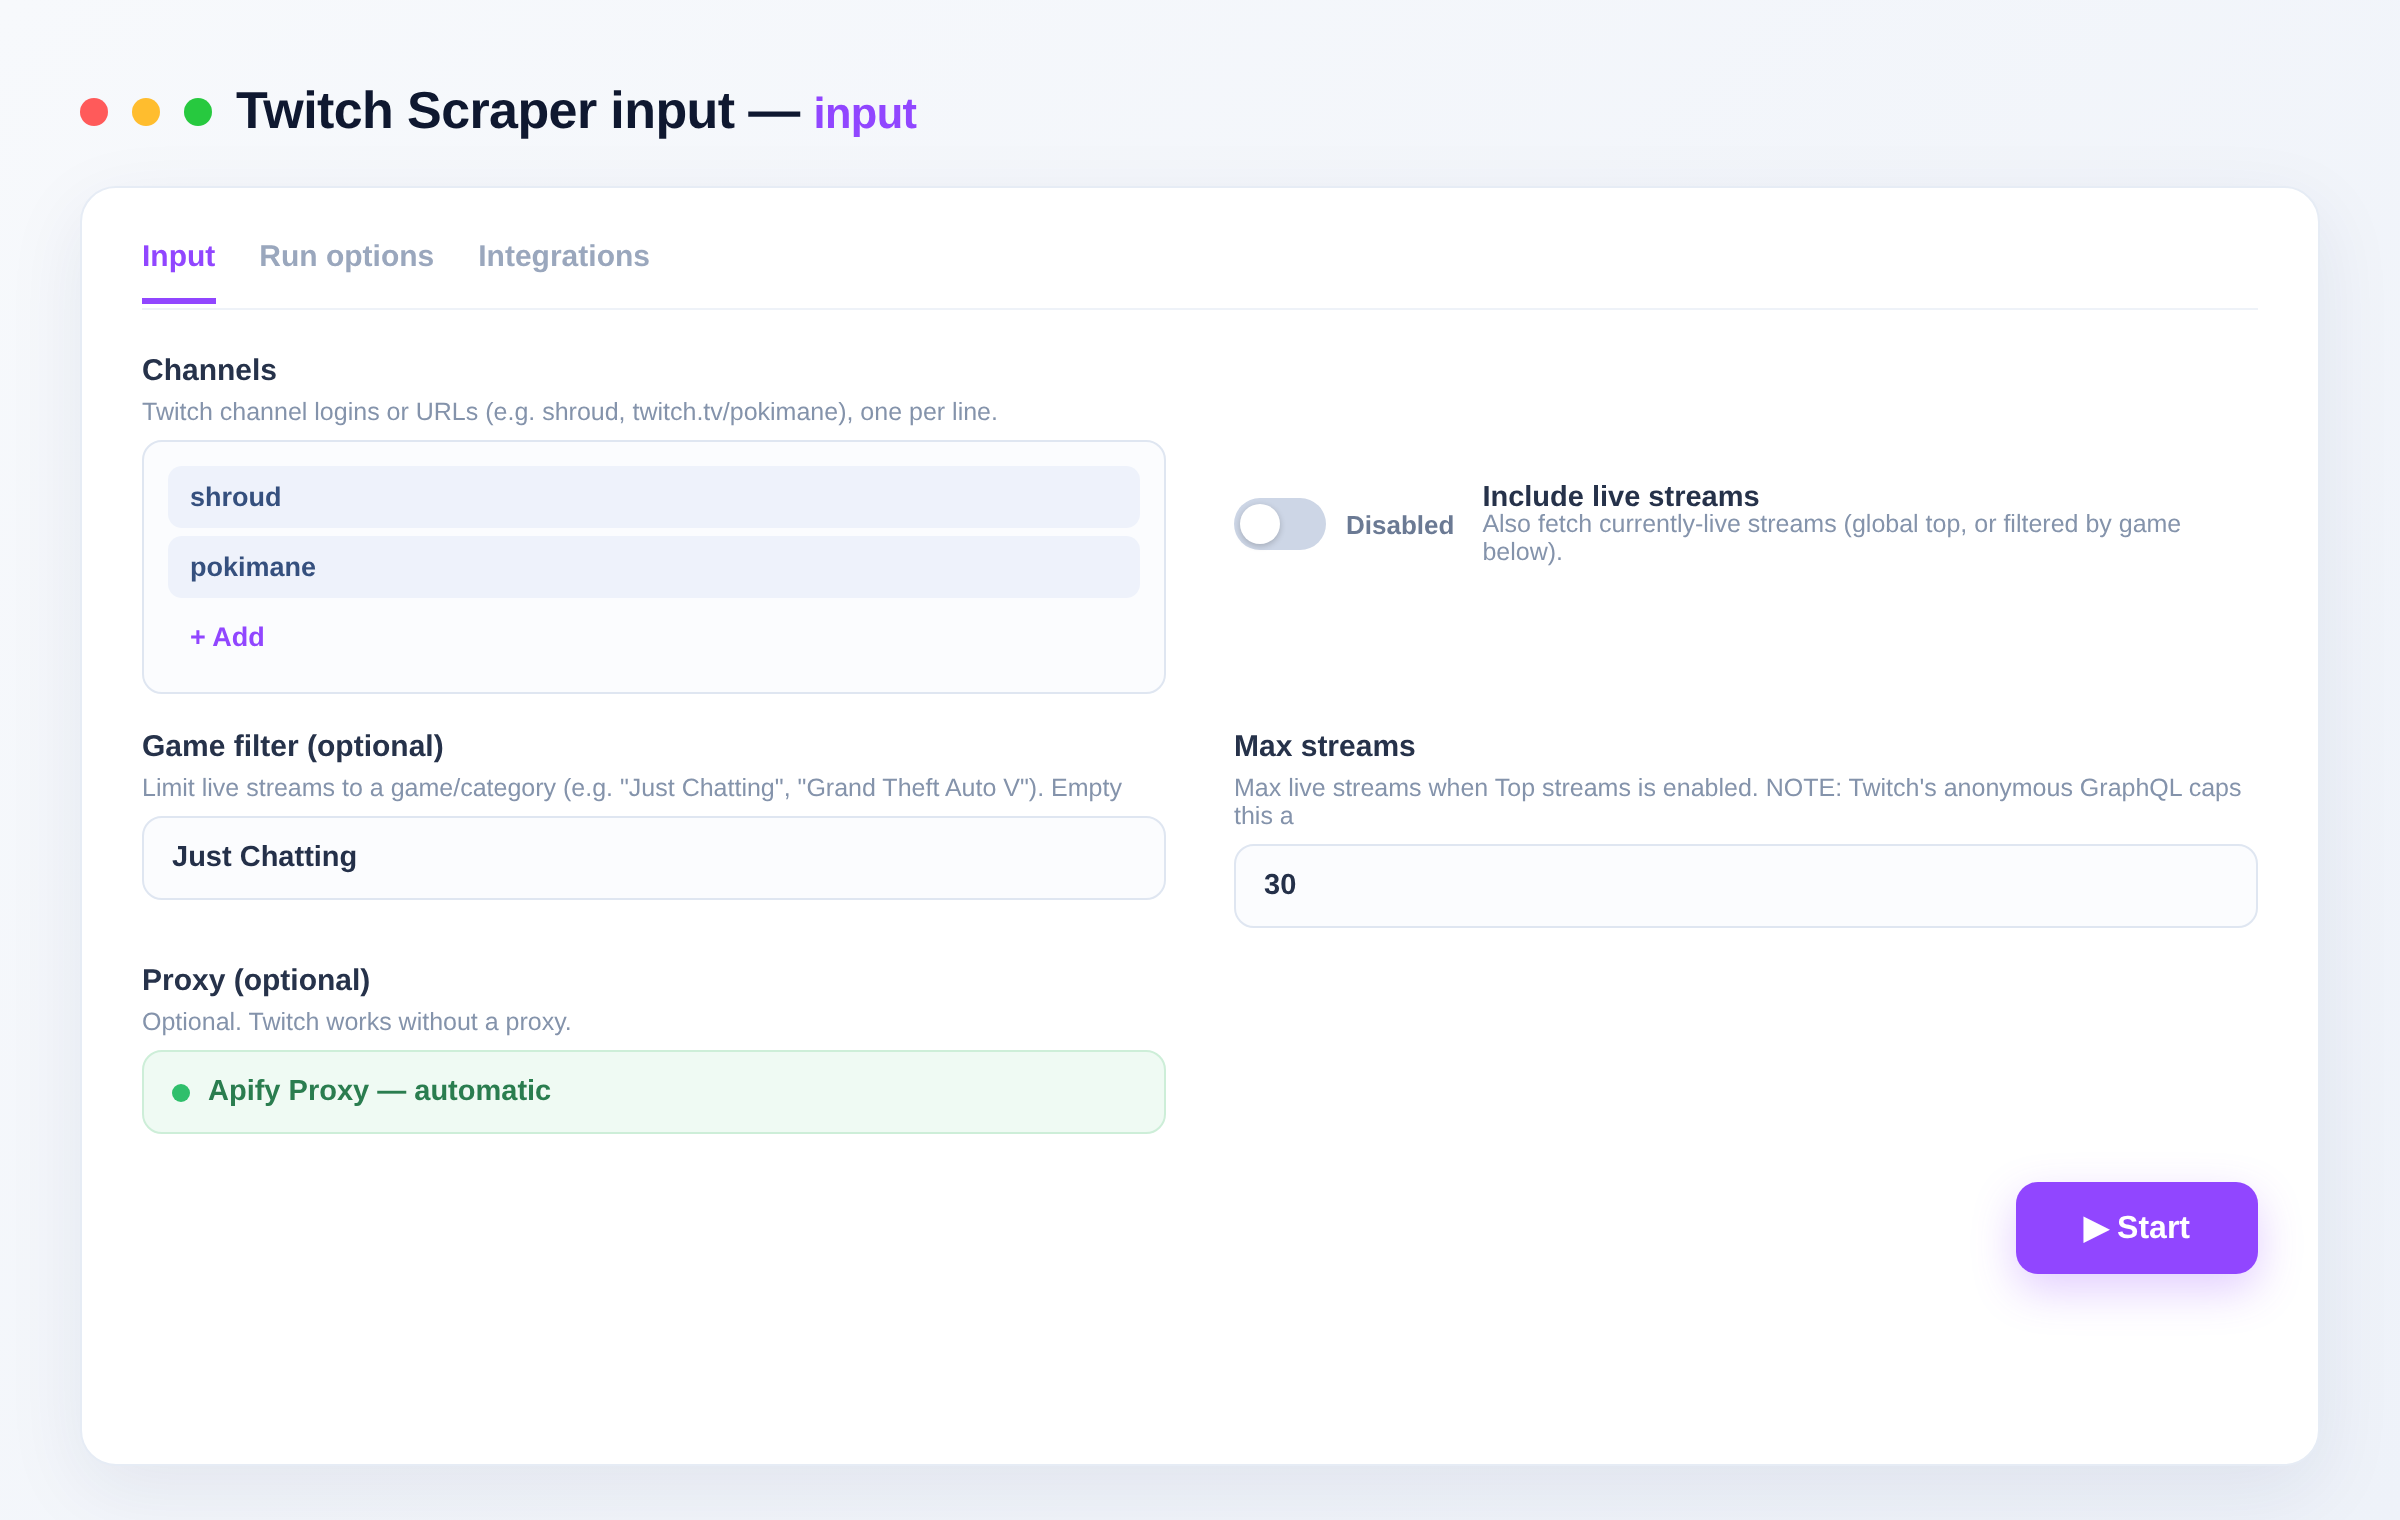
Input
| Field | Type | Description |
|---|---|---|
channelsChannels | array | Twitch channel logins or URLs (e.g. shroud, twitch.tv/pokimane), one per line. |
includeTopStreamsInclude live streams | boolean | Also fetch currently-live streams (global top, or filtered by game below). Default: false |
streamsGameGame filter (optional) | string | Limit live streams to a game/category (e.g. "Just Chatting", "Grand Theft Auto V"). Empty = global top streams. |
maxStreamsMax streams | integer | Max live streams when Top streams is enabled. NOTE: Twitch's anonymous GraphQL caps this at 30 and integrity-gates further pagination, so top/game streams return at most 30. (The 'channels' input is unaffected.) Default: 30 |
proxyConfigurationProxy (optional) | object | Optional. Twitch works without a proxy. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~twitch-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "channels": [
    "shroud",
    "pokimane"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/twitch-scraper").call(run_input={
"channels": [
"shroud",
"pokimane"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/twitch-scraper').call({
"channels": [
"shroud",
"pokimane"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Item scraped One channel or live stream with full metadata (followers, viewers, game, status) | $0.0085 | $0.0043 |
| API request One Twitch GraphQL request (a channel lookup or a page of streams) | $0.001 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Website Contact Scraper
Extract business emails, phone numbers and social media profiles from any list of websites. De-obfuscates emails, reads Organization schema, and optionally crawls contact/about pages. Bulk-ready.
1,576 runs · 69 users · $0.0024 / website scraped
Threads Downloader
Download Threads photos, videos and carousel posts by URL. Paste threads.net or threads.com links and get ready-to-use download links plus direct media URLs, a thumbnail, media type and count — one row per URL as JSON, CSV or Excel. Cheap, bulk, built for creators and n8n.
799 runs · 4 users · $0.003 / post downloaded
TikTok Video Downloader
Download TikTok videos without watermark in bulk. Paste video or photo-slideshow URLs and get a clean HD MP4 download link plus full metadata: caption, author, play/like/comment/share counts, sound and cover — one row per post as JSON, CSV or Excel. For creators, research and n8n.
678 runs · 9 users · $0.0035 / video downloaded
Reddit Scraper
Scrape Reddit posts and comments by subreddit, keyword, author or thread URL. Get titles, self-text, scores, upvote ratio, comment counts, comment trees and permalinks — one clean row per post or comment. Export as JSON, CSV or Excel.
568 runs · 15 users · $0.0034 / post scraped
Spotify Scraper
Search Spotify and scrape public metadata for tracks, artists, albums and playlists: names, artists, popularity, followers, genres, release dates, duration, ISRC, preview URL and more. No Spotify login or API key required. For music research, catalogs and analytics.
478 runs · 9 users · $0.0034 / item scraped
Reddit Video, Image & GIF Downloader
Download Reddit videos, images and GIFs by post URL. Paste reddit.com or redd.it links and get ready-to-use download links — videos as a single playable MP4 with audio, images and galleries as direct links — one row per URL as JSON, CSV or Excel. Cheap, bulk, built for creators and n8n.
453 runs · 16 users · $0.003 / item scrapedSend the site and the fields. We build it and you get it first.