Bilibili Scraper
hipersoft/bilibili-scraper
Scrape Bilibili videos: title, uploader, views, likes, coins, favorites, danmaku, category, duration and cover. Popular feed, category rankings, or video details by BV id.
Total users
2Monthly users
1Total runs
86Per video scraped
$0.002Last rebuilt
Oct 26, 2026Overview
Scrape Bilibili (哔哩哔哩) into clean JSON, CSV, Excel or XML. This Bilibili scraper extracts video titles, uploaders, view counts, likes, coins, favorites, danmaku, replies, shares, category, duration, publish date, description and cover images — from the popular/trending feed, category rankings (top 100), or any video by its BV id. A fast, cheap, no-code alternative to building your own Bilibili data pipeline: no setup, just add inputs and run.
Whether you track China's biggest video platform for creator intelligence, trend research or content analytics, this Bilibili video scraper turns the trending feed and rankings into a structured dataset in one run.
What does the Bilibili Scraper do?
The Bilibili Scraper crawls and extracts public Bilibili video data across three modes: the popular/trending feed, category rankings (the top 100 for any category), and video details by BV id. Point it at what you want and it returns structured data points — views, likes, coins, favorites, danmaku (bullet comments), replies, uploader, category, duration and more — ready for analytics, datasets, LLM pipelines, trend tracking or market research.
What data can you scrape from Bilibili?
| Group | Fields |
|---|---|
| 📈 Engagement stats | view count, like count, coins, favorites, danmaku (bullet comments), replies, shares |
| 🎬 Video metadata | BV id, title, description, category, duration (seconds), publish date, cover image, canonical URL |
| 👤 Uploader | uploader name, uploader mid (member id) |
| 🔀 Modes | popular/trending feed, category ranking (top 100), video details by BV id |
| 🕒 Run meta | collected-at timestamp for every item |
Use cases
- Track trending videos — snapshot the popular feed and category rankings to see what's rising on Bilibili right now.
- Creator & channel intelligence — pull uploader names, view counts and engagement to benchmark creators in any niche.
- Content & market research — study which formats, categories and topics win views, likes and coins.
- Build a video dataset — thousands of videos with views, likes, coins, danmaku and metadata for analytics or ML.
- Engagement & sentiment signals — measure danmaku, replies and favorites as audience-response indicators.
- Competitor monitoring — watch rankings over time to track share of attention in your category.
- Recommendation & trend models — feed structured engagement data into scoring and forecasting pipelines.
- Academic & market studies — analyze public video engagement on China's leading video platform.
How to scrape Bilibili data
- Click Try for free / Start to open the Bilibili Scraper.
- Choose a mode — popular/trending feed, category ranking, or video details by BV id.
- For ranking mode set the category id, or for details mode paste the BV ids you want.
- Set Max videos to cap the run, then click Run.
- Download the results as JSON, CSV, Excel or XML, or pull them from the API.
Input
Pick a mode, then set the options for that mode. No login or setup required.
{
  "mode": "popular",
  "maxItems": 200
}
Category ranking (top 100):
{
  "mode": "ranking",
  "rankingCategoryId": 0,
  "maxItems": 100
}
Video details by BV id:
{
  "mode": "videos",
  "bvids": ["BV1GJ411x7h7", "BV1xx411c7XX"]
}
| Field | Type | Description |
|---|---|---|
mode |
string | What to scrape: popular (trending feed), ranking (category top 100), or videos (details by BV id). |
rankingCategoryId |
integer | For ranking mode — the Bilibili category id (0 = all categories). |
bvids |
array | For videos mode — the BV ids to fetch, e.g. BV1xx411c7XX. |
maxItems |
integer | Maximum number of videos to scrape (default 100). |
Scrape the popular / trending feed
Set mode to popular and Bilibili's trending videos are returned with full engagement stats and metadata, up to your maxItems cap.
Scrape category rankings
Set mode to ranking and choose a rankingCategoryId to pull the top 100 videos for that category (use 0 for all).
Scrape video details by BV id
Set mode to videos and pass the BV ids in bvids to fetch full stats and metadata for exactly the videos you want.
Output
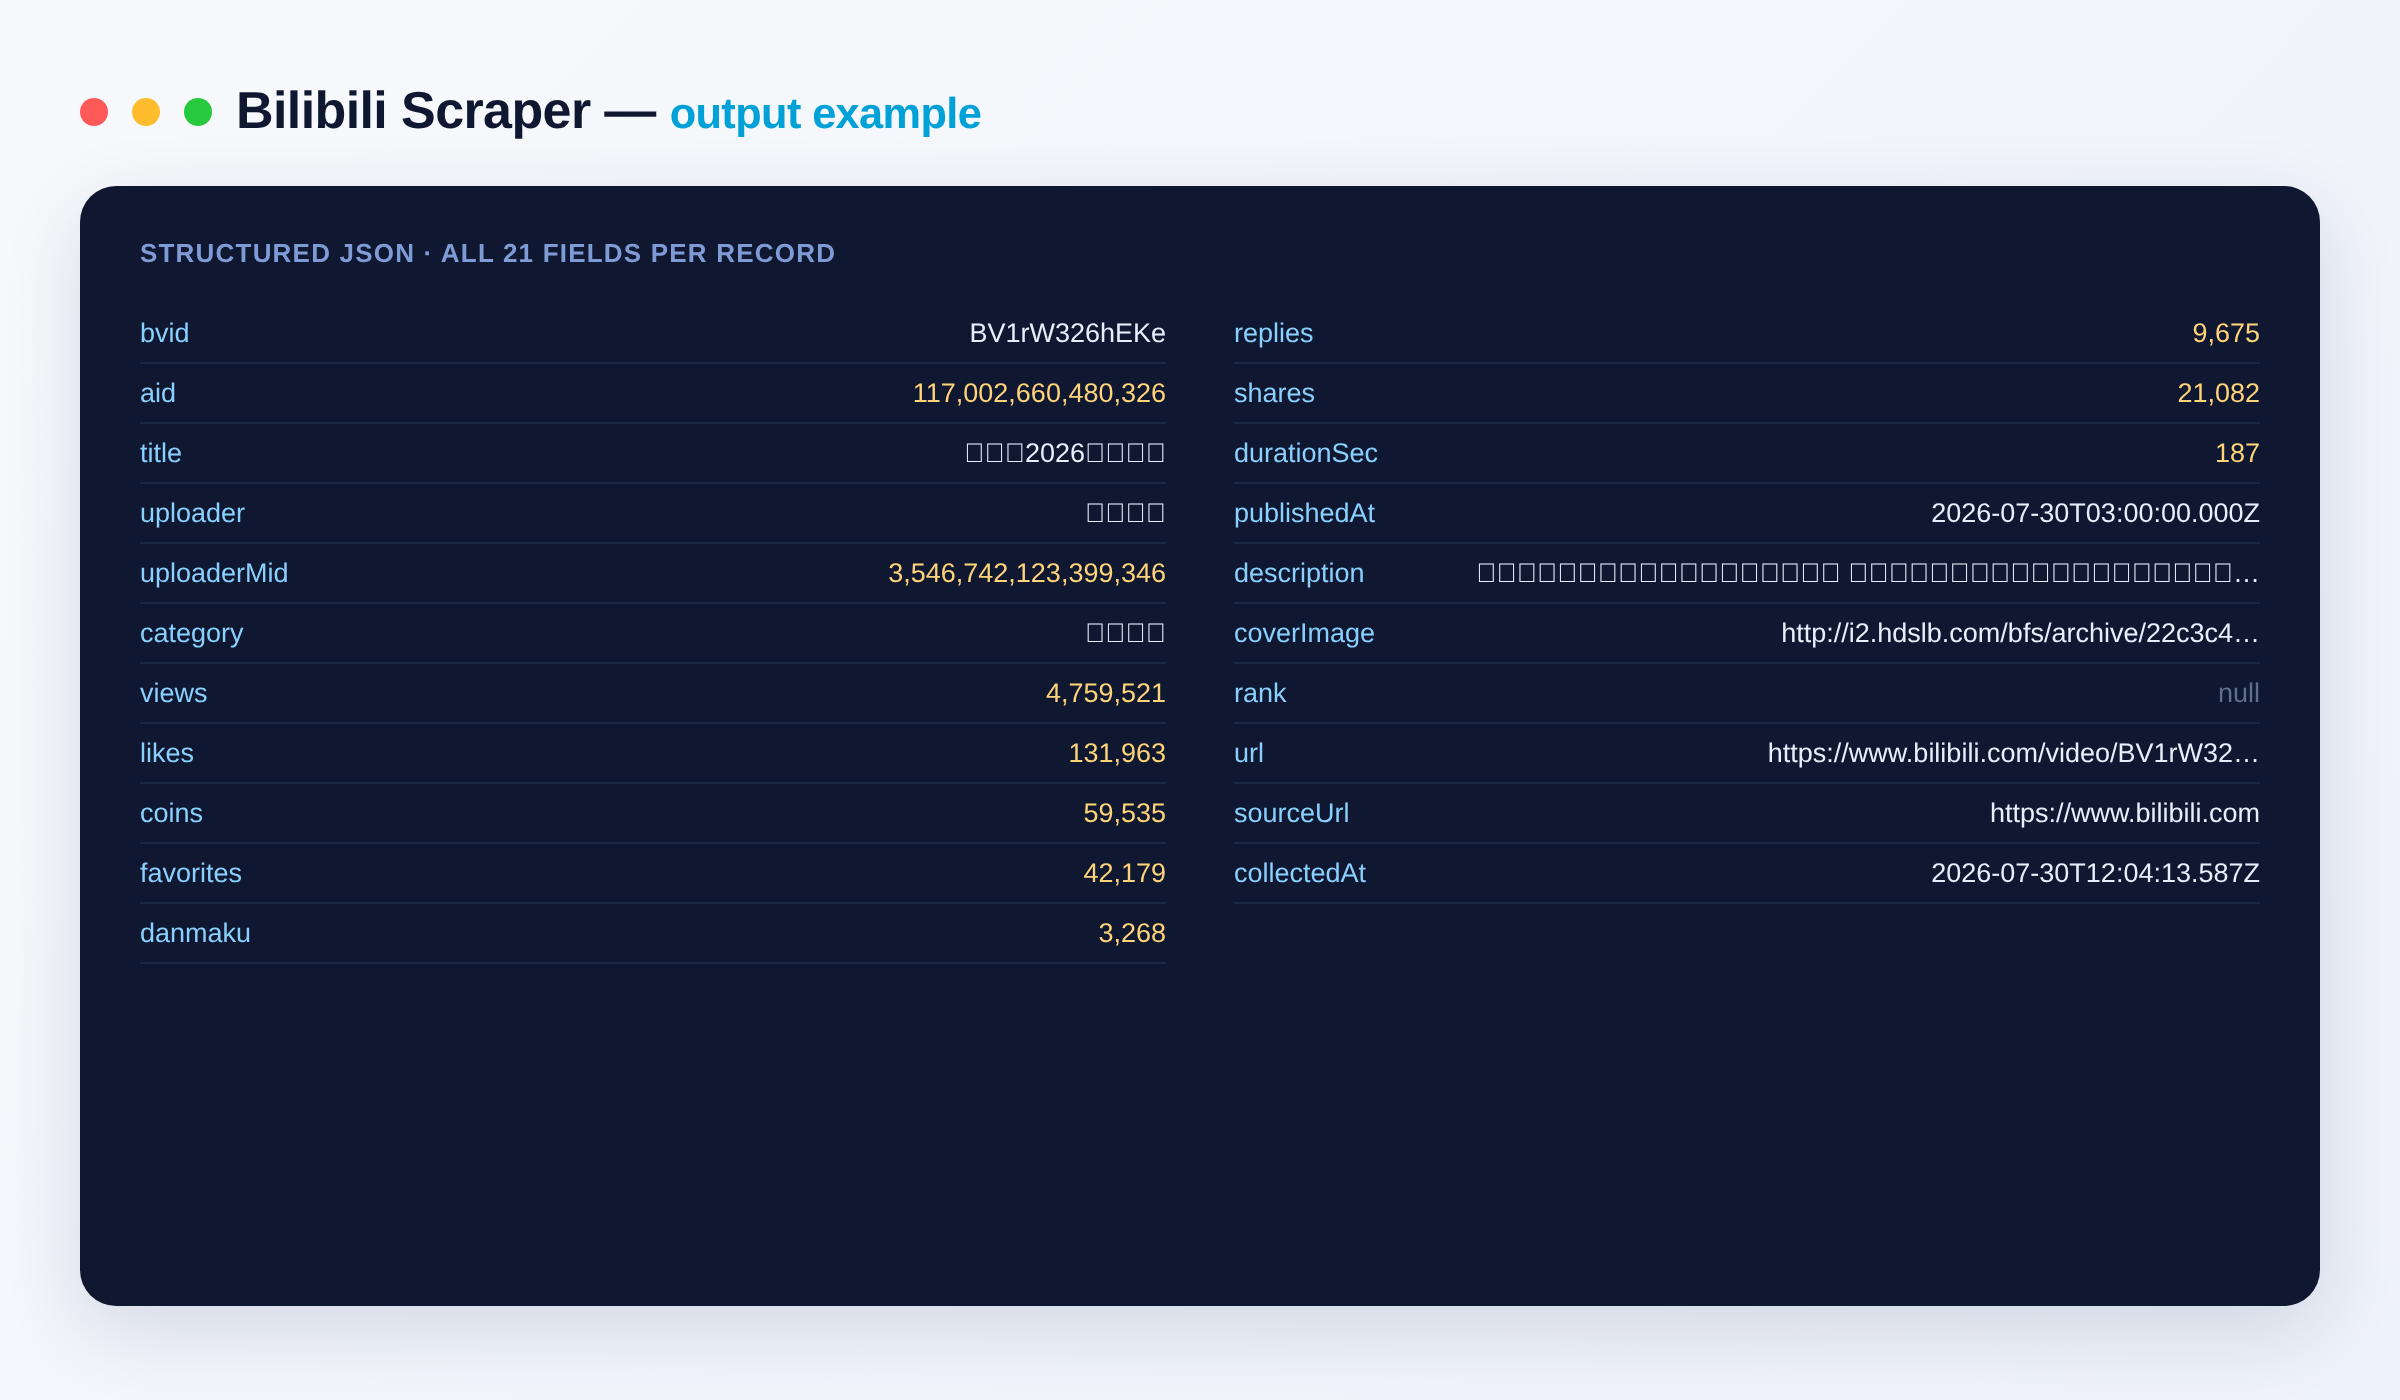
Each video is one dataset item:
{
  "bvid": "BV1xx411c7XX",
  "title": "抵抗者2026实机演示",
  "uploader": "浩汤科技",
  "uploaderMid": 12345678,
  "views": 4693132,
  "likes": 120000,
  "coins": 30000,
  "favorites": 45000,
  "danmaku": 8000,
  "replies": 5400,
  "shares": 2100,
  "category": "游戏",
  "durationSec": 605,
  "publishedAt": "2026-07-28T10:00:00.000Z",
  "description": "全新实机演示,展示核心玩法与画面。",
  "coverImage": "https://i0.hdslb.com/bfs/archive/cover.jpg",
  "url": "https://www.bilibili.com/video/BV1xx411c7XX",
  "collectedAt": "2026-07-30T12:00:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
bvid |
string | Bilibili BV id of the video. |
title |
string | Video title. |
uploader |
string | Uploader (creator) display name. |
uploaderMid |
integer | Uploader member id (mid). |
views |
integer | Total view count. |
likes |
integer | Total like count. |
coins |
integer | Number of coins given to the video. |
favorites |
integer | Number of times the video was favorited. |
danmaku |
integer | Danmaku (bullet comment) count. |
replies |
integer | Number of comments/replies. |
shares |
integer | Number of shares. |
category |
string | Video category name. |
durationSec |
integer | Video length in seconds. |
publishedAt |
string (ISO date) | When the video was published. |
description |
string | Video description text. |
coverImage |
string (URL) | Cover/thumbnail image URL. |
url |
string (URL) | Canonical Bilibili video URL. |
collectedAt |
string (ISO date) | Timestamp when the item was collected. |
Need more social & video data?
Building a wider dataset across Chinese social and video platforms? Pair the Bilibili Scraper with our other Actors:
- Weibo Scraper — posts, profiles and engagement from Weibo.
- Xiaohongshu Scraper — notes, creators and stats from RED / Little Red Book.
- Douban Scraper — movies, books and ratings from Douban.
- Juejin Scraper — developer articles, authors and engagement from Juejin.
FAQ
Do I need a Bilibili account or API key? No. The Bilibili Scraper needs no login and no official API key — just choose a mode, set your inputs and run.
How many videos can I scrape per run?
As many as you like. Use maxItems to cap the run; the popular and ranking feeds and any list of BV ids let you scale up to thousands of videos.
Can I scrape trending or ranking videos?
Yes — set mode to popular for the trending feed, or ranking with a rankingCategoryId for the top 100 videos in a category.
Can I get details for specific videos?
Yes — set mode to videos and pass the BV ids in bvids to pull full stats and metadata for exactly those videos.
Can it search by keyword? Not currently. This Actor covers the popular feed, category rankings and video details by BV id.
How does billing work? You pay per video you scrape — a simple, cheap pay-per-result price with no monthly minimum.
What export formats are supported? JSON, CSV, Excel and XML, plus webhooks and the Apify API.
Can I automate or integrate the Bilibili Scraper? Yes. The Bilibili Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification, or kick off another process such as loading your data downstream.
Is scraping Bilibili legal? The Actor collects only public data. You are responsible for how you use it and for complying with Bilibili's terms and applicable laws.
Notes
Original clean-room implementation. Collects only public Bilibili data; you are responsible for how you use the data and for complying with Bilibili's terms. This is an independent tool and is not affiliated with or endorsed by Bilibili.
Input
| Field | Type | Description |
|---|---|---|
modeMode | string · popular, ranking, videos | popular feed, category ranking, or video details by BV id. Default: "popular" |
rankingCategoryIdRanking category id (rid) | integer | For ranking mode: Bilibili category id (0 = all). Default: 0 |
bvidsBV ids | array | For videos mode: BV ids (e.g. BV1xx...). |
maxItemsMax videos | integer | Maximum videos to scrape. Default: 100 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~bilibili-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/bilibili-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/bilibili-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Video scraped One video scraped with stats. | $0.002 | $0.002 |
| API request One Bilibili API request. | $0.0008 | $0.0008 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Dribbble Shots Scraper
Scrape public design shots from Dribbble: title, high-res image, tags, likes, views and designer credit. Filter by category or sort, export JSON, CSV or Excel.
359 runs · 5 users · $0.003 / shot scraped
Computrabajo Scraper
Scrape Computrabajo job listings across Latin America (Mexico, Colombia, Argentina, Chile, Peru and more): title, company, location, salary, posted date and apply URL. Filter by country and keyword. No setup.
206 runs · 4 users · $0.002 / listing scraped
Kraken Market Data Scraper
Fetch Kraken spot market data in bulk: ticker stats (ask, bid, last, 24h high/low/volume/vwap), OHLC candles for any interval, order book depth (top bids/asks), and tradable pair metadata. Fast, clean and cheap.
165 runs · 4 users · $0.001 / pair scraped
Bayt Scraper
Scrape Bayt.com job listings across the Middle East (UAE, Saudi Arabia, Egypt, Qatar and more): title, company, location, posted date and apply URL. Filter by country and keyword.
134 runs · 4 users · $0.003 / job scraped
GitHub Scraper
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos). Uses the GitHub REST API; optional token for higher rate limits. For developer lead generation, OSS research and recruiting.
131 runs · 7 users · $0.0008 / item scraped
Hacker News Scraper
Scrape Hacker News stories, comments, Ask HN, Show HN, jobs and polls by keyword, points, comments and date range. Sort by relevance or newest. Title, URL, author, points, comment count, text and HN link. Fast clean HTTP via the HN Algolia API, no setup.
130 runs · 2 users · $0.004 / item scrapedSend the site and the fields. We build it and you get it first.