Xiaohongshu (RedNote) Scraper
hipersoft/xiaohongshu-scraper
Scrape Xiaohongshu / RedNote notes by keyword: title, author, likes, images and link. Runs a real browser to handle signing. For social & market intelligence.
Total users
3Monthly users
0Total runs
104Per note scraped
$0.004Last rebuilt
Oct 28, 2026Overview
Scrape Xiaohongshu (RedNote / 小红书) public notes at scale into clean JSON, CSV, Excel or XML. This Xiaohongshu scraper extracts note titles, authors, like counts, cover images and note links from the public discover feed and note URLs — no code, no account and no login required. A fast, reliable and cheap way to turn China's biggest lifestyle-and-shopping social network into a structured dataset.
Point it at the explore feed or paste specific note URLs, hit Run, and export ready-to-use data for trend research, creator discovery and market intelligence.
What does the Xiaohongshu Scraper do?
The Xiaohongshu Scraper crawls and extracts public Xiaohongshu (RedNote) data from the discover/explore feed and from individual note URLs. For every note it returns structured data points — title, author, like count, cover image, note URL and note ID — normalized and ready for analytics, datasets, LLM pipelines, dashboards or lead generation. Like counts written in Chinese shorthand (for example 1.1万) are parsed into plain integers (11000) so your data is analysis-ready out of the box.
What data can you scrape from Xiaohongshu?
| Group | Fields |
|---|---|
| 📕 Note | note ID, title, cover image URL, canonical note URL |
| 👤 Author | author / creator display name |
| ❤️ Engagement | like count (normalized from 万 shorthand to a plain integer) |
| 🧾 Provenance | source feed / channel, source URL, collectedAt timestamp |
Use cases
- China trend & social intelligence — track what's trending on the discover feed for any market-research or brand study.
- Creator & influencer discovery — surface authors and their top-performing notes for outreach and partnerships.
- Content research & inspiration — mine titles, cover images and engagement to plan your own content strategy.
- Product & market research — see which lifestyle, beauty, travel and shopping notes get traction.
- Build a Xiaohongshu dataset — collect thousands of notes with engagement and metadata for analysis or LLM training.
- Engagement benchmarking — compare like counts across notes and authors to find outliers.
- Monitoring & alerting — re-run on a schedule to watch a feed and catch new notes over time.
- Academic & market research — study topics, popularity and audience signals from public data.
How to scrape Xiaohongshu data
- Click Try for free / Start to open the Xiaohongshu Scraper.
- Keep
explorefor the public discover feed, or paste specific Xiaohongshu note / explore URLs into the input. - Set Max notes per feed to control how many notes you collect.
- Click Run.
- Download the results as JSON, CSV, Excel or XML, or pull them from the Apify API.
Input
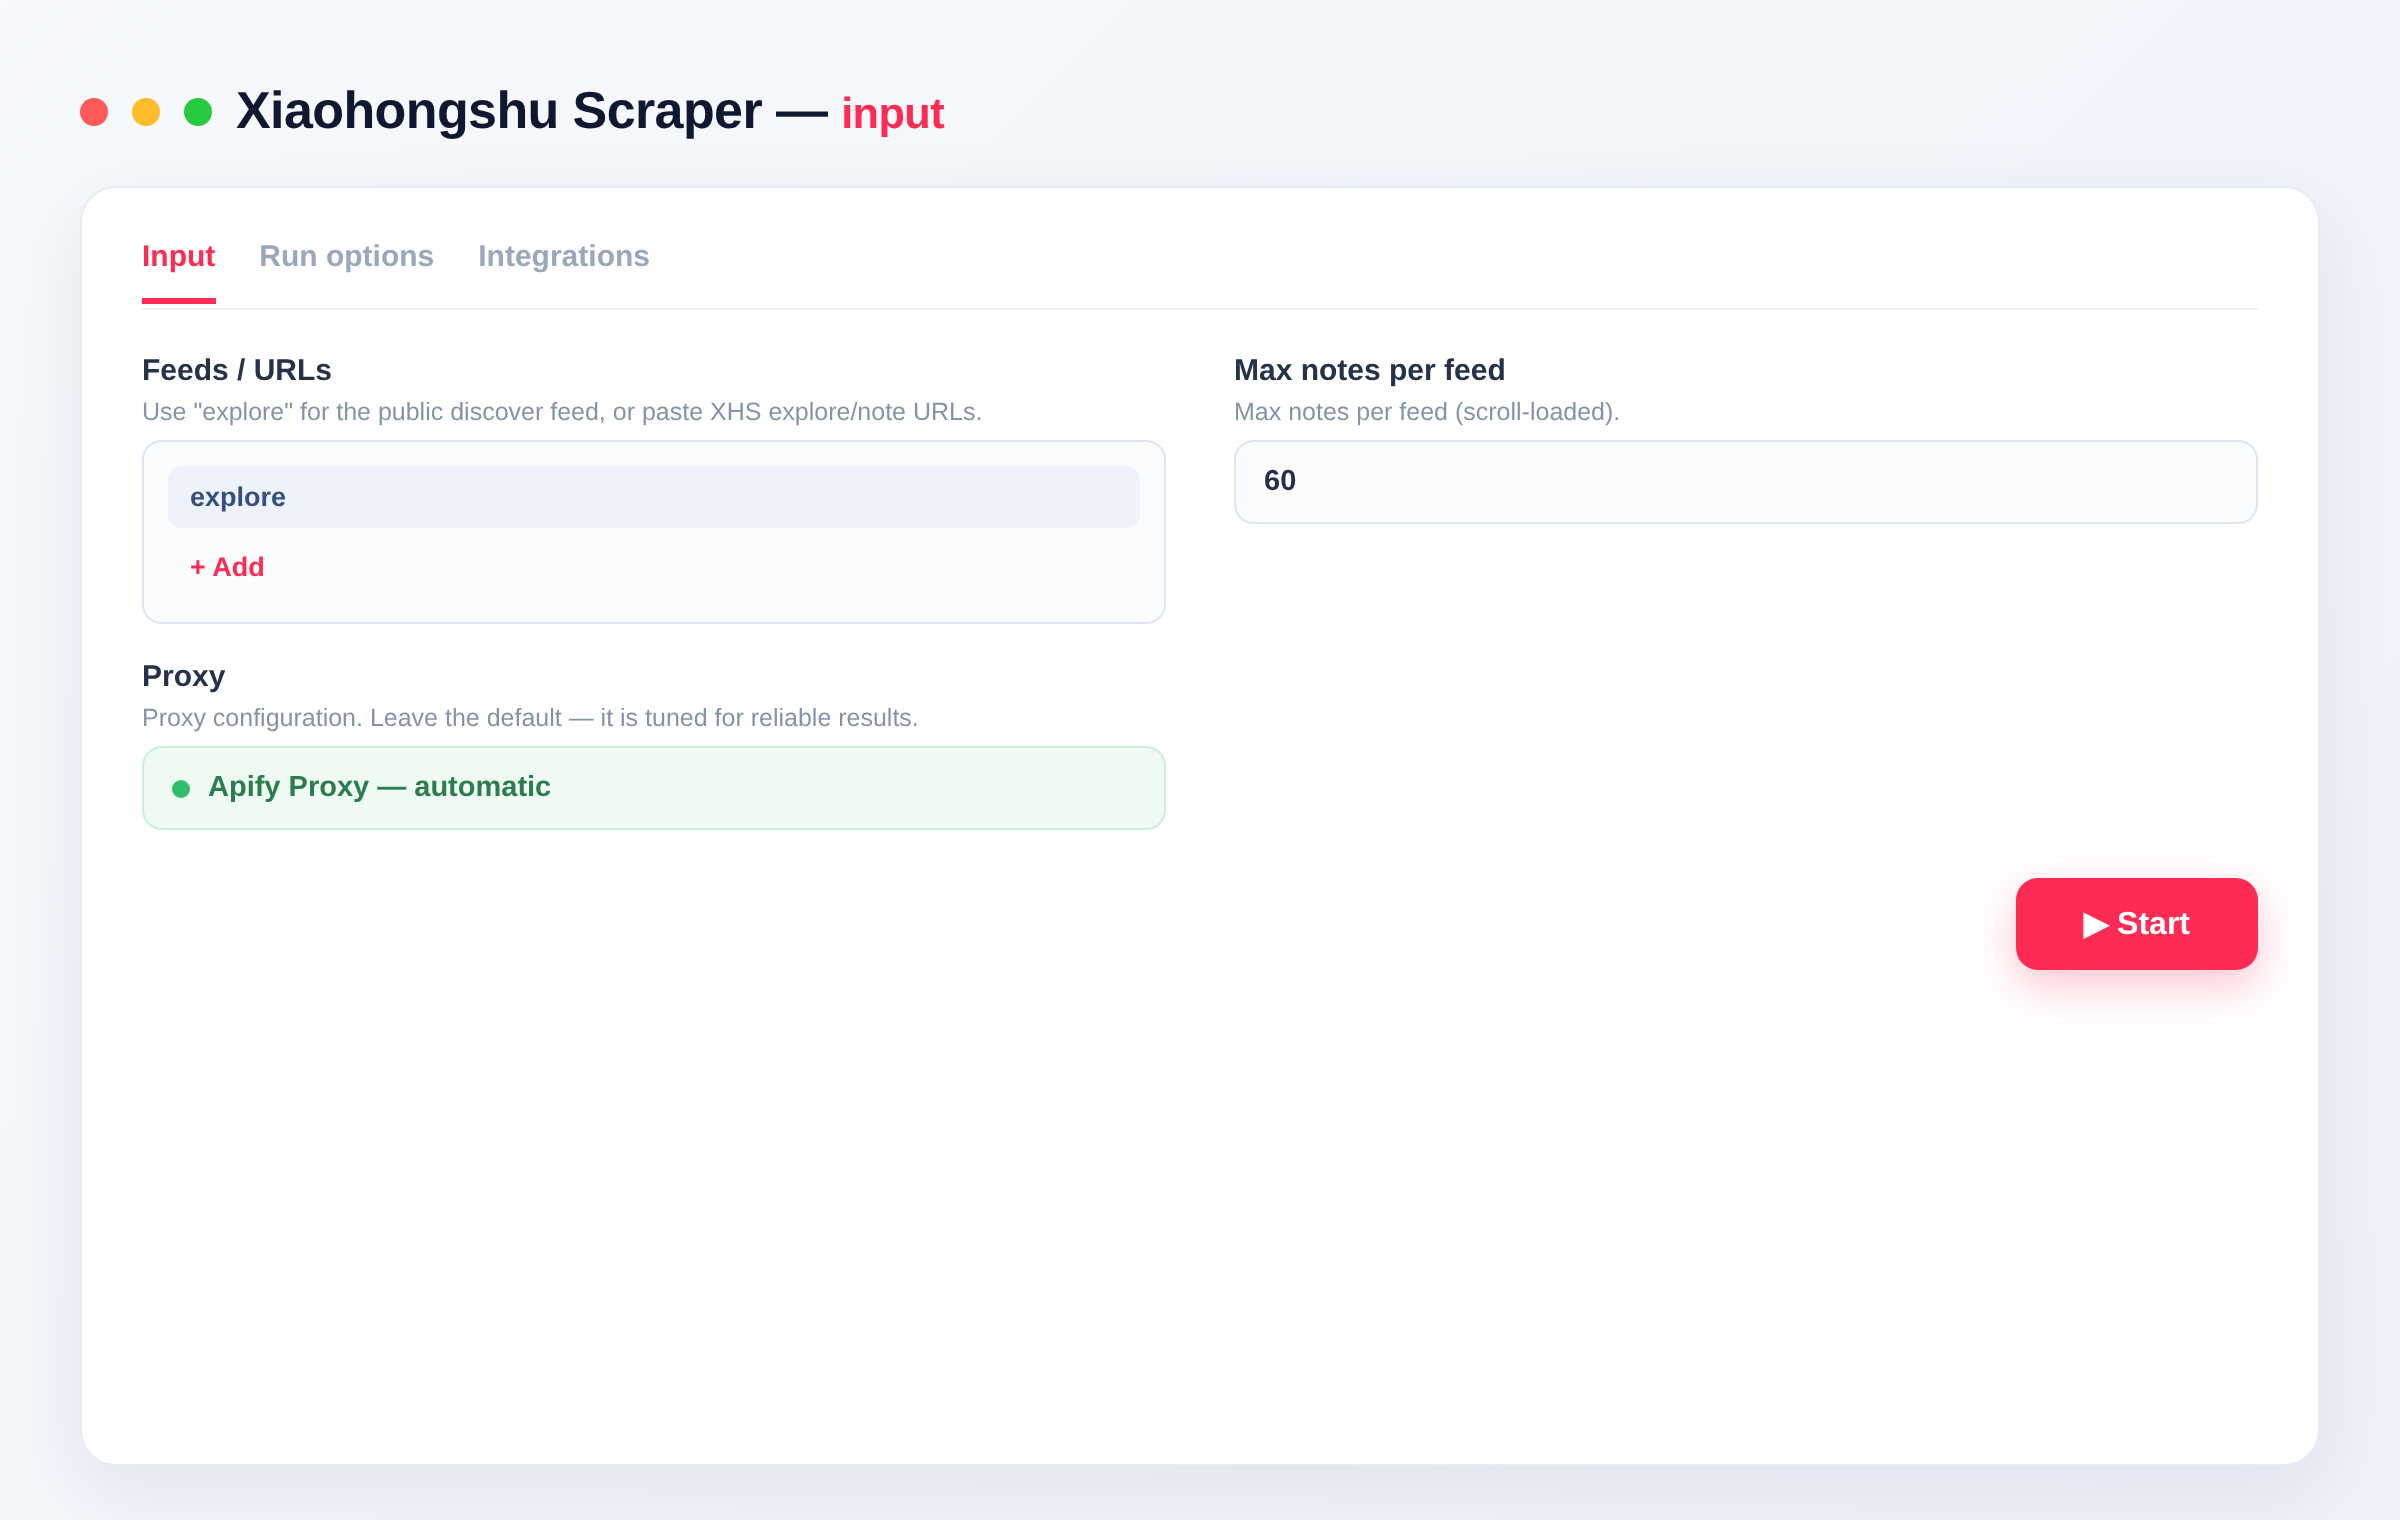
Provide the feed keyword explore and/or specific note URLs, then set a per-feed limit. No setup or account needed — just add your inputs.
{
  "channels": ["explore"],
  "maxItemsPerChannel": 60,
  "proxyConfiguration": { "useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"] }
}
| Field | Type | Description |
|---|---|---|
channels |
array | Use explore for the public discover feed, or paste one or more Xiaohongshu explore/note URLs. |
maxItemsPerChannel |
integer | Maximum notes to collect per feed (scroll-loaded). Default 60, up to 5000. |
proxyConfiguration |
object | Proxy settings. Leave the default — it is tuned for reliable results. |
Scrape the discover feed or specific notes
Keep channels set to explore to pull trending notes from the public discover feed, or paste exact note/explore URLs to target the notes you already know. Mix both in one run.
Set how many notes you collect
Use maxItemsPerChannel to cap the number of notes per feed. The Actor scroll-loads the feed until it reaches your limit or runs out of new notes.
Output
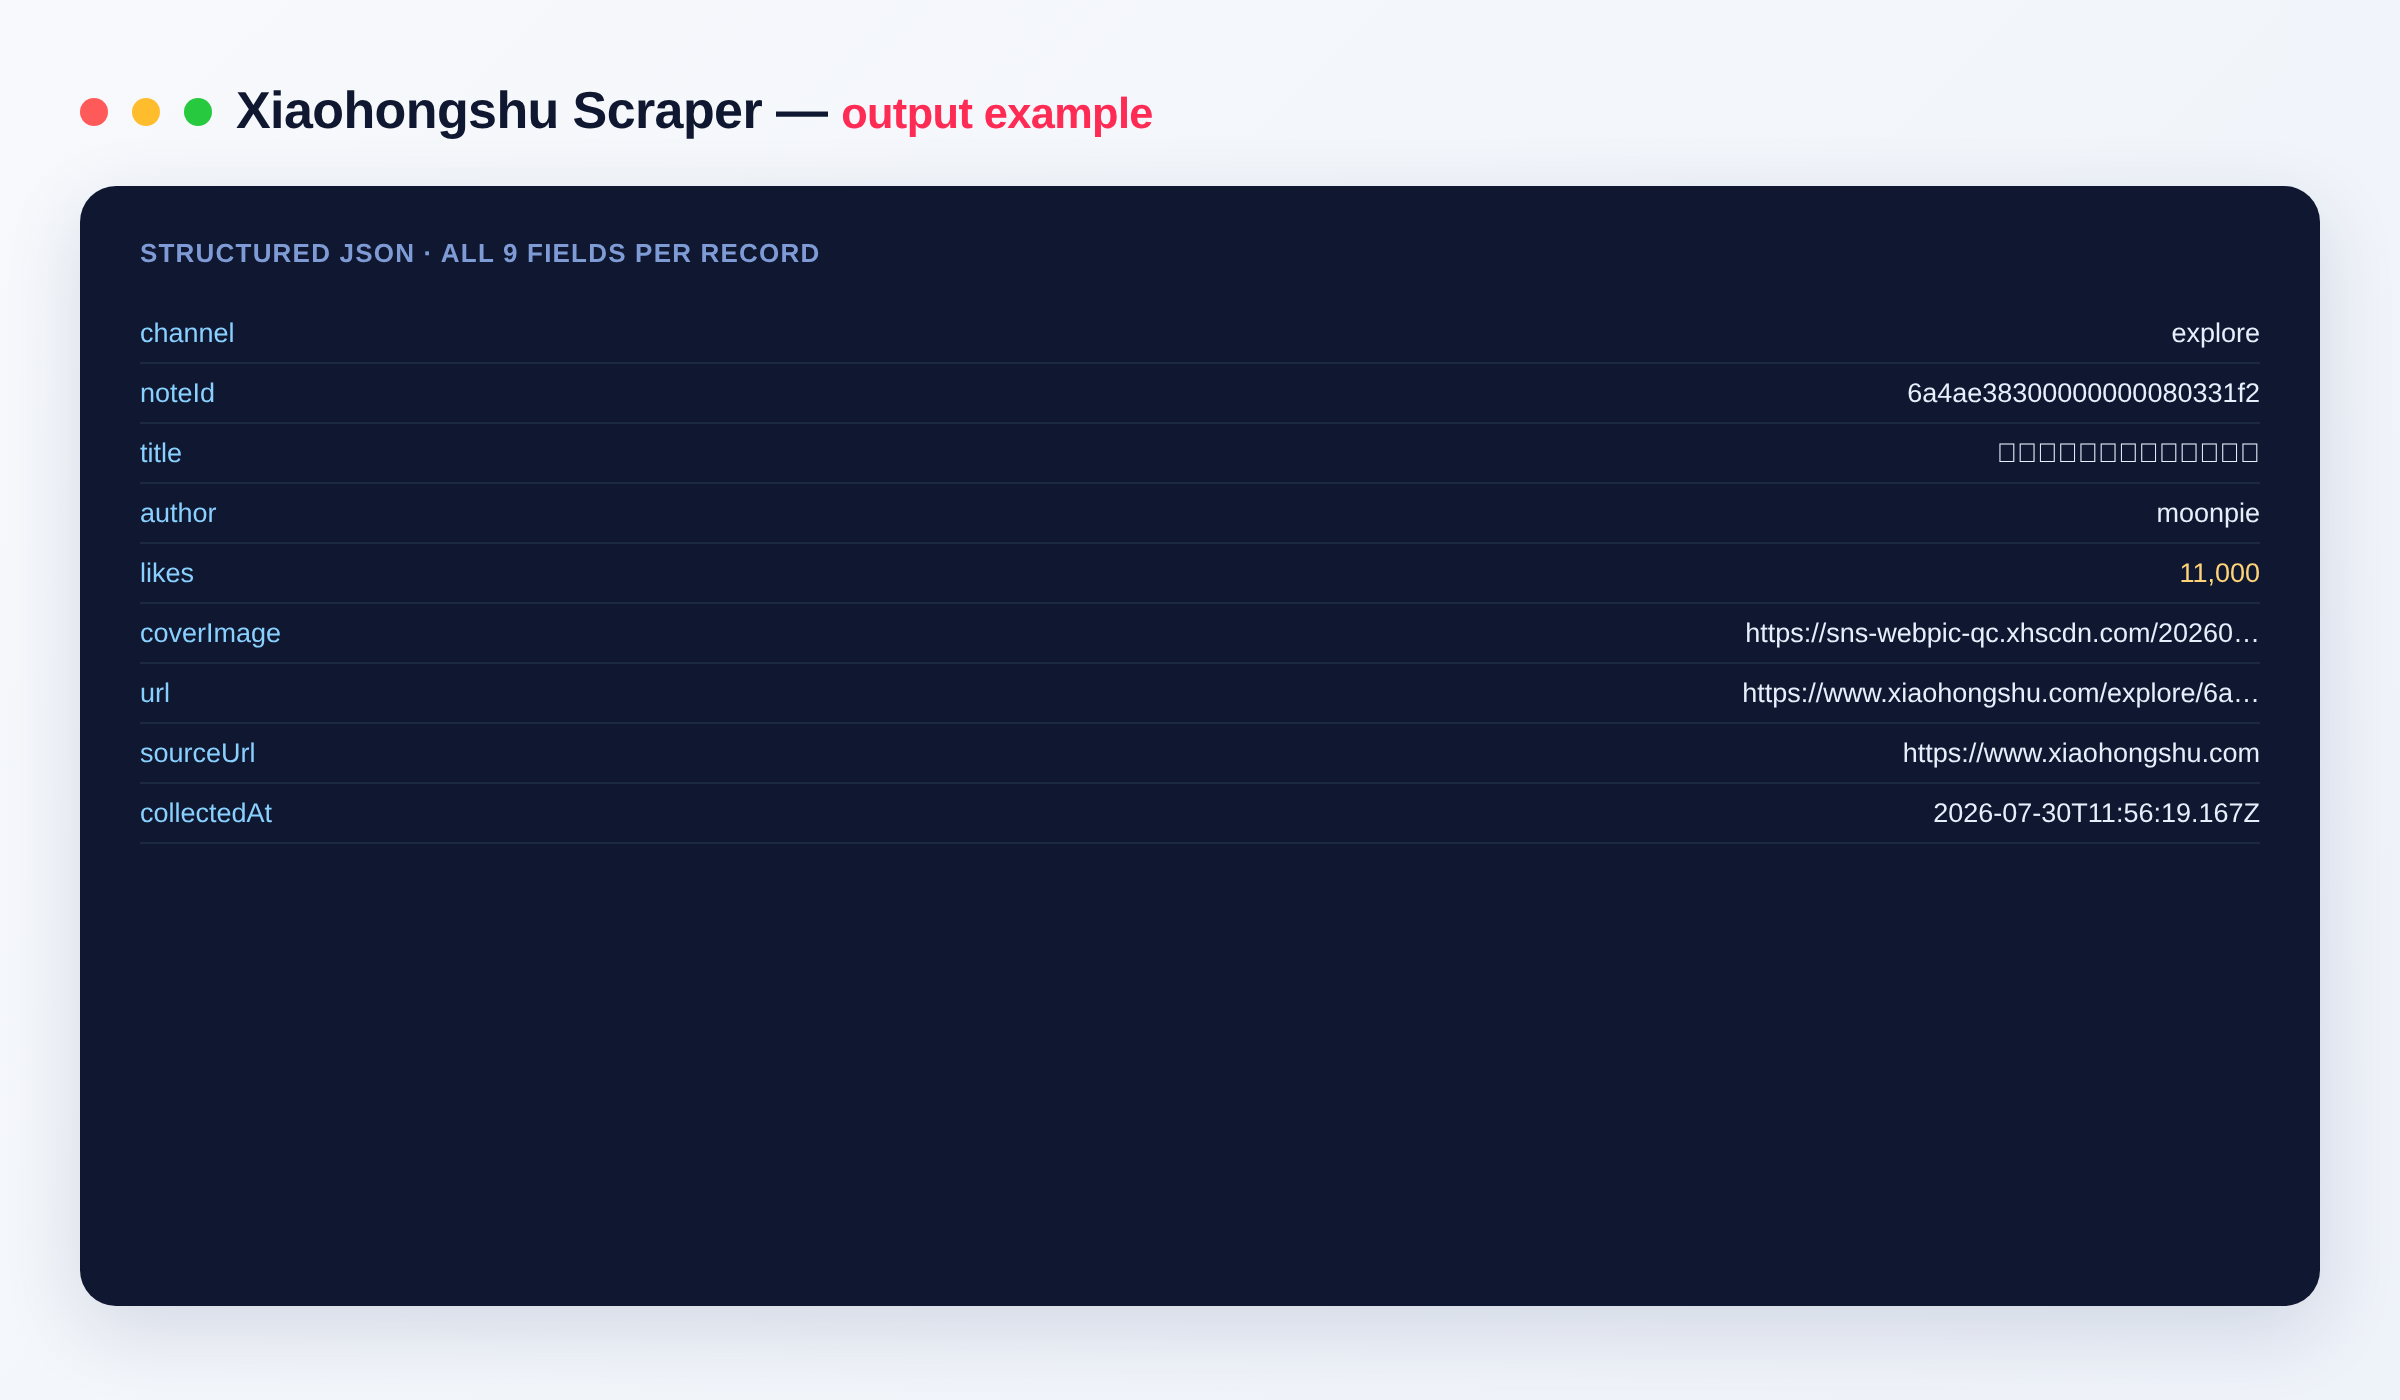
Each note is one dataset item:
{
  "channel": "explore",
  "noteId": "6a4f0800000000000f01d638",
  "title": "五级能耗一晚上一万块够不够",
  "author": "moonpie",
  "likes": 11000,
  "coverImage": "https://sns-webpic-qc.xhscdn.com/...",
  "url": "https://www.xiaohongshu.com/explore/6a4f08...?xsec_token=...",
  "sourceUrl": "https://www.xiaohongshu.com",
  "collectedAt": "2026-07-30T11:50:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
channel |
string | The feed or URL the note came from (for example explore). |
noteId |
string | Unique Xiaohongshu note ID. |
title |
string | Note title / caption text. |
author |
string | Display name of the note's author. |
likes |
integer | Like count, normalized from 万 shorthand to a plain integer. |
coverImage |
string (URL) | URL of the note's cover image. |
url |
string (URL) | Canonical URL of the note. |
sourceUrl |
string (URL) | The site the note was collected from. |
collectedAt |
string (ISO date) | Timestamp when the note was collected. |
Need more social & China data?
The Xiaohongshu Scraper pairs well with our other social and content scrapers — build a wider dataset across platforms:
- Weibo Scraper — posts, authors and engagement from Weibo.
- Bilibili Scraper — videos, creators and view counts.
- Douban Scraper — movies, books and ratings.
- Juejin Scraper — tech articles, authors and stats.
FAQ
Do I need a Xiaohongshu account or login? No. The Xiaohongshu Scraper needs no account and no login — it collects only public notes from the discover feed and note URLs. Just add your inputs and run.
How many notes can I scrape per run?
As many as you like. Set maxItemsPerChannel to control the count per feed (up to 5000), and pass multiple feeds or URLs in one run to scale up.
Do I need to write any code? No — this is a no-code tool. Add your inputs in the Apify Console, click Run, and download the data. Developers can also drive it via the Apify API.
What export formats are supported? JSON, CSV, Excel and XML, plus webhooks and the Apify API.
How does billing work? You pay per item you get, so it stays one of the cheapest ways to collect Xiaohongshu data — no monthly fees, no wasted credits.
How fresh is the data?
Every run collects live notes from the public feed at that moment, each stamped with a collectedAt time. Re-run any time (or on a schedule) for fresh data.
Can I automate or integrate the Xiaohongshu Scraper? Yes. The Xiaohongshu Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification, or kick off another process such as loading your data downstream.
Is scraping Xiaohongshu legal? The Actor collects only public data. You are responsible for how you use it and for complying with Xiaohongshu's terms and applicable laws.
Notes
Original clean-room implementation. Collects only public Xiaohongshu (RedNote) data; you are responsible for how you use the data and for complying with Xiaohongshu's terms. This is an independent tool and is not affiliated with or endorsed by Xiaohongshu.
Input
| Field | Type | Description |
|---|---|---|
channelsFeeds / URLs | array | Use "explore" for the public discover feed, or paste XHS explore/note URLs. Default: ["explore"] |
maxItemsPerChannelMax notes per feed | integer | Max notes per feed (scroll-loaded). Default: 60 |
proxyConfigurationProxy | object | Proxy configuration. Leave the default — it is tuned for reliable results. Default: {"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~xiaohongshu-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "channels": [
    "explore"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/xiaohongshu-scraper").call(run_input={
"channels": [
"explore"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/xiaohongshu-scraper').call({
"channels": [
"explore"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Note scraped One Xiaohongshu note scraped. | $0.004 | $0.004 |
| Feed loaded One feed loaded in a residential browser. | $0.01 | $0.01 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Carousell Scraper
Scrape Carousell search listings: title, price, condition, location, seller, photo and URL. Requires your own Carousell app token.
242 runs · 2 users · $0.003 / listing scraped
Google Flights Scraper
Scrape flight options from Google Flights by route and date: airline, flight number, departure and arrival times, duration, stops, layovers and price. One-way or round-trip, any cabin and currency. For travel and price monitoring.
216 runs · 4 users · $0.004 / flight scraped
Pinterest Scraper
Search Pinterest and scrape pins (title, description, destination link, image, pinner, board, saves), boards and users. Fast. For visual research, e-commerce, trend and marketing analysis.
151 runs · 2 users · $0.0034 / item scraped
Google Trends Scraper
Scrape Google Trends for any keyword: interest over time, related and rising queries, and interest by region. Per country and timeframe. For SEO, market and trend research. No setup.
139 runs · 6 users · $0.001 / keyword scraped
AliExpress Product Search Scraper
Search AliExpress by keyword and export one clean row per product — title, sale price, original price, image and product URL. Export to JSON, CSV or Excel.
135 runs · 3 users · $0.003 / product scraped
Google Maps Scraper
Search Google Maps and scrape places: name, category, full address, city, coordinates, rating, phone, website, Place ID and map link. Fast browser-free via Google's internal endpoint, no setup. For local lead generation and market research.
130 runs · 2 users · $0.005 / place scrapedSend the site and the fields. We build it and you get it first.