IT之家 Scraper
hipersoft/ithome-scraper
Scrape IT之家 (ithome.com) tech news across channels: title, summary, views, comments, keywords, image and URL. Android, Apple, Windows, digital, games, AI and more.
Total users
1Monthly users
0Total runs
90Per article scraped
$0.001Last rebuilt
Oct 26, 2026Overview
Scrape IT Home (IT之家, ithome.com) — one of China's biggest consumer-tech news sites — into clean JSON, CSV, Excel or XML. This IT Home scraper extracts article titles, summaries, view counts, comment counts, keyword tags, cover images, posted dates and URLs across the Top News, Android, Digital and Games channels — all from one Actor, no code and no login required. A fast, cheap, no-code way to turn ITHome's front pages into a structured tech-news dataset.
Perfect for China tech-news monitoring, product-launch tracking, trend research, price-drop alerts and media intelligence — and one of the cheapest ways to do it, since you pay only per article you get.
What does the IT Home Scraper do?
The IT Home Scraper crawls and extracts public news data from IT之家 (ithome.com) by channel. Pick any mix of the Top News, Android, Digital and Games channels, set how many articles you want, and it returns structured data points — title, summary, views, comments, keywords, image, posted date and canonical URL — ready for analytics, dashboards, datasets, LLM pipelines or trend research. It's a no-code crawler and extractor for Chinese consumer-tech coverage, with no API key to manage.
What data can you scrape from IT Home?
| Group | Fields |
|---|---|
| 📰 Article | id, title, description/summary, canonical URL, cover image |
| 📊 Engagement | view count (阅读), comment count per article |
| 🏷️ Tags | keyword tags attached to the article |
| 🔀 Channel | source channel — Top News (资讯), Android (安卓), Digital (数码), Games (游戏) |
| 🕒 Timestamps | posted date, collected-at timestamp |
Use cases
- Tech-news monitoring — track new coverage across IT之家's Top News, Android, Digital and Games channels in near real time.
- Product-launch & rumor tracking — catch phone, chip and gadget announcements as soon as they hit the front page.
- Trend & topic research — mine keyword tags, views and comments to see what Chinese tech readers care about.
- Build a tech-news dataset — thousands of articles with engagement stats for analytics, BI or model training.
- LLM & RAG pipelines — feed clean summaries and metadata into knowledge bases and summarization workflows.
- Competitive & market intelligence — watch how brands and products are covered and how much engagement they pull.
- Content curation & newsletters — pull the most-read stories per channel to power a digest.
- Price & deal tracking — surface pricing and pre-order stories the moment they publish.
How to scrape IT Home data
- Click Try for free / Start to open the IT Home Scraper.
- Choose the channels you want — Top News, Android, Digital and/or Games.
- Set Max articles to cap how many results you collect across all selected channels.
- Click Run.
- Download the results as JSON, CSV, Excel or XML, or pull them from the API.
Input
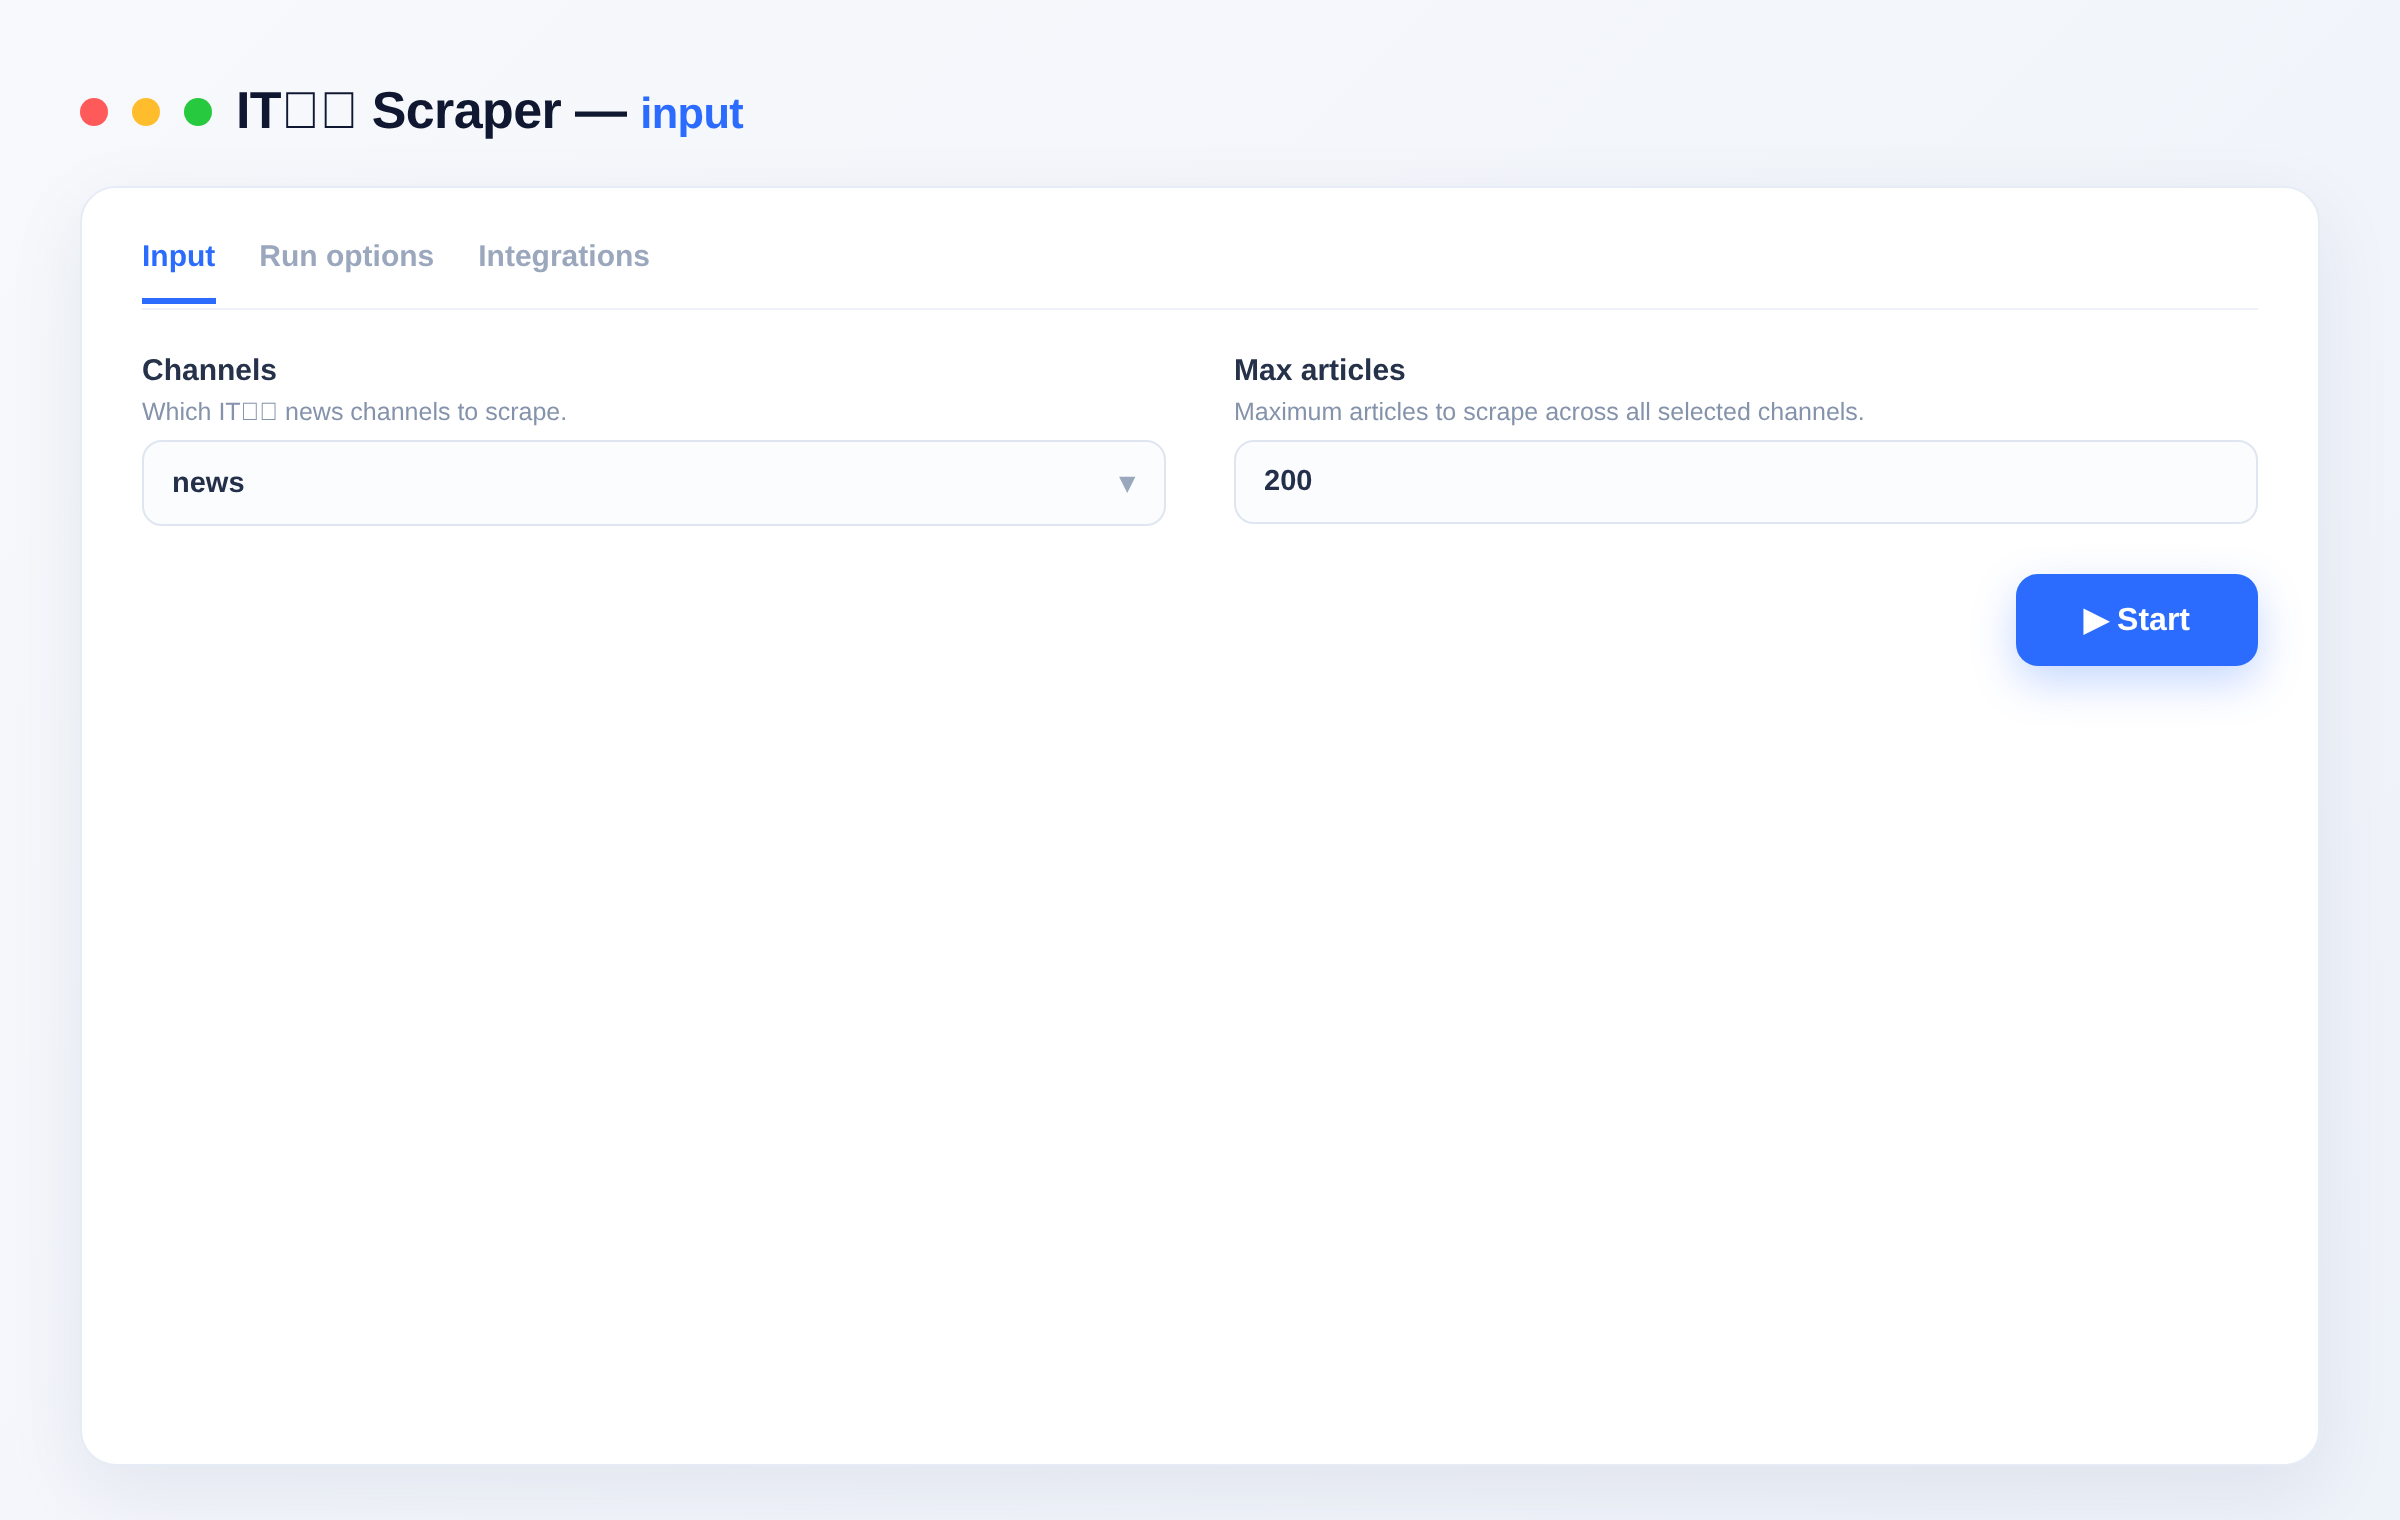
Pick one or more channels and a limit — that's it. No code, no login, no setup.
{
  "channels": ["news", "android", "digi", "game"],
  "maxItems": 200
}
| Field | Type | Description |
|---|---|---|
channels |
array | Which IT之家 channels to scrape. Options: news (Top News 资讯), android (Android 安卓), digi (Digital 数码), game (Games 游戏). Pass any combination. |
maxItems |
integer | Maximum number of articles to collect across all selected channels (default 200). |
Choose your channels
Select any mix of the four channels — news, android, digi, game. Each maps to an IT之家 section, and articles are tagged with the channel they came from so you can filter or split the dataset later.
Set how many articles you get
Use maxItems to control run size and cost. Since you pay per article, a smaller limit is a cheap way to sample a channel before scaling up to a full dataset.
Output
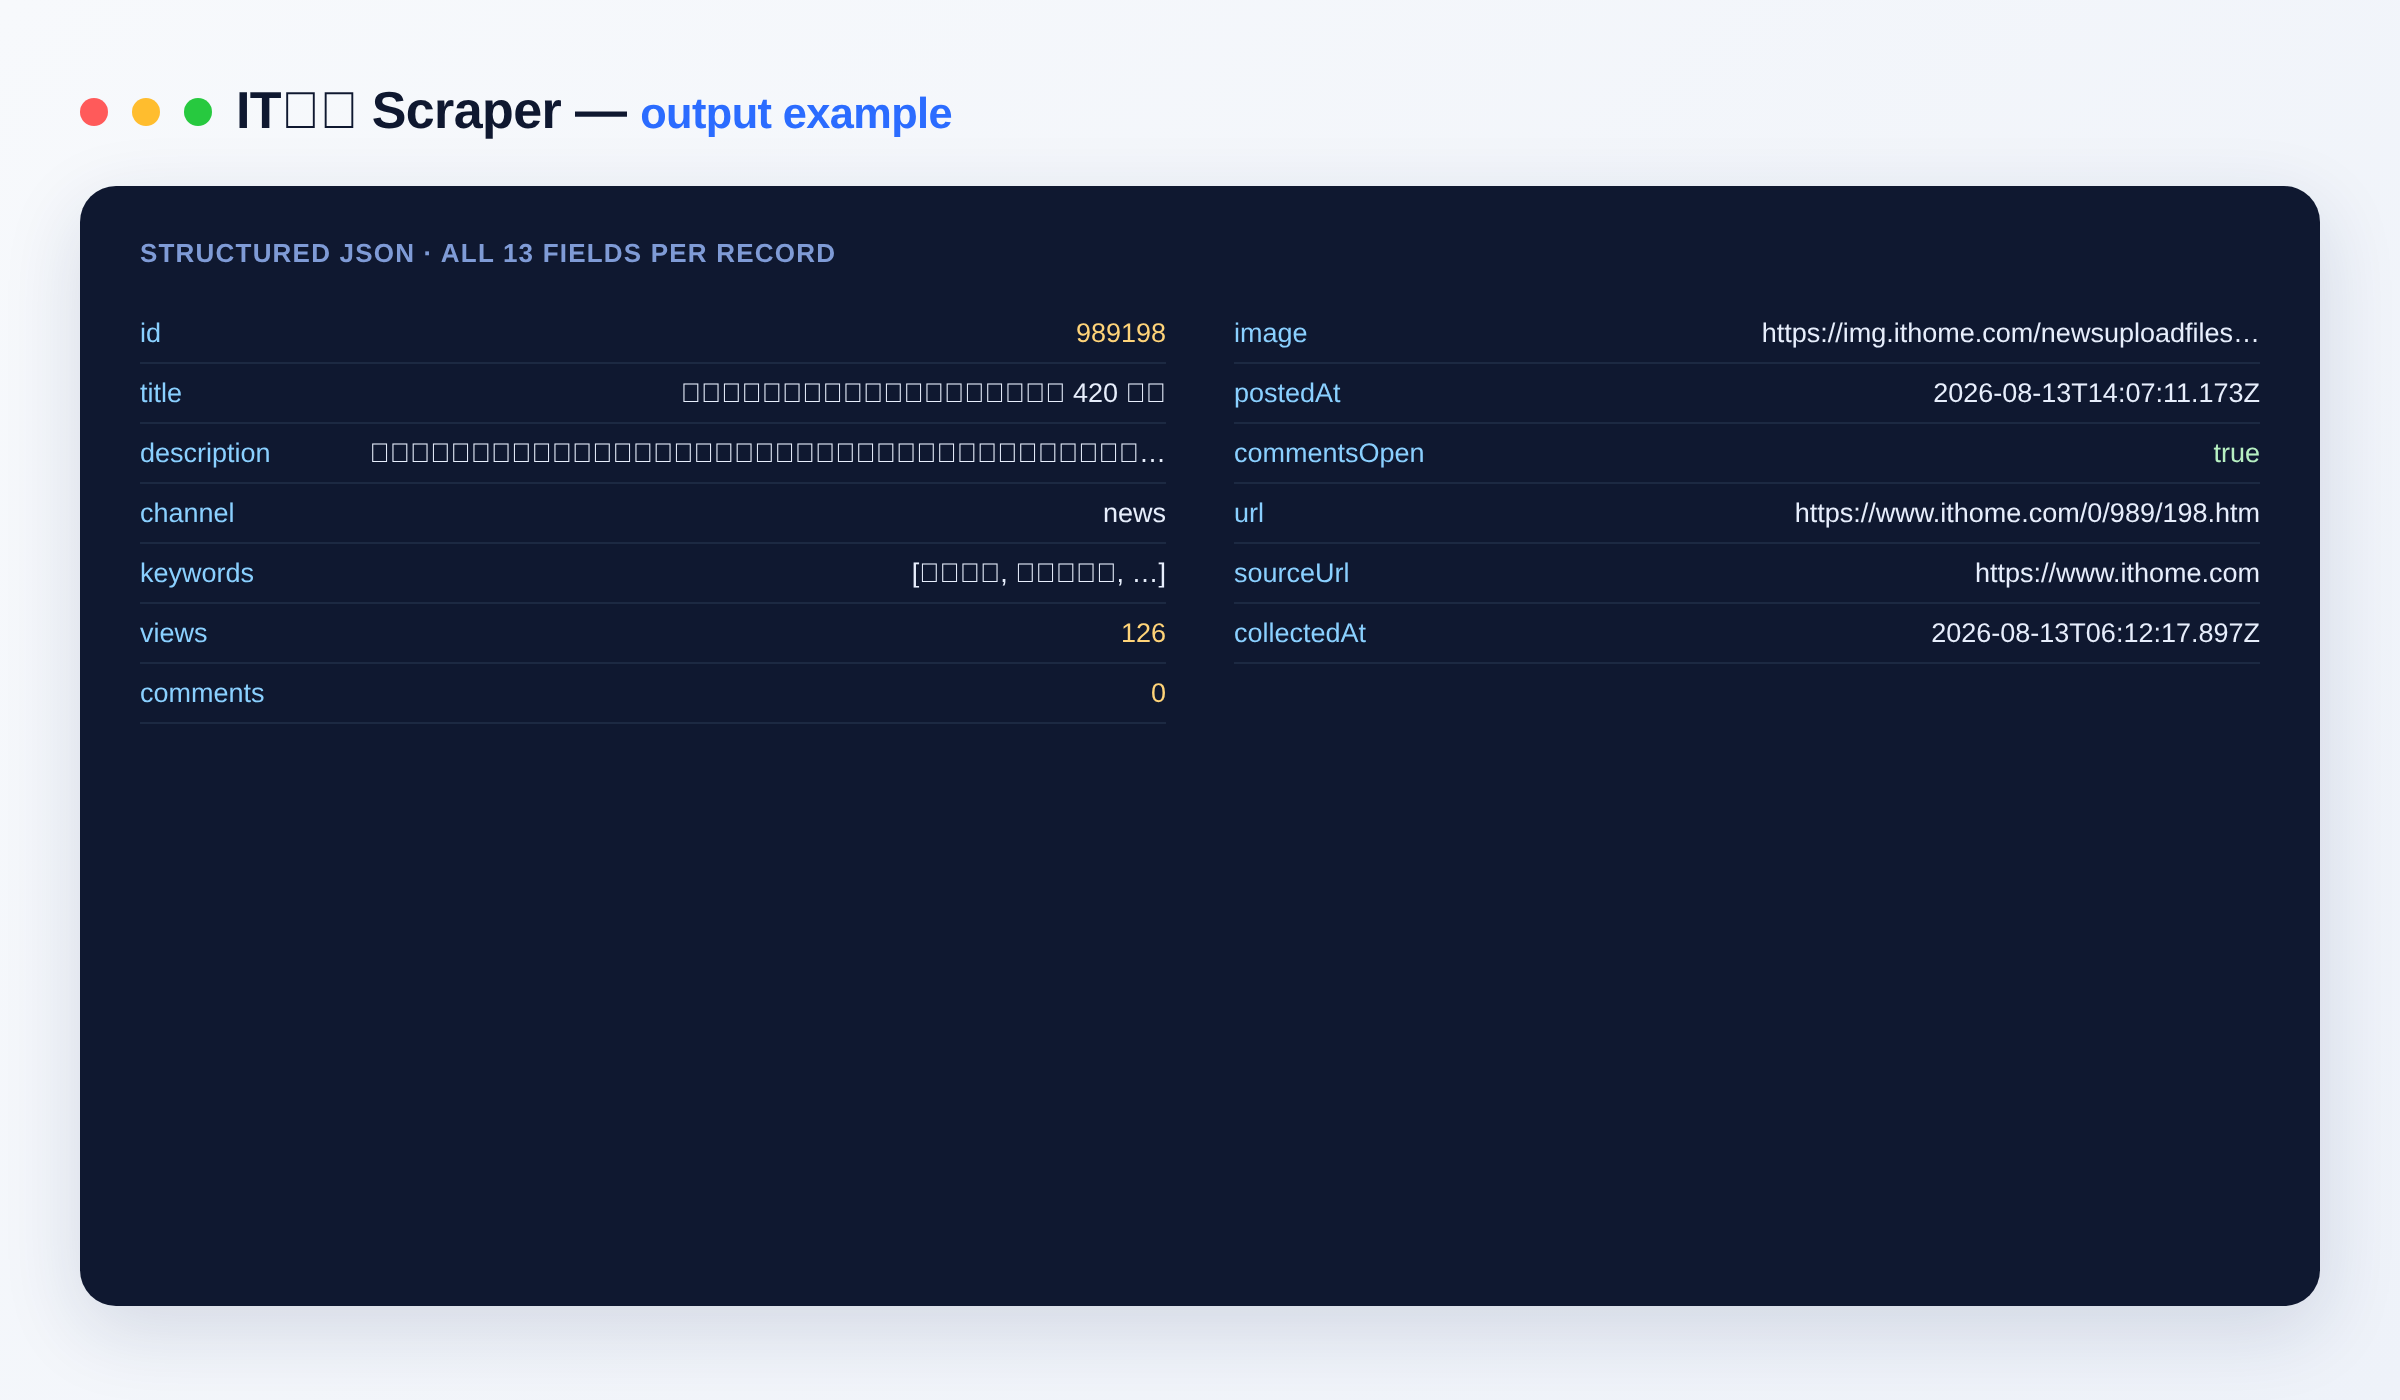
Each article is one dataset item:
{
  "id": 983883,
  "title": "25.99 万元!小米澎程 N70 Max 预售价格公布",
  "description": "……",
  "channel": "news",
  "keywords": ["闪讯"],
  "views": 2081,
  "comments": 0,
  "image": "https://img.ithome.com/newsuploadfiles/thumbnail/....jpg",
  "postedAt": "2026-07-30T18:51:05.443Z",
  "url": "https://www.ithome.com/0/983/883.htm",
  "collectedAt": "2026-07-30T12:00:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
id |
integer | Unique IT之家 article ID. |
title |
string | Article headline. |
description |
string | Article summary / lead text. |
channel |
string | Source channel — news, android, digi or game. |
keywords |
array | Keyword tags attached to the article. |
views |
integer | View count (阅读) for the article. |
comments |
integer | Number of comments on the article. |
image |
string (URL) | Cover / thumbnail image URL. |
postedAt |
string (ISO date) | When the article was published. |
url |
string (URL) | Canonical article URL on ithome.com. |
collectedAt |
string (ISO date) | When this record was collected. |
Need more Chinese tech & community data?
Building a wider China tech dataset? Pair the IT Home Scraper with our other scrapers:
- Bilibili Scraper — videos, channels and stats from China's biggest video community.
- SSPAI Scraper — apps, gear and productivity articles from 少数派.
- Juejin Scraper — developer articles, tags and engagement from 掘金.
- Guokr Scraper — science and tech explainers from 果壳.
FAQ
Do I need an API key or login to scrape IT Home? No. There's no setup, no key and no login — just pick your channels, set a limit and run.
How many articles can I scrape per run?
As many as you like. Use maxItems to cap results across all selected channels, and scale up to thousands when you need a full dataset.
Which channels can I scrape?
Top News (资讯), Android (安卓), Digital (数码) and Games (游戏). Select any combination in the channels input.
How does billing work?
You pay per article you collect, so cost scales with your maxItems and channel selection — one of the cheapest ways to build a China tech-news dataset.
What export formats are supported? JSON, CSV, Excel and XML, plus webhooks and the Apify API.
How fresh is the data?
Each run pulls the latest articles currently published on the selected IT之家 channels, with a postedAt date and a collectedAt timestamp on every item.
Can I filter by channel?
Yes — choose exactly the channels you want in the input, and every item is tagged with its source channel so you can split or filter the dataset afterward.
Can I automate or integrate the IT Home Scraper? Yes. The IT Home Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification, or kick off another process such as loading your data downstream.
Is scraping IT Home legal? The Actor collects only public data. You are responsible for how you use it and for complying with IT之家's terms and applicable laws.
Notes
Original clean-room implementation. Returns only public data; you are responsible for how you use the data and for complying with IT之家's terms. This is an independent tool and is not affiliated with or endorsed by IT Home (IT之家 / ithome.com).
Input
| Field | Type | Description |
|---|---|---|
channelsChannels | array | Which IT之家 news channels to scrape. Default: ["news"] |
maxItemsMax articles | integer | Maximum articles to scrape across all selected channels. Default: 200 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~ithome-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/ithome-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/ithome-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Article scraped One IT之家 news article scraped with stats. | $0.001 | $0.001 |
| API request One IT之家 channel API request. | $0.0008 | $0.0008 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Dribbble Shots Scraper
Scrape public design shots from Dribbble: title, high-res image, tags, likes, views and designer credit. Filter by category or sort, export JSON, CSV or Excel.
359 runs · 5 users · $0.003 / shot scraped
Computrabajo Scraper
Scrape Computrabajo job listings across Latin America (Mexico, Colombia, Argentina, Chile, Peru and more): title, company, location, salary, posted date and apply URL. Filter by country and keyword. No setup.
206 runs · 4 users · $0.002 / listing scraped
Kraken Market Data Scraper
Fetch Kraken spot market data in bulk: ticker stats (ask, bid, last, 24h high/low/volume/vwap), OHLC candles for any interval, order book depth (top bids/asks), and tradable pair metadata. Fast, clean and cheap.
165 runs · 4 users · $0.001 / pair scraped
Bayt Scraper
Scrape Bayt.com job listings across the Middle East (UAE, Saudi Arabia, Egypt, Qatar and more): title, company, location, posted date and apply URL. Filter by country and keyword.
134 runs · 4 users · $0.003 / job scraped
GitHub Scraper
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos). Uses the GitHub REST API; optional token for higher rate limits. For developer lead generation, OSS research and recruiting.
131 runs · 7 users · $0.0008 / item scraped
Hacker News Scraper
Scrape Hacker News stories, comments, Ask HN, Show HN, jobs and polls by keyword, points, comments and date range. Sort by relevance or newest. Title, URL, author, points, comment count, text and HN link. Fast clean HTTP via the HN Algolia API, no setup.
130 runs · 2 users · $0.004 / item scrapedSend the site and the fields. We build it and you get it first.