npm Package Scraper
hipersoft/npm-scraper
Search the npm registry or look up exact packages and get name, version, description, keywords, license, author, maintainers, dependencies, repository, and monthly/weekly download counts.
Total users
2Monthly users
1Total runs
120Per package scraped
$0.0015Last rebuilt
Oct 26, 2026Overview
Search the npm registry or look up exact packages and get back clean, structured JSON: version, description, keywords, license, author, maintainers, dependencies, repository and homepage links, package size, and day/week/month download counts plus npms.io quality scores. It pulls from the official npm registry public API — no account, no API key. Built for JavaScript developers, dependency and license auditors, and OSS researchers who need dependable package data at scale.
Features
- 🔎 Free-text search — run any npm query (
web scraping,react state management) and collect matching packages in bulk. - 🎯 Exact lookups — pass precise names, including scoped packages like
@apify/storage, alongside search results. - 📈 Download counts — fetch downloads for the last day, week or month per package.
- 📦 Full metadata — optional manifest fetch adds
dependencies,repositoryUrl,homepage,unpackedSizeandfileCount. - ⭐ Quality signals — capture npms.io
score,scoreQuality,scorePopularityandscoreMaintenancefrom search. - 👥 People & licensing —
author,maintainersandlicensefor compliance and outreach. - ⚙️ Reliable by design — bulk download calls, chunked pushing and retry-with-backoff keep large runs stable.
What you get
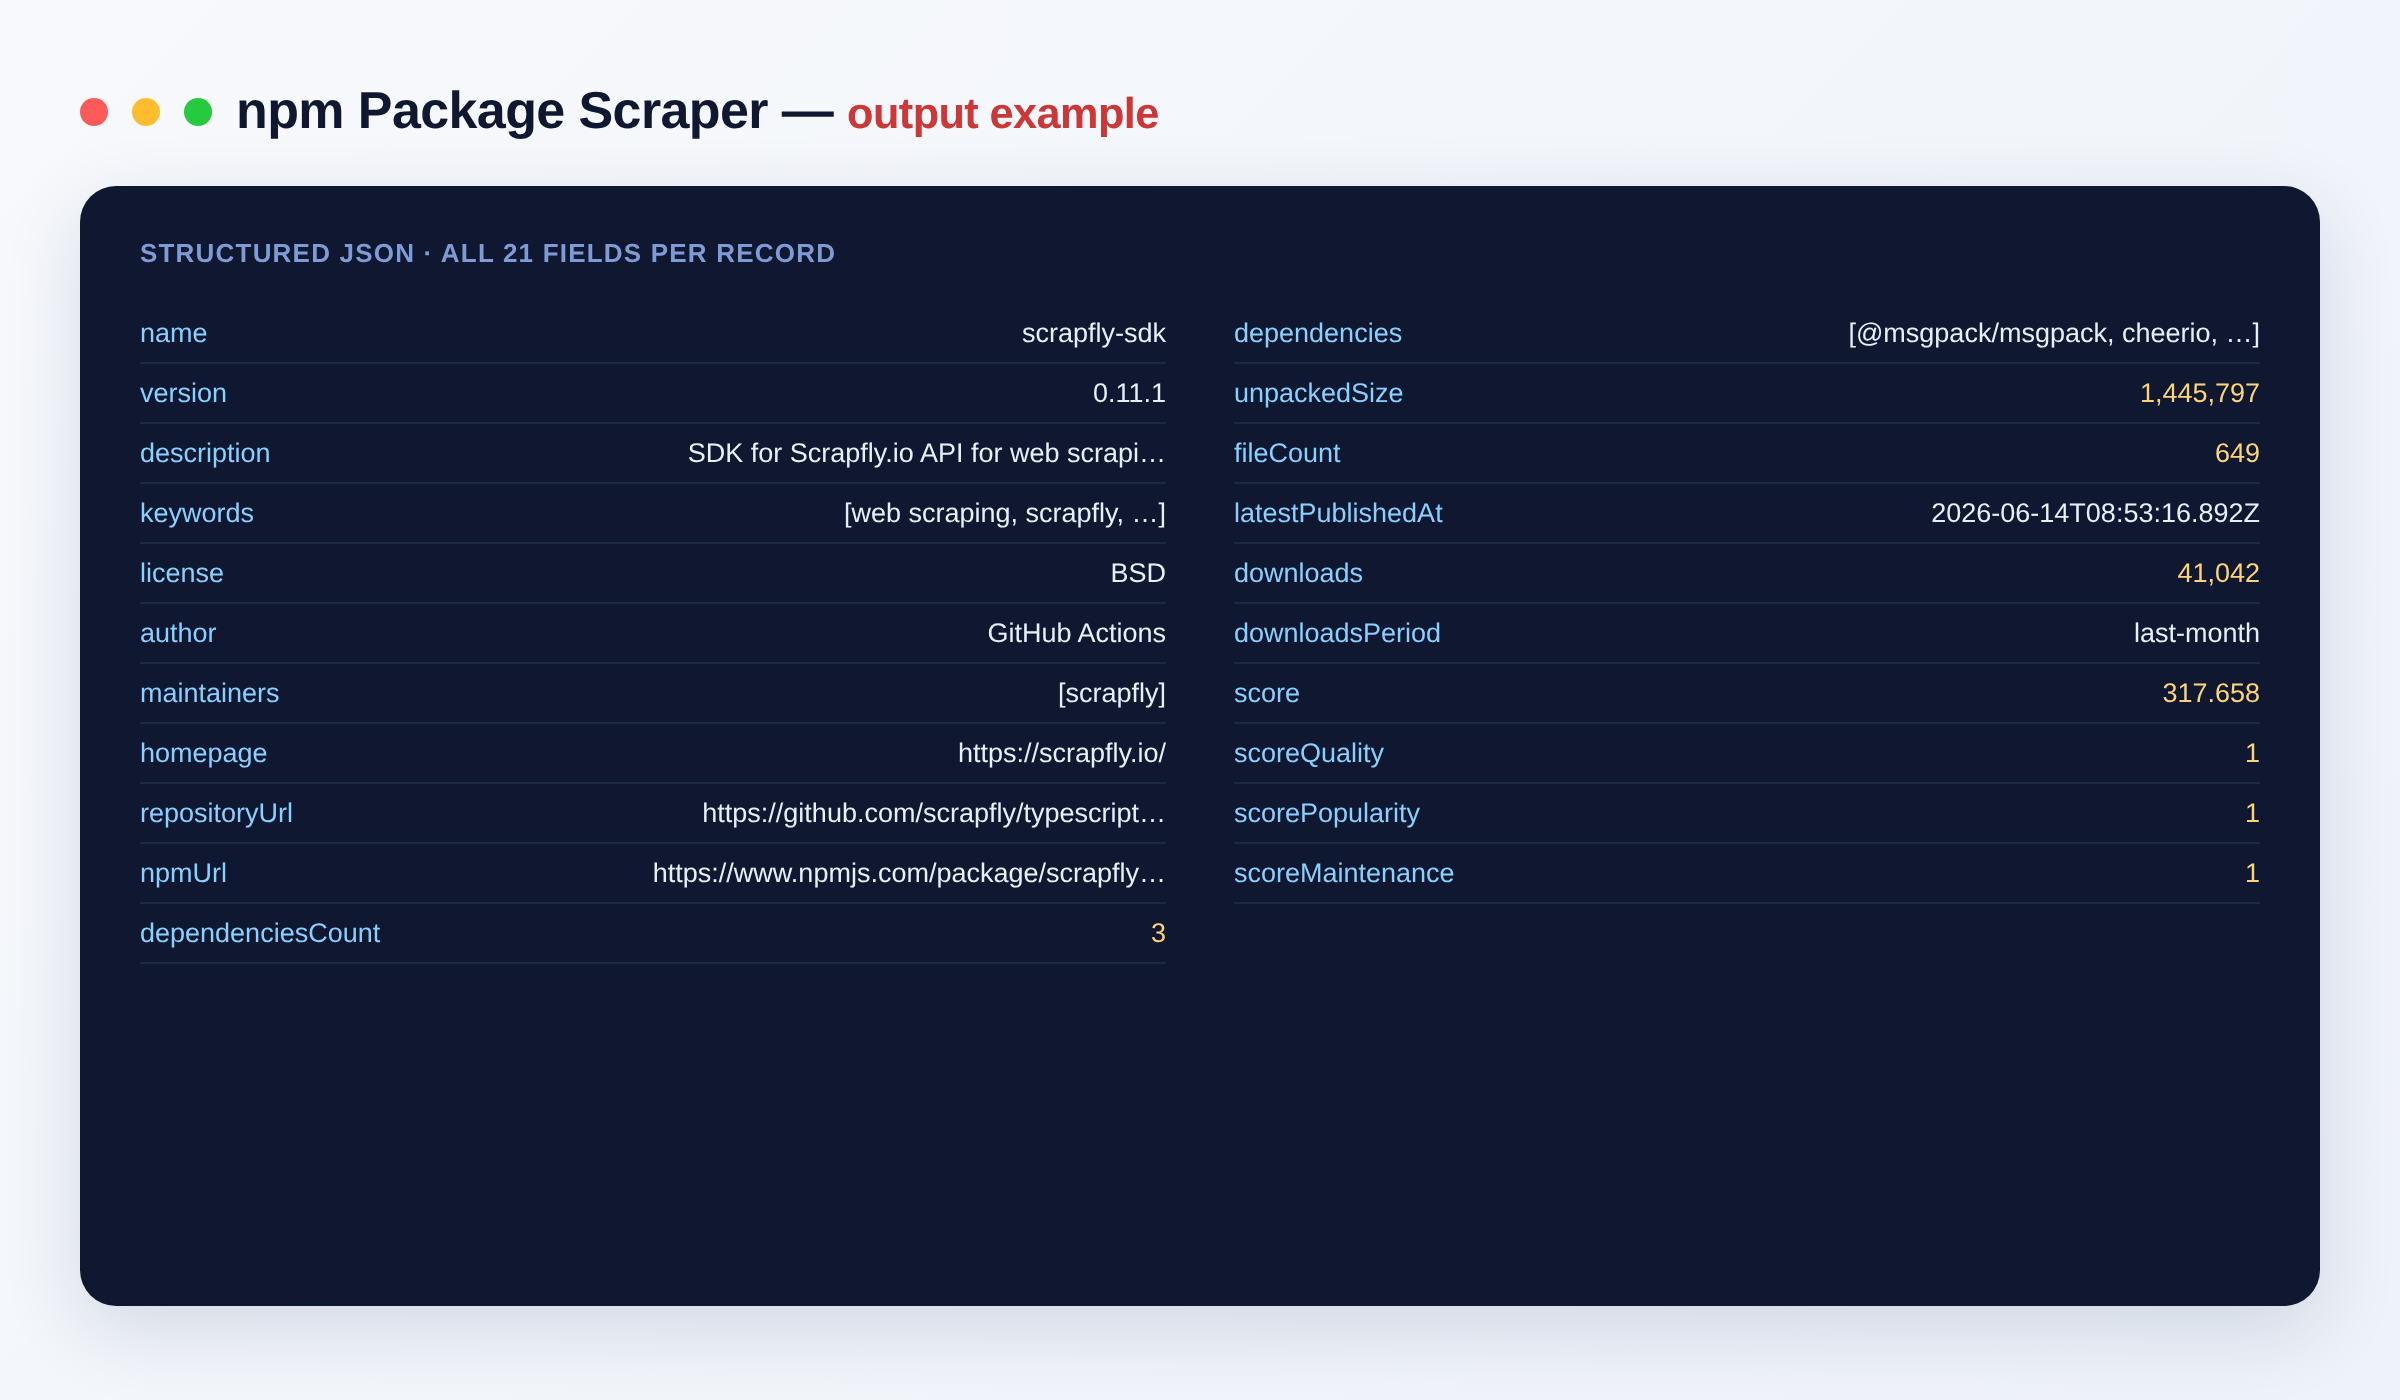
Each package becomes one clean JSON record:
{
  "name": "cheerio",
  "version": "1.0.0",
  "description": "The fast, flexible, and elegant library for parsing and manipulating HTML and XML.",
  "keywords": ["html", "parser", "jquery", "scraper"],
  "license": "MIT",
  "author": "The Cheerio contributors",
  "maintainers": ["feedic", "jugglinmike"],
  "homepage": "https://cheerio.js.org/",
  "repositoryUrl": "https://github.com/cheeriojs/cheerio",
  "npmUrl": "https://www.npmjs.com/package/cheerio",
  "dependenciesCount": 6,
  "dependencies": ["cheerio-select", "dom-serializer", "domhandler", "htmlparser2", "parse5", "parse5-htmlparser2-tree-adapter"],
  "unpackedSize": 143210,
  "fileCount": 34,
  "latestPublishedAt": "2024-02-01T10:23:11.000Z",
  "downloads": 78345612,
  "downloadsPeriod": "last-month",
  "score": 0.91,
  "scoreQuality": 0.95,
  "scorePopularity": 0.88,
  "scoreMaintenance": 0.93
}
Output schema
| Field | Type | Description |
|---|---|---|
name |
string | Package name on npm. |
version |
string | Latest published version of the package. |
description |
string | Short package description from its manifest. |
keywords |
array | Keyword tags declared by the package. |
license |
string | License identifier, e.g. MIT. |
author |
string | Package author name. |
maintainers |
array | npm usernames of the package maintainers. |
homepage |
string (URL) | Project homepage link. |
repositoryUrl |
string (URL) | Source code repository link. |
npmUrl |
string (URL) | Package page on npmjs.com. |
dependenciesCount |
integer | Number of runtime dependencies. |
dependencies |
array | Names of the runtime dependency packages. |
unpackedSize |
integer | Installed size of the package in bytes. |
fileCount |
integer | Number of files in the published package. |
latestPublishedAt |
string (ISO date) | Publish timestamp of the latest version. |
downloads |
integer | Download count for the selected period. |
downloadsPeriod |
string | Time window the download count covers (last-day, last-week or last-month). |
score |
number | Overall npms.io quality score (0–1). |
scoreQuality |
integer | npms.io quality sub-score. |
scorePopularity |
integer | npms.io popularity sub-score. |
scoreMaintenance |
integer | npms.io maintenance sub-score. |
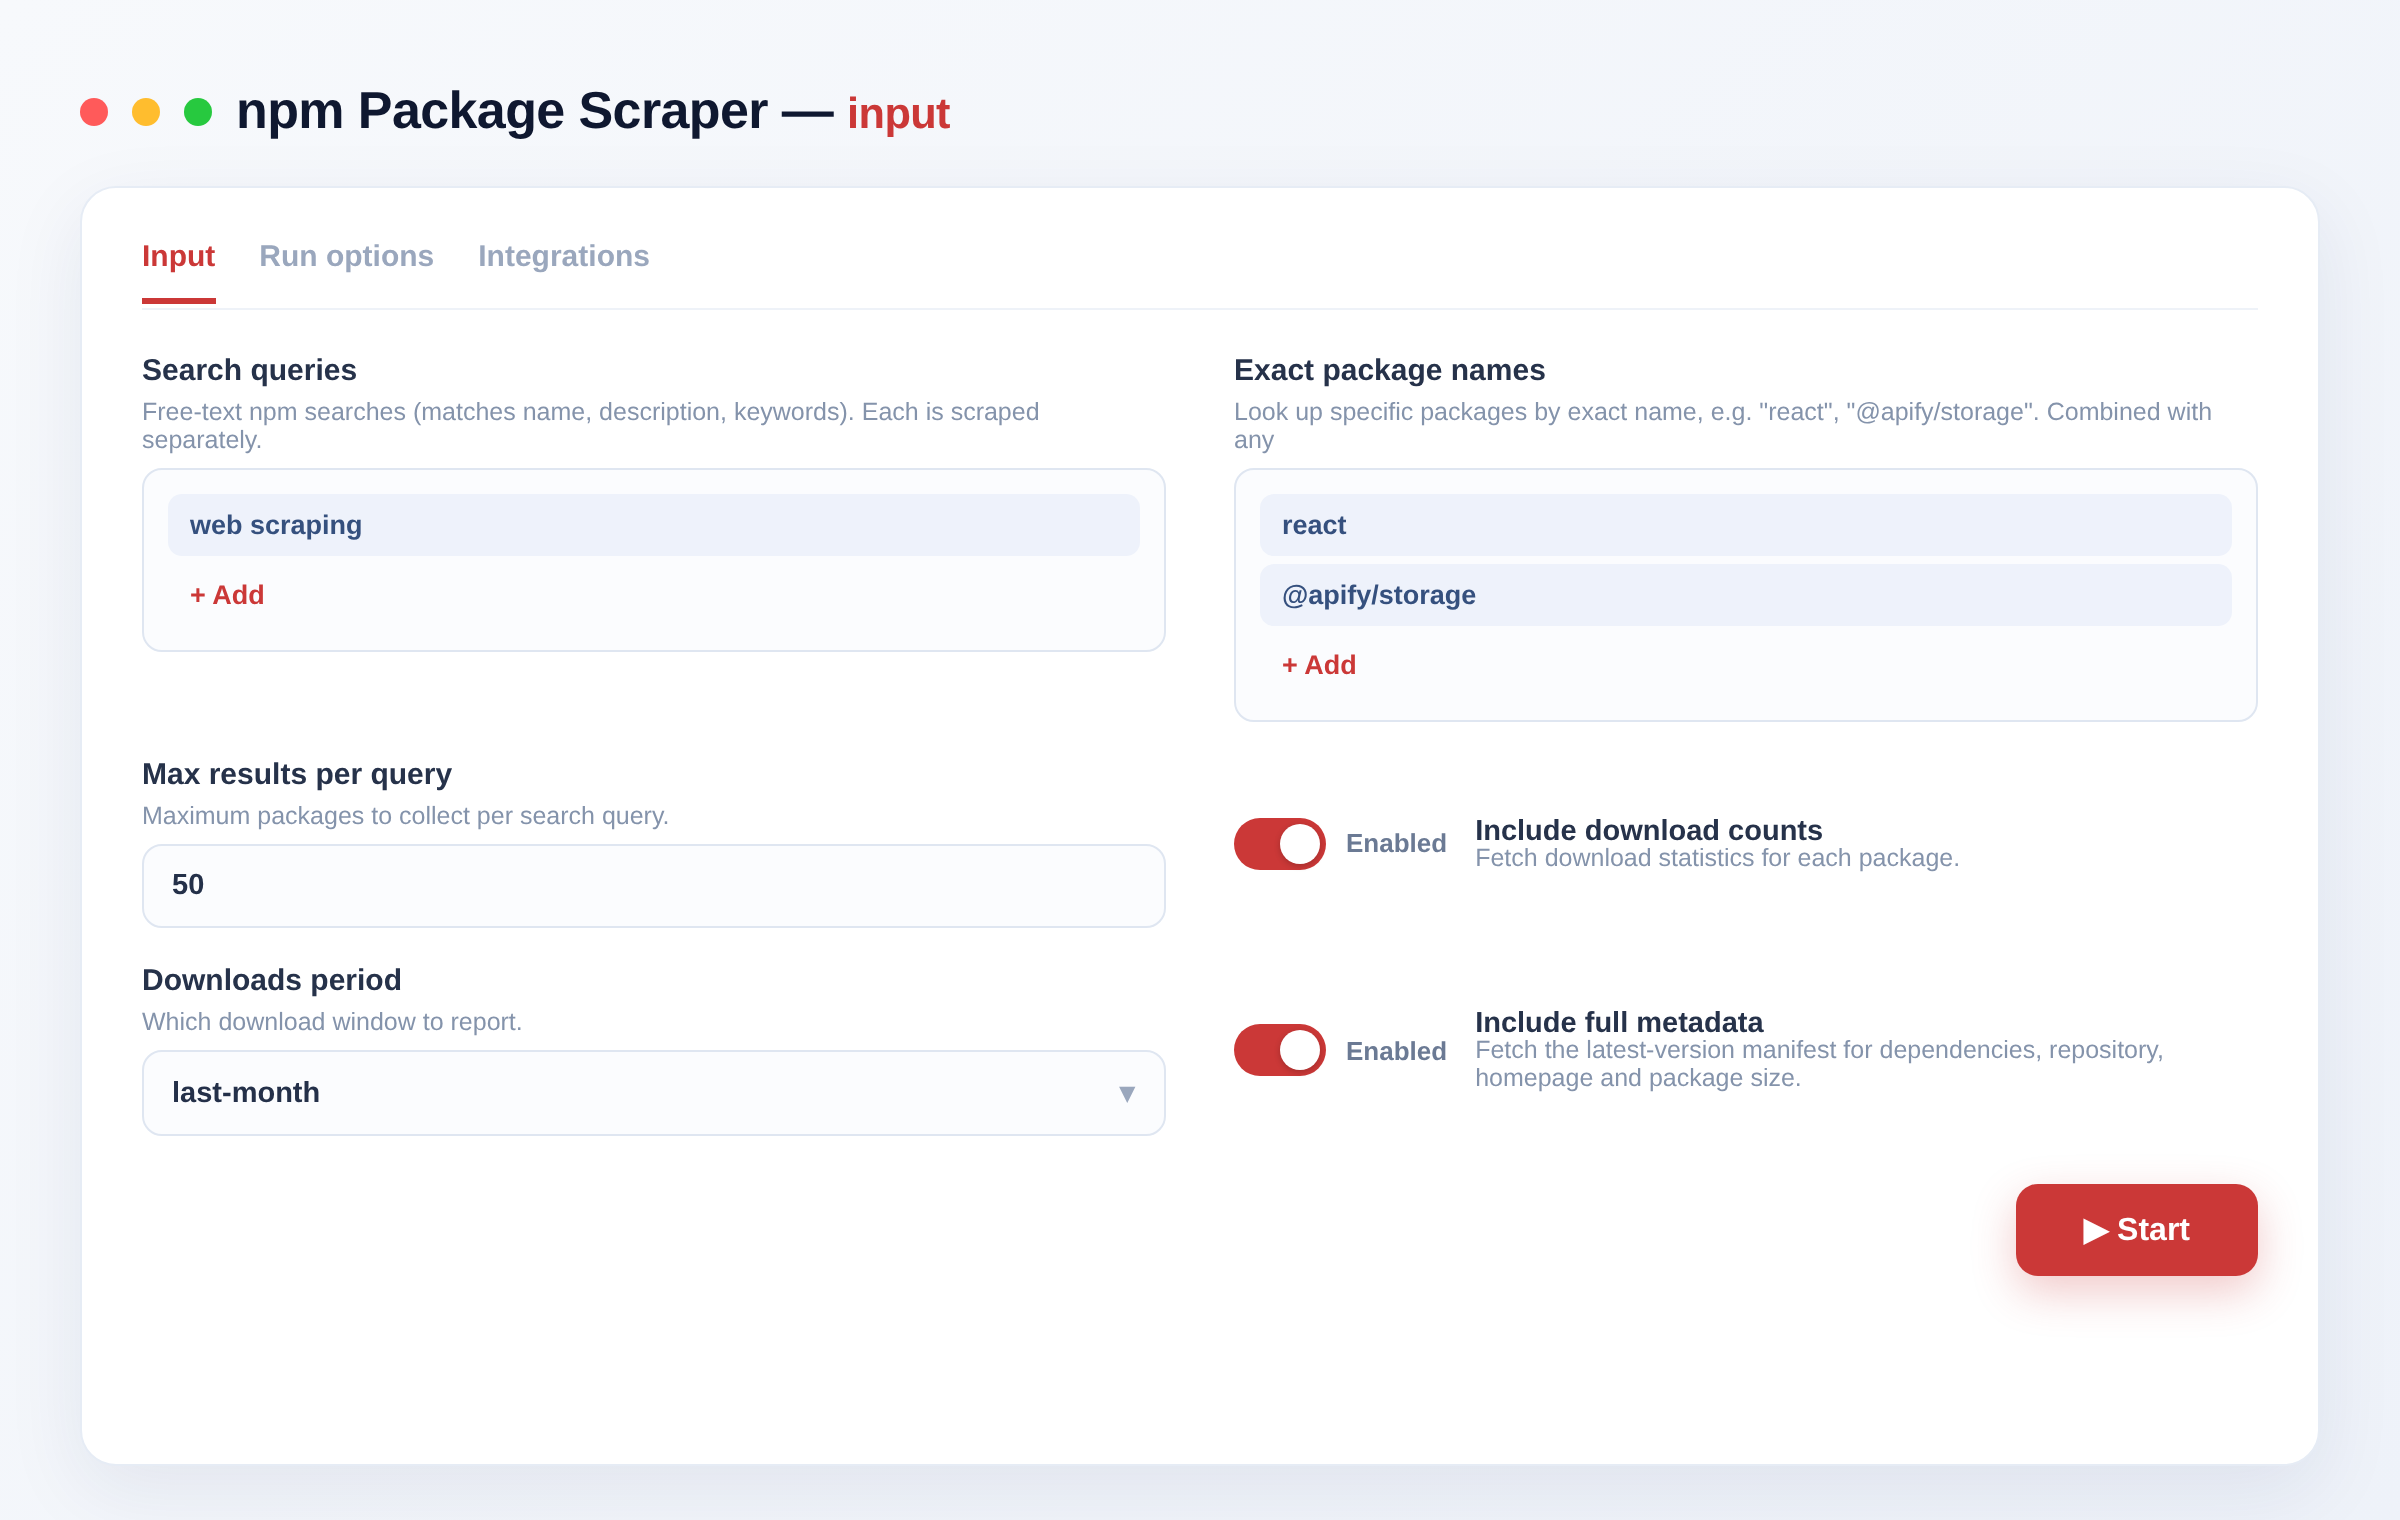
Input
{
  "queries": ["web scraping"],
  "packages": ["cheerio", "express"],
  "maxPerQuery": 50,
  "includeDownloads": true,
  "downloadsPeriod": "last-month",
  "includeMetadata": true
}
| Field | Description |
|---|---|
queries |
Free-text npm searches (name, description, keywords). Each is scraped separately. |
packages |
Exact package names, including scoped @scope/name, combined with search results. |
maxPerQuery |
Maximum packages to collect per search query (1–1000). |
includeDownloads |
Fetch download statistics for each package. |
downloadsPeriod |
Which window to report: last-day, last-week or last-month. |
includeMetadata |
Fetch the latest manifest for dependencies, repository, homepage and size. |
Use cases
- Audit licenses and dependency counts across a set of packages before adoption.
- Compare download trends and quality scores between competing libraries.
- Build a curated catalog of packages for a topic or internal registry.
- Generate outreach lists from
authorandmaintainersfor OSS collaboration.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need an npm account or API key? No. The actor reads from the public npm registry and download APIs, so no account, login or API key is required.
How many packages can I scrape per run?
As many as you like. Each free-text query can return up to 1000 packages (maxPerQuery), and you can add any number of exact package names in packages — including scoped names like @apify/storage.
Is scraping npm allowed? This actor only reads publicly available package metadata through npm's own public registry and download endpoints; it does not access private packages or require authentication. As with any data source, review npm's terms before large-scale or commercial reuse.
What's the output format?
Structured JSON — one clean record per package with fields such as name, version, license, dependencies, unpackedSize, downloads and npms.io quality scores. Export it as JSON, CSV, Excel or via the API.
Can I get download counts and dependencies?
Yes. Set includeDownloads to fetch last-day/week/month figures and choose the window with downloadsPeriod, and set includeMetadata to add dependencies, repositoryUrl, homepage and package size.
Can I integrate this with other tools? The npm Package Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Auditing dependencies and packages across ecosystems? Pair this with our other developer-data scrapers:
- PyPI Package Scraper — metadata, dependencies, licenses and downloads for Python packages from PyPI.
- crates.io Scraper — Rust crate metadata, versions, licenses and download trends.
- GitHub Scraper — repositories and user profiles with stars, topics, licenses and leads.
- Docker Hub Scraper — image metadata, pulls, stars and tags from Docker Hub.
Notes
This actor uses the public npm registry and download APIs and reads only publicly available package data. It is an independent tool and is not affiliated with, endorsed by, or sponsored by npm, Inc. or GitHub; "npm" is a trademark of its respective owner.
Input
| Field | Type | Description |
|---|---|---|
queriesSearch queries | array | Free-text npm searches (matches name, description, keywords). Each is scraped separately. |
packagesExact package names | array | Look up specific packages by exact name, e.g. "react", "@apify/storage". Combined with any search results. |
maxPerQueryMax results per query | integer | Maximum packages to collect per search query. Default: 50 |
includeDownloadsInclude download counts | boolean | Fetch download statistics for each package. Default: true |
downloadsPeriodDownloads period | string · last-day, last-week, last-month | Which download window to report. Default: "last-month" |
includeMetadataInclude full metadata | boolean | Fetch the latest-version manifest for dependencies, repository, homepage and package size. Default: true |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~npm-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "queries": [
    "web scraping"
  ],
  "packages": [
    "cheerio",
    "playwright"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/npm-scraper").call(run_input={
"queries": [
"web scraping"
],
"packages": [
"cheerio",
"playwright"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/npm-scraper').call({
"queries": [
"web scraping"
],
"packages": [
"cheerio",
"playwright"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Package scraped One npm package with version, description, license, dependencies, repository and download count | $0.0015 | $0.0008 |
| Search request One npm registry search page (up to 250 results) | $0.001 | $0.001 |
| API request One metadata or download-stats fetch for a package | $0.0003 | $0.0003 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
North Data Scraper
Look up European companies on North Data: legal name, former names, register number, address, founding date, LEI, business purpose, managing directors and officers, and recent register publications. Germany, UK, France, Austria and 20+ countries. Bulk lookups.
2,467 runs · 5 users · $0.004 / company
Website Content Crawler
Extract clean, readable content from any list of websites: page title, meta description, headings, main body text, word count and link/image counts. Optional same-domain crawl. Bulk-ready. Great for LLM/RAG ingestion, content audits and research.
206 runs · 20 users · $0.0024 / page scraped
SpyFu Domain Scraper
Bulk SEO and PPC reports for any domain from SpyFu: organic keywords, monthly SEO clicks and value, Google Ads budget, paid keywords, top keywords, competitors, top countries and monthly history. Competitor research for agencies. Export CSV/JSON.
185 runs · 7 users · $0.008 / domain report
Trustpilot Reviews Scraper
Scrape Trustpilot reviews and company ratings by company domain or Trustpilot URL: star rating, title, text, reviewer name & country, verification, date, company reply, plus company TrustScore and total reviews.
146 runs · 4 users · $0.0006 / review scraped
ACRA Singapore Company Registry Scraper
Search and export Singapore's full ACRA corporate registry: UEN, entity name, status, incorporation date, address, SSIC industry codes, officers, former names and audit firms. Filter by name, status, entity type or industry. Public open data, no setup.
138 runs · 10 users · $0.01 / company scraped
Wayback Machine Scraper
List every Internet Archive (Wayback Machine) snapshot of a URL or whole domain: timestamp, snapshot URL, status code, MIME type and content digest. Filter by date, status and dedupe. For SEO, OSINT and historical research. No setup.
135 runs · 15 users · $0.002 / snapshot scrapedSend the site and the fields. We build it and you get it first.