Stack Overflow & Stack Exchange Scraper
hipersoft/stackexchange-scraper
Scrape questions from Stack Overflow and any Stack Exchange site by tag or full-text search: title, tags, score, views, answer count, accepted answer, author, dates, link and full question body. Fast clean HTTP via the Stack Exchange API; optional key for higher quota.
Total users
1Monthly users
1Total runs
117Per question scraped
$0.004Last rebuilt
Oct 28, 2026Overview
Scrape questions from Stack Overflow and any Stack Exchange site by tag or full-text search, and get back clean, structured JSON — title, tags, score, views, answer count, accepted-answer flag, author, dates, link and the full question body. It runs on the official Stack Exchange API v2.3, with automatic pagination so large tag or search result sets come back in one run. No key required; add an optional Stack Apps key to raise the daily quota. Built for developer researchers, community analysts and knowledge-base builders.
Features
- 🌐 Any Stack Exchange site —
sitetargetsstackoverflow,serverfault,superuser,askubuntu,math,stats,unixand more. - 🏷️ Tag or search — filter by
tags, run a full-textquery, or combine both. - 🔀 Smart sorting —
sortBysupportsvotes,activity,creation,hot(tag mode) orrelevance(search mode). - 📈 Quality filter —
minScorekeeps only questions above a score threshold. - 📄 Full question body — the
bodyfield carries the cleaned-up question text, HTML stripped and entities decoded. - 🔑 Optional API key — supply a Stack Apps key to lift the quota from 300 to 10,000 requests/day.
- ⚡ Deep pagination — pages through large result sets up to
maxItemsautomatically.
What you get
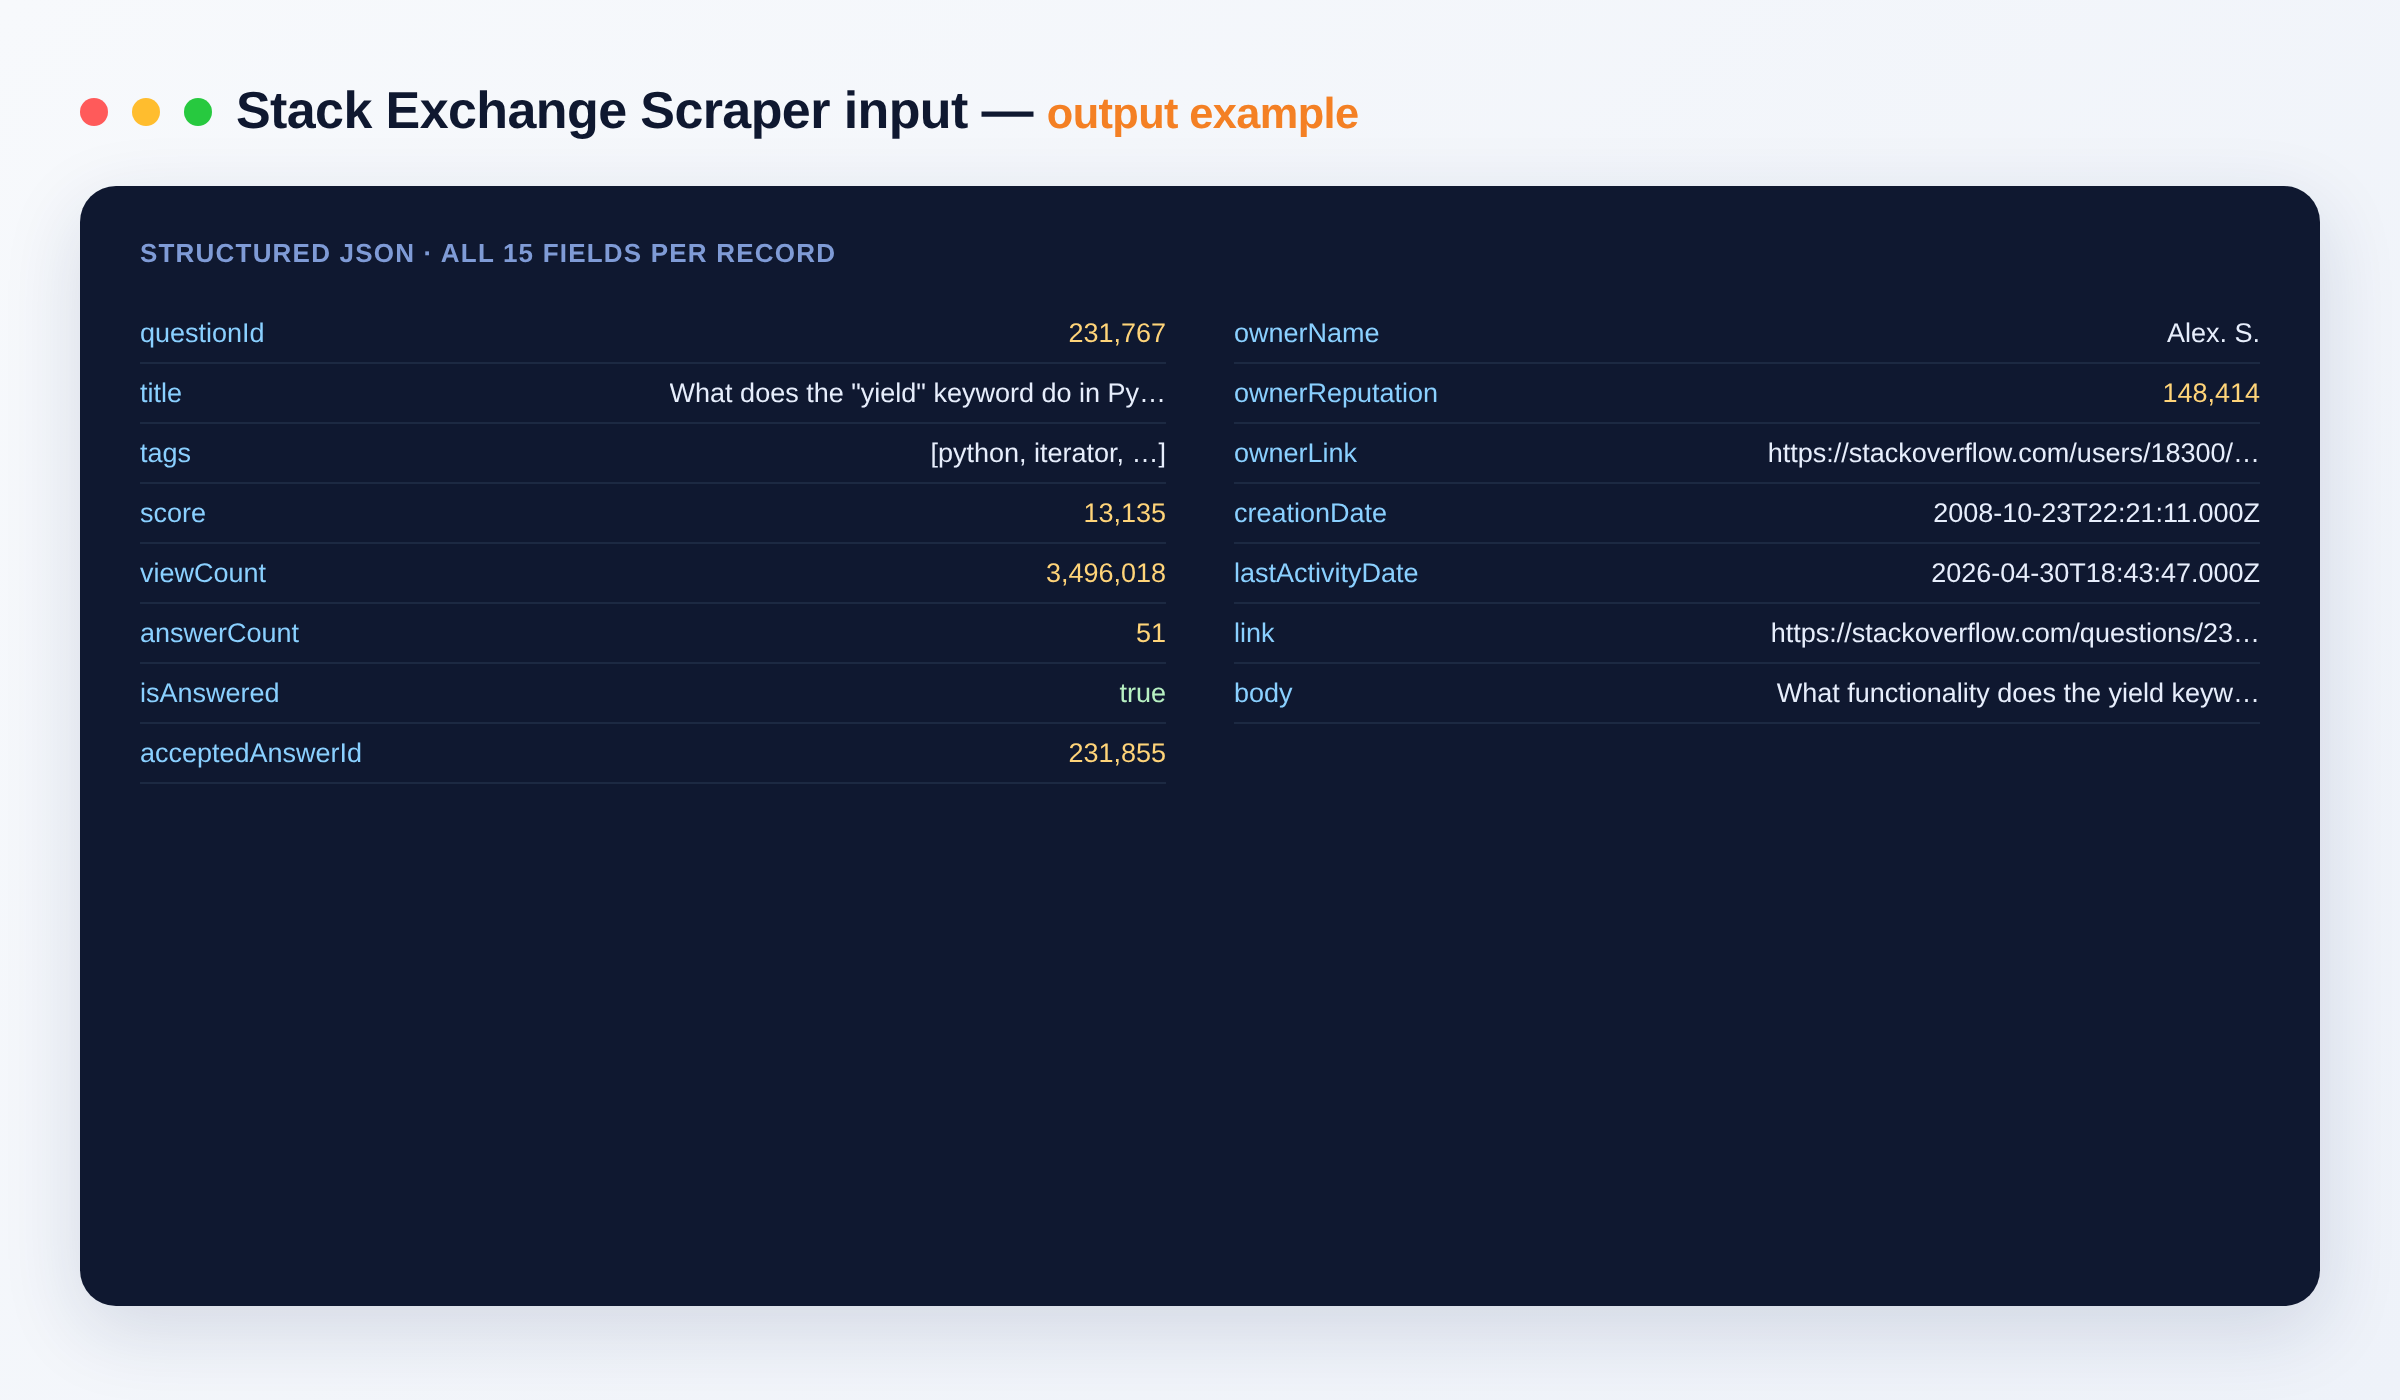
Every question becomes one clean JSON record:
{
  "questionId": 12345678,
  "title": "How do I merge two dictionaries in Python?",
  "tags": ["python", "dictionary", "merge"],
  "score": 4820,
  "viewCount": 3100000,
  "answerCount": 27,
  "isAnswered": true,
  "acceptedAnswerId": 12345699,
  "ownerName": "devuser",
  "ownerReputation": 15230,
  "ownerLink": "https://stackoverflow.com/users/1/devuser",
  "creationDate": "2016-09-02T10:12:00.000Z",
  "lastActivityDate": "2026-05-14T08:41:00.000Z",
  "link": "https://stackoverflow.com/questions/12345678/how-do-i-merge-two-dictionaries",
  "body": "I have two Python dictionaries and I want to combine them into one..."
}
Output schema
| Field | Type | Description |
|---|---|---|
questionId |
integer | Unique Stack Exchange question ID. |
title |
string | Question title. |
tags |
array | Tags applied to the question. |
score |
integer | Net vote score of the question. |
viewCount |
integer | Number of times the question was viewed. |
answerCount |
integer | Number of answers on the question. |
isAnswered |
boolean | Whether the question is marked answered. |
acceptedAnswerId |
integer | ID of the accepted answer, if any. |
ownerName |
string | Display name of the question's author. |
ownerReputation |
integer | Reputation score of the author. |
ownerLink |
string (URL) | Link to the author's profile. |
creationDate |
string (ISO date) | When the question was created. |
lastActivityDate |
string (ISO date) | When the question last had activity. |
link |
string (URL) | Link to the question. |
body |
string | Cleaned-up question text (HTML stripped). |
Input
{
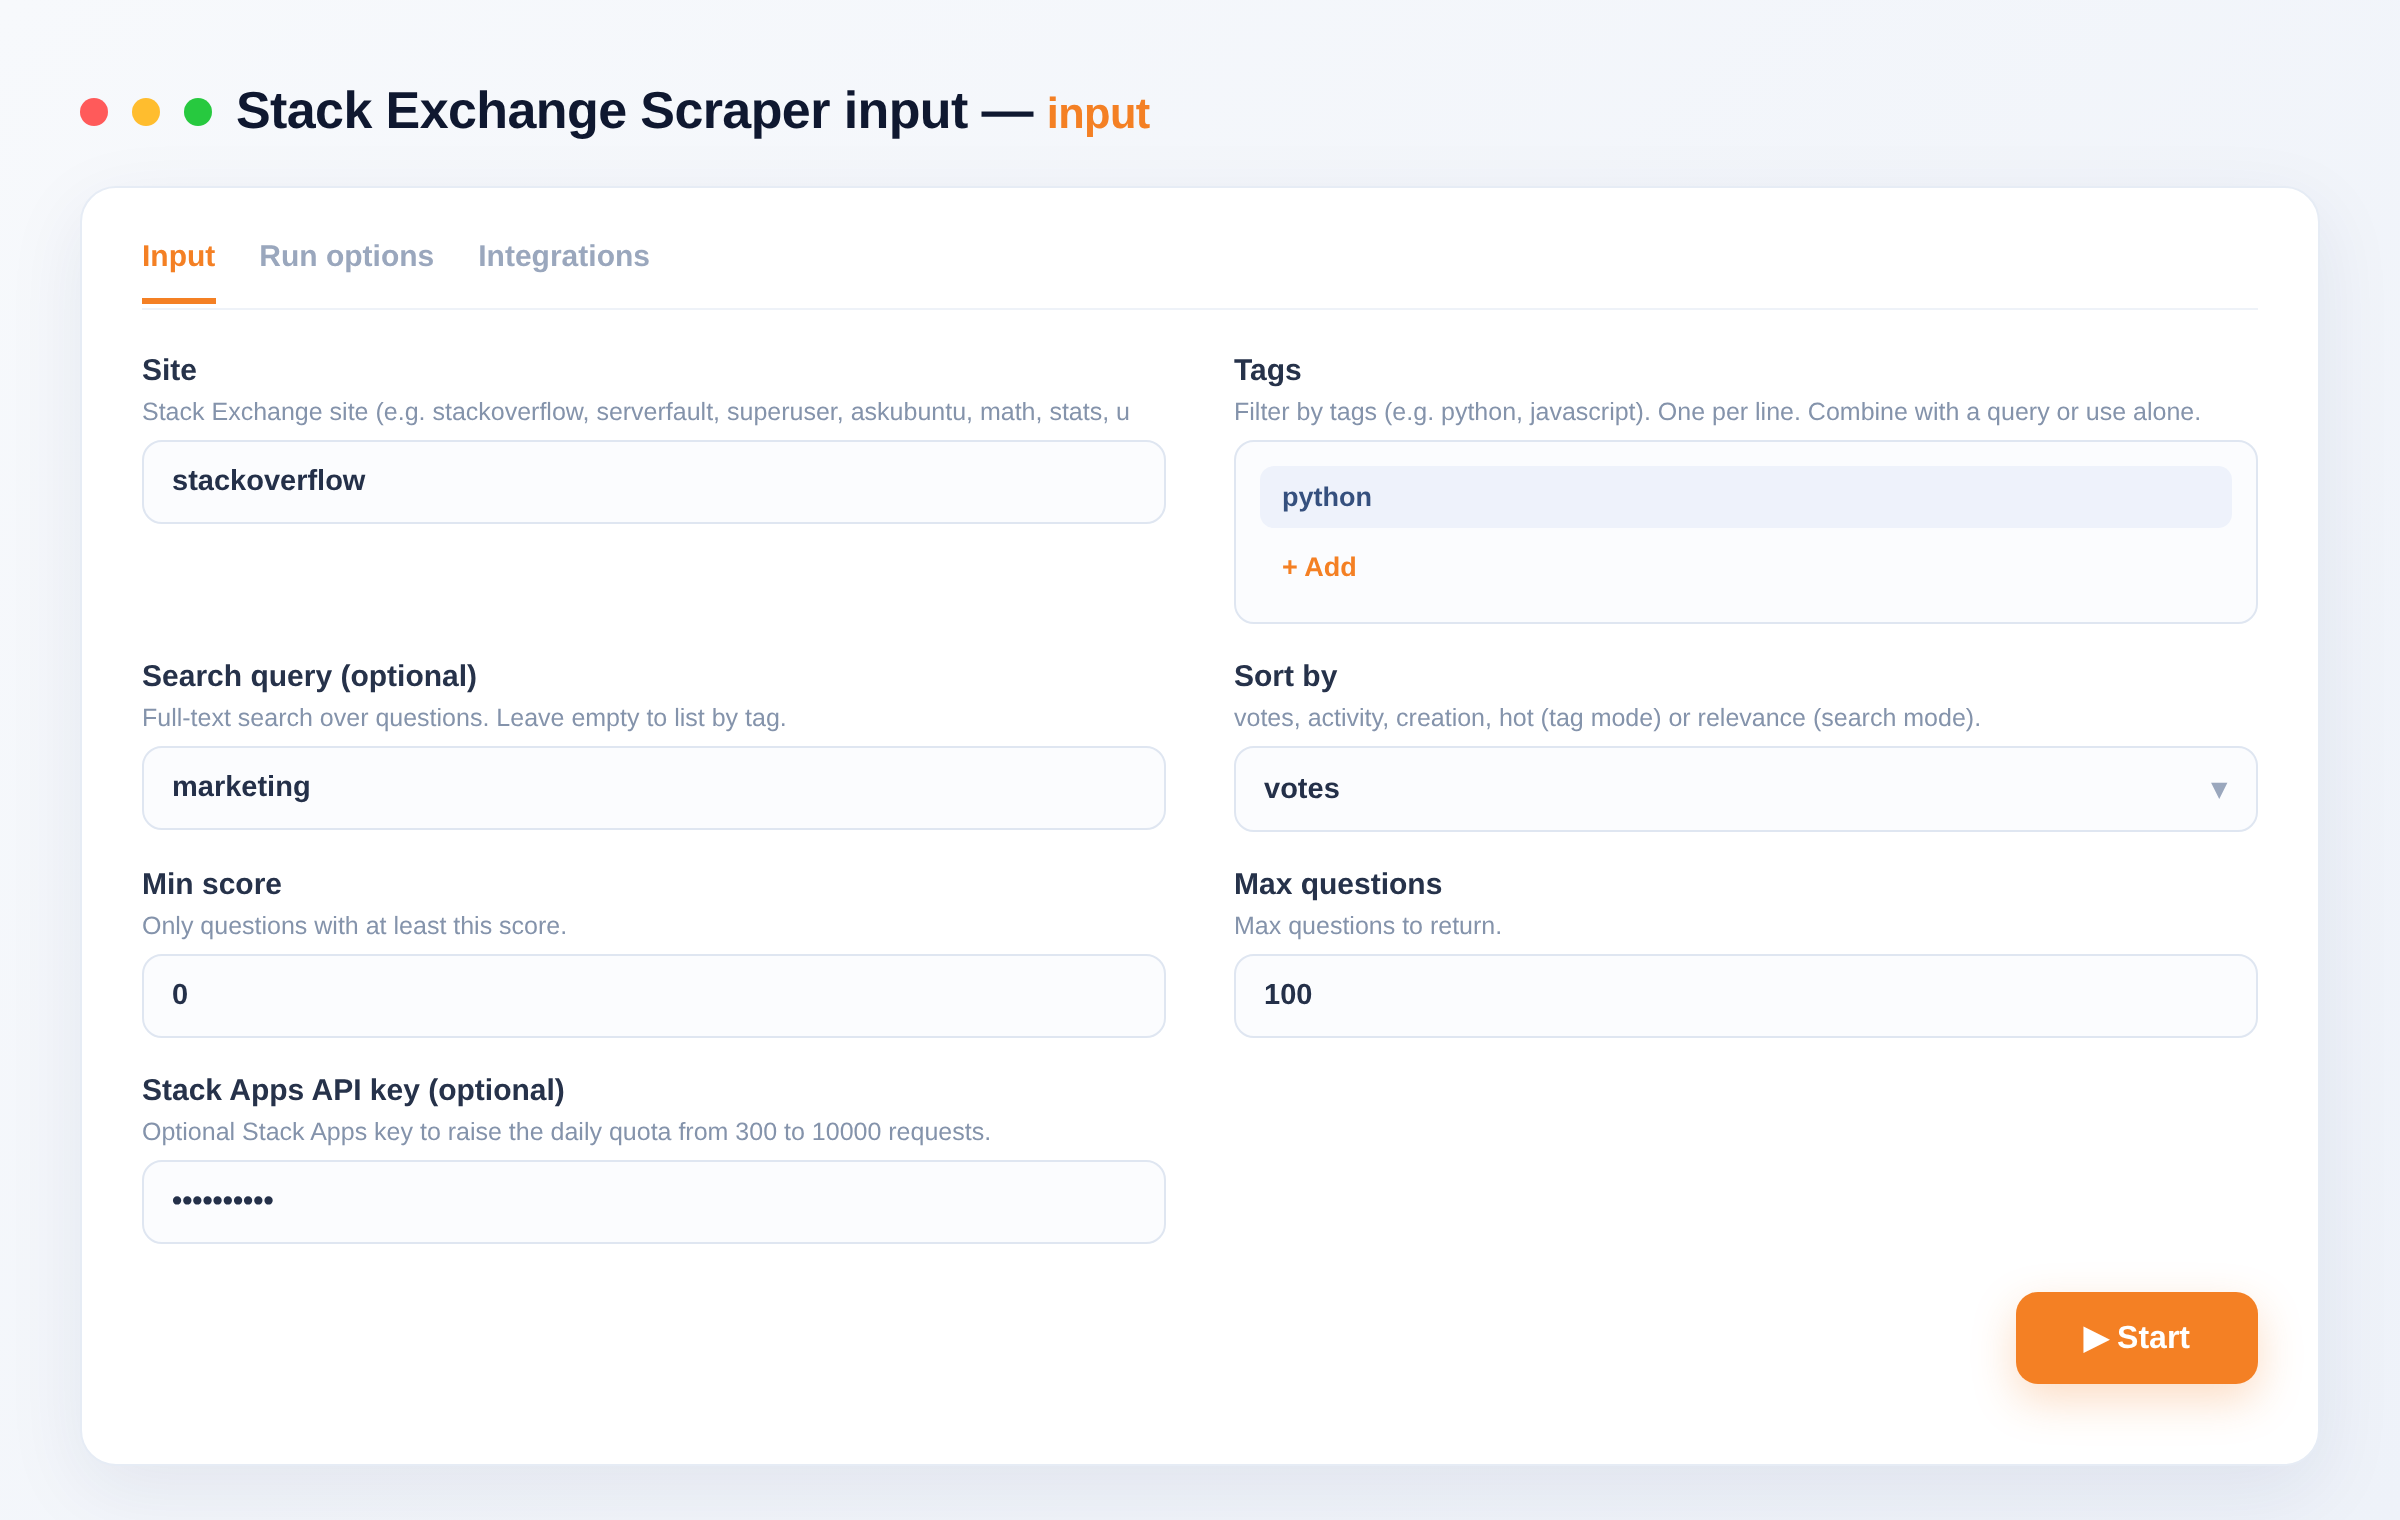
  "site": "stackoverflow",
  "tags": ["python"],
  "query": "",
  "sortBy": "votes",
  "minScore": 50,
  "maxItems": 500
}
| Field | Description |
|---|---|
site |
Stack Exchange site (e.g. stackoverflow, serverfault, superuser, askubuntu, math, stats, unix). |
tags |
Filter by tags (e.g. python, javascript). One per line. Combine with a query or use alone. |
query |
Full-text search over questions. Leave empty to list by tag. |
sortBy |
votes, activity, creation, hot (tag mode) or relevance (search mode). |
minScore |
Only questions with at least this score. |
maxItems |
Max questions to return. |
apiKey |
Optional Stack Apps key to raise the daily quota from 300 to 10,000 requests. |
Use cases
- Mine the highest-voted questions for a tag to find common problems and gaps.
- Track new or trending questions on a niche Stack Exchange site.
- Build a developer knowledge base or FAQ dataset from accepted-answer questions.
- Analyze community activity by score, views and answer counts over time.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need a Stack Exchange account or API key? No. The actor runs on the official Stack Exchange API v2.3 with no key. An optional Stack Apps key is only needed to raise the daily quota from 300 to 10,000 requests.
How many questions can I scrape per run?
As many as you set with maxItems. The actor walks the API's has_more pages automatically with rate-limit backoff until it hits your limit.
Which sites can I scrape besides Stack Overflow?
Any Stack Exchange site — set site to stackoverflow, serverfault, superuser, askubuntu, math, stats, unix and many more.
What's the output format?
Structured JSON — one record per question with title, tags, score, viewCount, answerCount, isAnswered, acceptedAnswerId, author, dates, link and the full cleaned-up body. Export as JSON, CSV, Excel or via the API.
Can I filter by tag, score or search term?
Yes. Filter by tags, run a full-text query, or combine both; keep only high-quality items with minScore; and order results with sortBy (votes, activity, creation, hot, or relevance in search mode).
Can I integrate this with other tools? The Stack Exchange Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Building a developer knowledge base or research dataset? Combine this with our other developer-data scrapers:
- Hacker News Scraper — stories, comments and Ask/Show HN by keyword and filters.
- GitHub Scraper — repositories and user profiles with stars, topics, licenses and leads.
- Wikipedia Scraper — full article text, summaries and pageviews in any language.
- npm Package Scraper — search and look up npm packages with metadata, dependencies and downloads.
Notes
This Actor uses the official public Stack Exchange API (v2.3). It is an independent tool and is not affiliated with, endorsed by, or sponsored by Stack Exchange Inc.; "Stack Overflow" and "Stack Exchange" are trademarks of Stack Exchange Inc.
Input
| Field | Type | Description |
|---|---|---|
siteSite | string | Stack Exchange site (e.g. stackoverflow, serverfault, superuser, askubuntu, math, stats, unix). Default: "stackoverflow" |
tagsTags | array | Filter by tags (e.g. python, javascript). One per line. Combine with a query or use alone. |
querySearch query (optional) | string | Full-text search over questions. Leave empty to list by tag. |
sortBySort by | string · votes, relevance, activity, creation, hot | votes, activity, creation, hot (tag mode) or relevance (search mode). Default: "votes" |
minScoreMin score | integer | Only questions with at least this score. Default: 0 |
maxItemsMax questions | integer | Max questions to return. Default: 100 |
apiKeyStack Apps API key (optional) | string | Optional Stack Apps key to raise the daily quota from 300 to 10000 requests. |
proxyConfigurationProxy (optional) | object | Optional. The Stack Exchange API works without a proxy. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~stackexchange-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "tags": [
    "python"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/stackexchange-scraper").call(run_input={
"tags": [
"python"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/stackexchange-scraper').call({
"tags": [
"python"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Question scraped One question with title, tags, score, views, answers, author, dates and full body | $0.004 | $0.002 |
| API request One Stack Exchange API request (up to 100 questions) | $0.001 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Steam Reviews Scraper
Scrape user reviews and ratings for any game on Steam. Get the review text, recommended/not-recommended, helpful & funny votes, author playtime, purchase type, language, early-access flag and dates. One clean row per review as JSON, CSV or Excel.
45 runs · 2 users · $0.0008 / review scraped
Lobsters Scraper
Scrape stories from Lobsters (lobste.rs): title, link, score, comments, submitter, tags and description. Pull the Hottest or Newest feed, or filter by tag. One clean row per story as JSON, CSV or Excel.
41 runs · 2 users · $0.0015 / story scraped
Rotten Tomatoes Scraper
Scrape Rotten Tomatoes movie and TV data: Tomatometer critics score, audience score, sentiment, title, year, genres, content rating, director, cast, description and poster. Just pass titles or URLs. One row per title as JSON, CSV or Excel.
38 runs · 2 users · $0.002 / title scraped
AniList Scraper
Scrape anime and manga data from AniList: title, score, popularity, format, status, episodes/chapters, genres, studios, season, start/end dates, description and cover image. Search by title. One row per title as JSON, CSV or Excel.
38 runs · 2 users · $0.001 / title scraped
Readability Scorer
Score how easy any text is to read. Get Flesch Reading Ease, Flesch-Kincaid Grade, Gunning Fog, SMOG, Coleman-Liau and ARI, plus word, sentence and syllable counts and a plain-English difficulty label. Score one text or many at once. Output JSON, CSV or Excel.
37 runs · 2 users · $0.001 / text scored
Chess.com Player Scraper
Scrape Chess.com player data in bulk: name, title, country, followers, join date, and ratings for rapid, blitz, bullet and daily plus win/loss/draw records, best ratings, tactics and puzzle rush. Just pass usernames. One row per player as JSON, CSV or Excel.
37 runs · 2 users · $0.001 / player scrapedSend the site and the fields. We build it and you get it first.