Wikipedia Scraper
hipersoft/wikipedia-scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
Total users
1Monthly users
1Total runs
121Per article scraped
$0.001Last rebuilt
Oct 26, 2026Overview
Search Wikipedia or look up exact article titles and get back clean, structured JSON — full plain-text article content, intro summary, categories, lead image, Wikidata ID and monthly pageview trends. Works in any language edition. No account, no API key. Perfect for research, building RAG and AI training datasets, content analysis and tracking topic popularity over time.
Features
- 🔎 Search + exact titles — combine
searchTerms(which pull matching articles) with exacttitles; results are deduplicated by title. - 🌍 Any language — set
languageto any Wikipedia edition code (en,es,de,fr,ja, …). - 📄 Full plain text — toggle
fullTextfor the complete article as clean plain text, or just the intro summary when off. - 📈 Pageview trends — flip
includePageviewsto attach the last 6 months of monthly pageviews plus apageviewsTotal. - 🏷️ Rich metadata — visible categories, lead image URL, Wikidata ID, page ID, word count and last-modified timestamp on every record.
- ✂️ Clean snippets — search snippets are stripped of HTML and decoded from entities into readable text.
- 📊 Scales per term — take up to 500 articles from each search term with automatic pagination and retries.
What you get
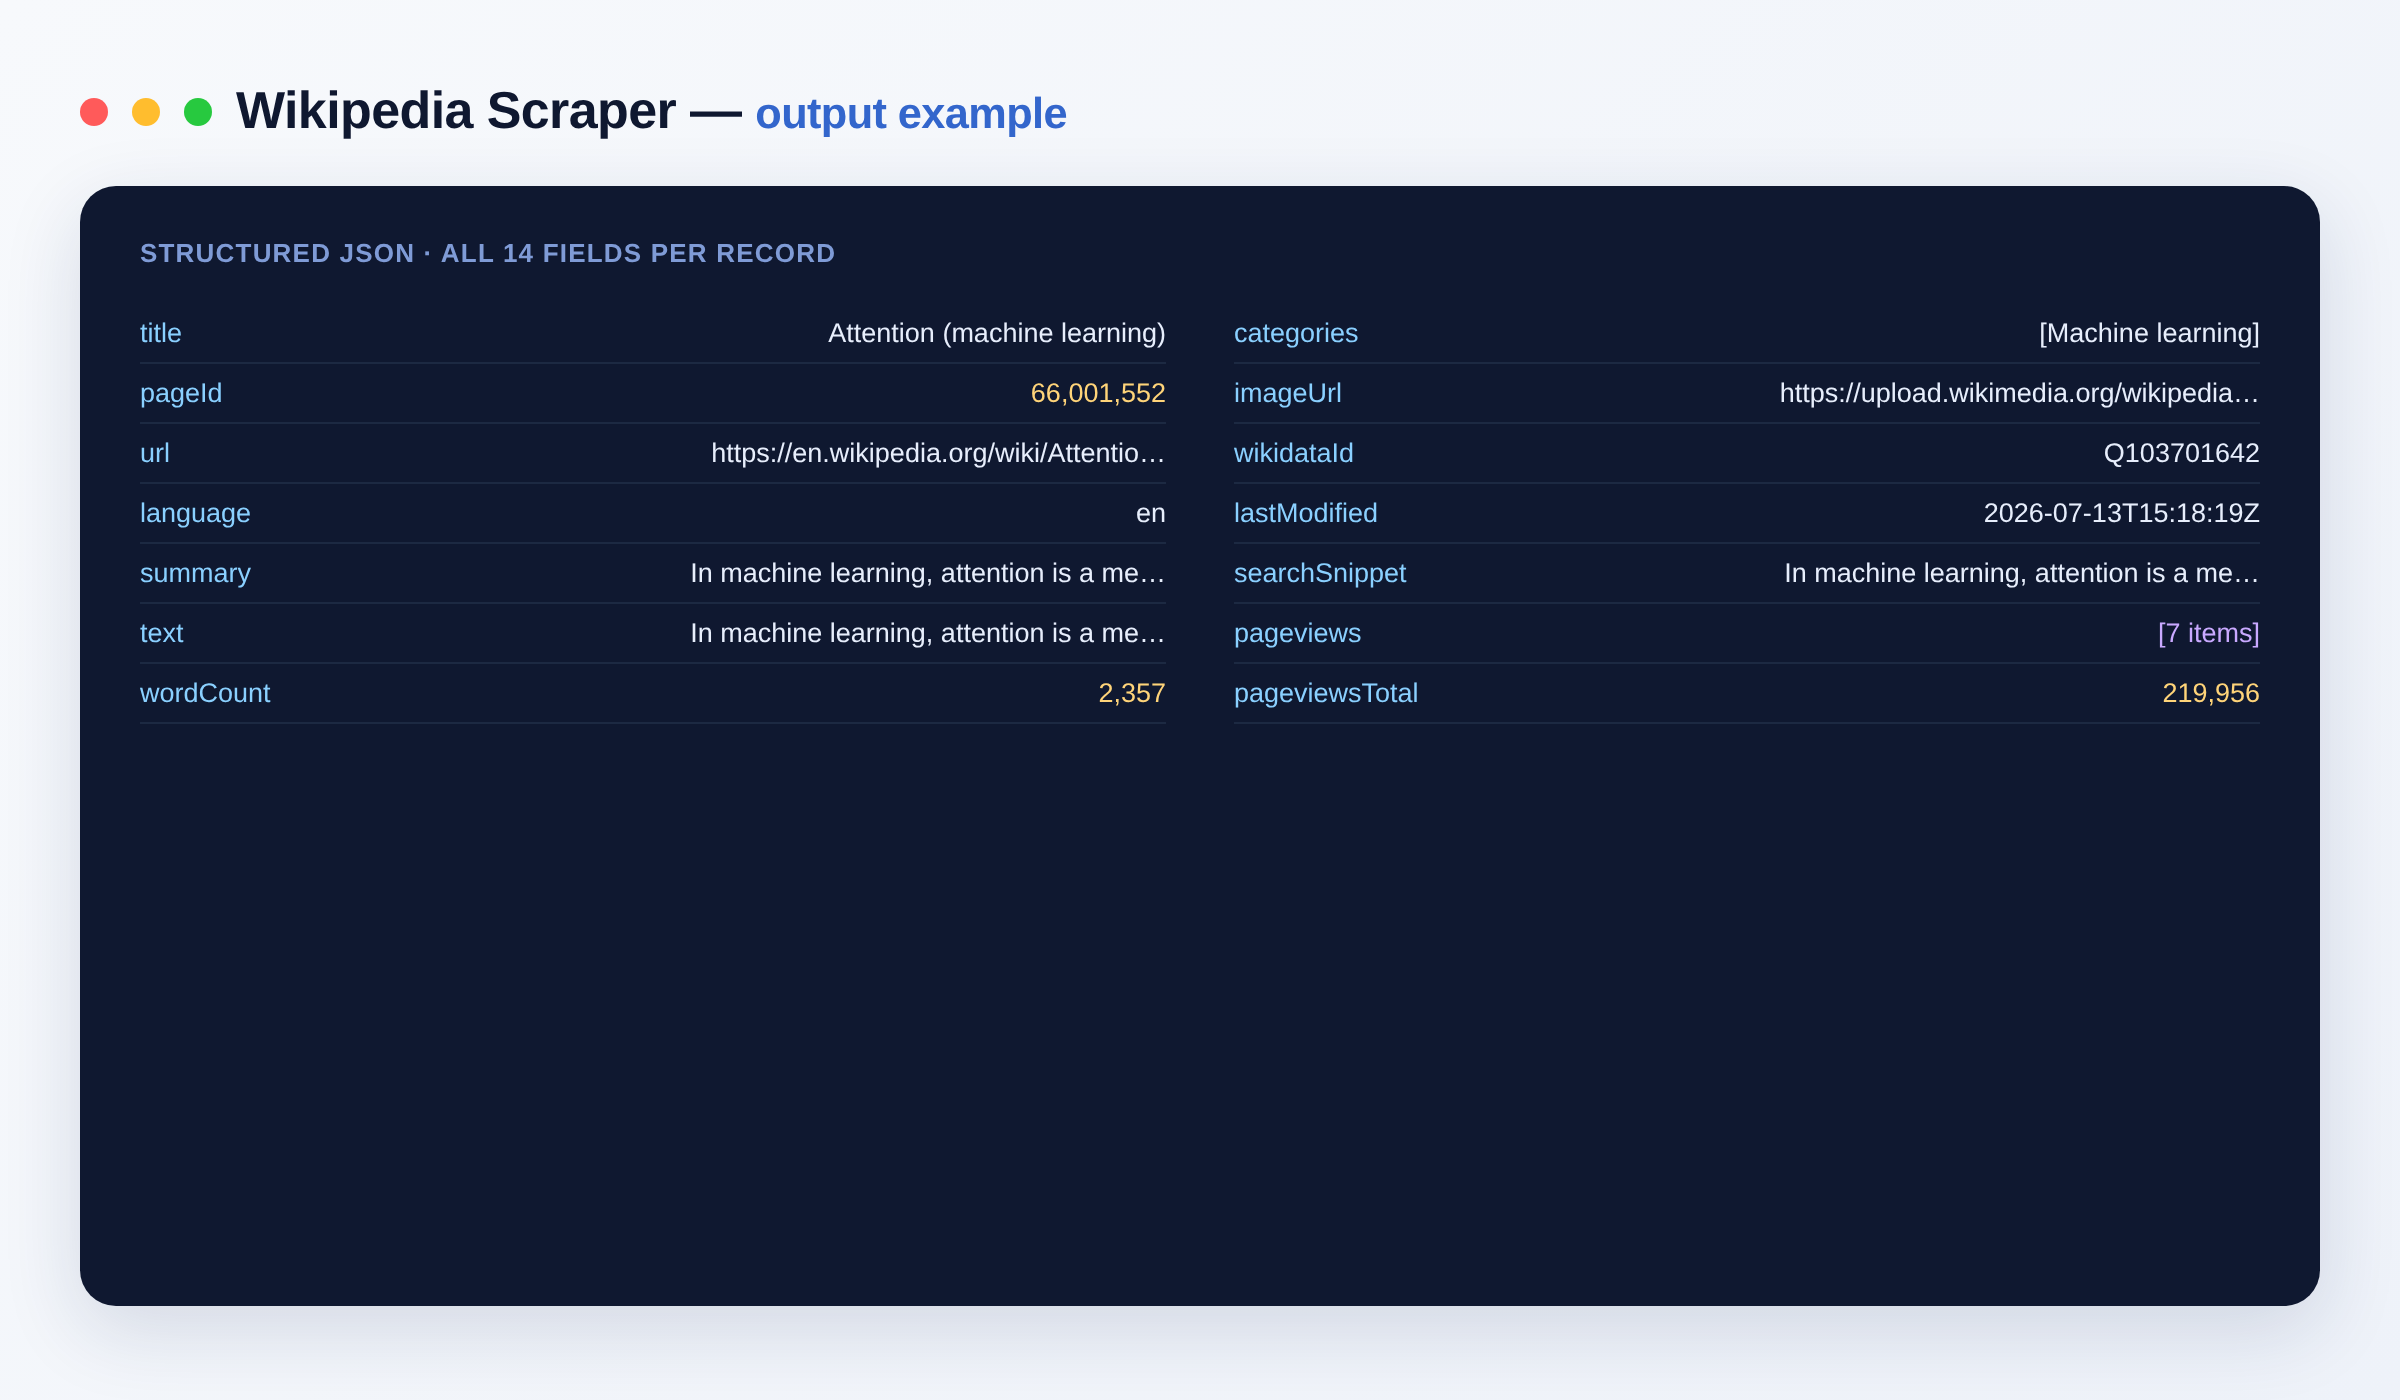
Each dataset row is one article:
{
  "title": "Machine learning",
  "pageId": 233488,
  "url": "https://en.wikipedia.org/wiki/Machine_learning",
  "language": "en",
  "summary": "Machine learning (ML) is a field of study in artificial intelligence concerned with...",
  "text": "Machine learning (ML) is a field of study in artificial intelligence...\n\nHistory...",
  "wordCount": 9231,
  "categories": ["Machine learning", "Cybernetics", "Learning"],
  "imageUrl": "https://upload.wikimedia.org/wikipedia/commons/.../example.svg",
  "wikidataId": "Q2539",
  "lastModified": "2024-11-20T14:03:12Z",
  "searchSnippet": "Machine learning is a field of study in artificial intelligence...",
  "pageviews": [
    { "month": "202502", "views": 412034 },
    { "month": "202503", "views": 398115 }
  ],
  "pageviewsTotal": 2410882
}
Output schema
| Field | Type | Description |
|---|---|---|
title |
string | Article title. |
pageId |
integer | Wikipedia numeric page ID. |
url |
string (URL) | Canonical URL of the article. |
language |
string | Wikipedia language edition code (e.g. en). |
summary |
string | Intro summary of the article. |
text |
string | Full article body as clean plain text. |
wordCount |
integer | Number of words in the article text. |
categories |
array | Visible category labels for the article. |
imageUrl |
string (URL) | Link to the article's lead image. |
wikidataId |
string | Linked Wikidata entity ID. |
lastModified |
string (ISO date) | Timestamp the article was last edited. |
searchSnippet |
string | Plain-text search-result snippet. |
pageviews |
array | Monthly pageview counts as month/views objects. |
pageviewsTotal |
integer | Sum of pageviews over the returned months. |
Input
{
  "searchTerms": ["quantum computing", "climate change"],
  "titles": ["Alan Turing", "Python (programming language)"],
  "language": "en",
  "maxResultsPerSearch": 20,
  "fullText": true,
  "includePageviews": true
}
| Field | Description |
|---|---|
searchTerms |
Terms to search Wikipedia for; matching articles are scraped. |
titles |
Exact article titles to scrape, combined with any search results. |
language |
Wikipedia language edition code (e.g. en, es, de, fr, ja). |
maxResultsPerSearch |
How many articles to take from each search term (1–500). |
fullText |
Include the full plain-text article; if off, only the intro summary. |
includePageviews |
Attach the last 6 months of monthly pageviews per article. |
Use cases
- Build clean, plain-text article corpora for RAG pipelines and AI training datasets.
- Track topic popularity over time using monthly pageview trends.
- Enrich entities with Wikidata IDs, categories and lead images.
- Compile multilingual reference content by running the same titles across language editions.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need a Wikipedia account or API key? No. The actor uses Wikipedia's public MediaWiki APIs and the Wikimedia pageviews API — no account, login or API key.
How many articles can I scrape per run?
Each search term can return up to 500 articles (maxResultsPerSearch), with automatic pagination and retries. You can also add any number of exact titles, and results are deduplicated by title.
Can I scrape non-English Wikipedia?
Yes. Set language to any Wikipedia edition code (en, es, de, fr, ja, …), and run the same titles across editions for multilingual corpora.
What's the output format?
Structured JSON — one record per article with title, url, summary, full plain-text text, wordCount, categories, imageUrl, wikidataId and optional monthly pageviews. Export as JSON, CSV, Excel or via the API.
Can I get full article text and pageview trends?
Yes. Toggle fullText for the complete cleaned plain text (or just the intro summary when off), and set includePageviews to attach the last 6 months of monthly pageviews plus a pageviewsTotal.
Can I connect this to other apps and services? The Wikipedia Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Building research or RAG datasets? Combine this with our other reference and developer-data scrapers:
- Stack Overflow & Stack Exchange Scraper — questions by tag or search across Stack Exchange sites.
- Hacker News Scraper — stories, comments and Ask/Show HN by keyword and filters.
- GitHub Scraper — repositories and user profiles with stars, topics, licenses and leads.
- npm Package Scraper — search and look up npm packages with metadata, dependencies and downloads.
Notes
This Actor uses Wikipedia's public MediaWiki APIs and the Wikimedia pageviews API, returning that content as-is over openly available pages with no login required. Article text is available under Wikipedia's own licensing (typically CC BY-SA); check and comply with those terms for reuse. This is an independent tool and is not affiliated with, endorsed by, or sponsored by Wikipedia or the Wikimedia Foundation.
Input
| Field | Type | Description |
|---|---|---|
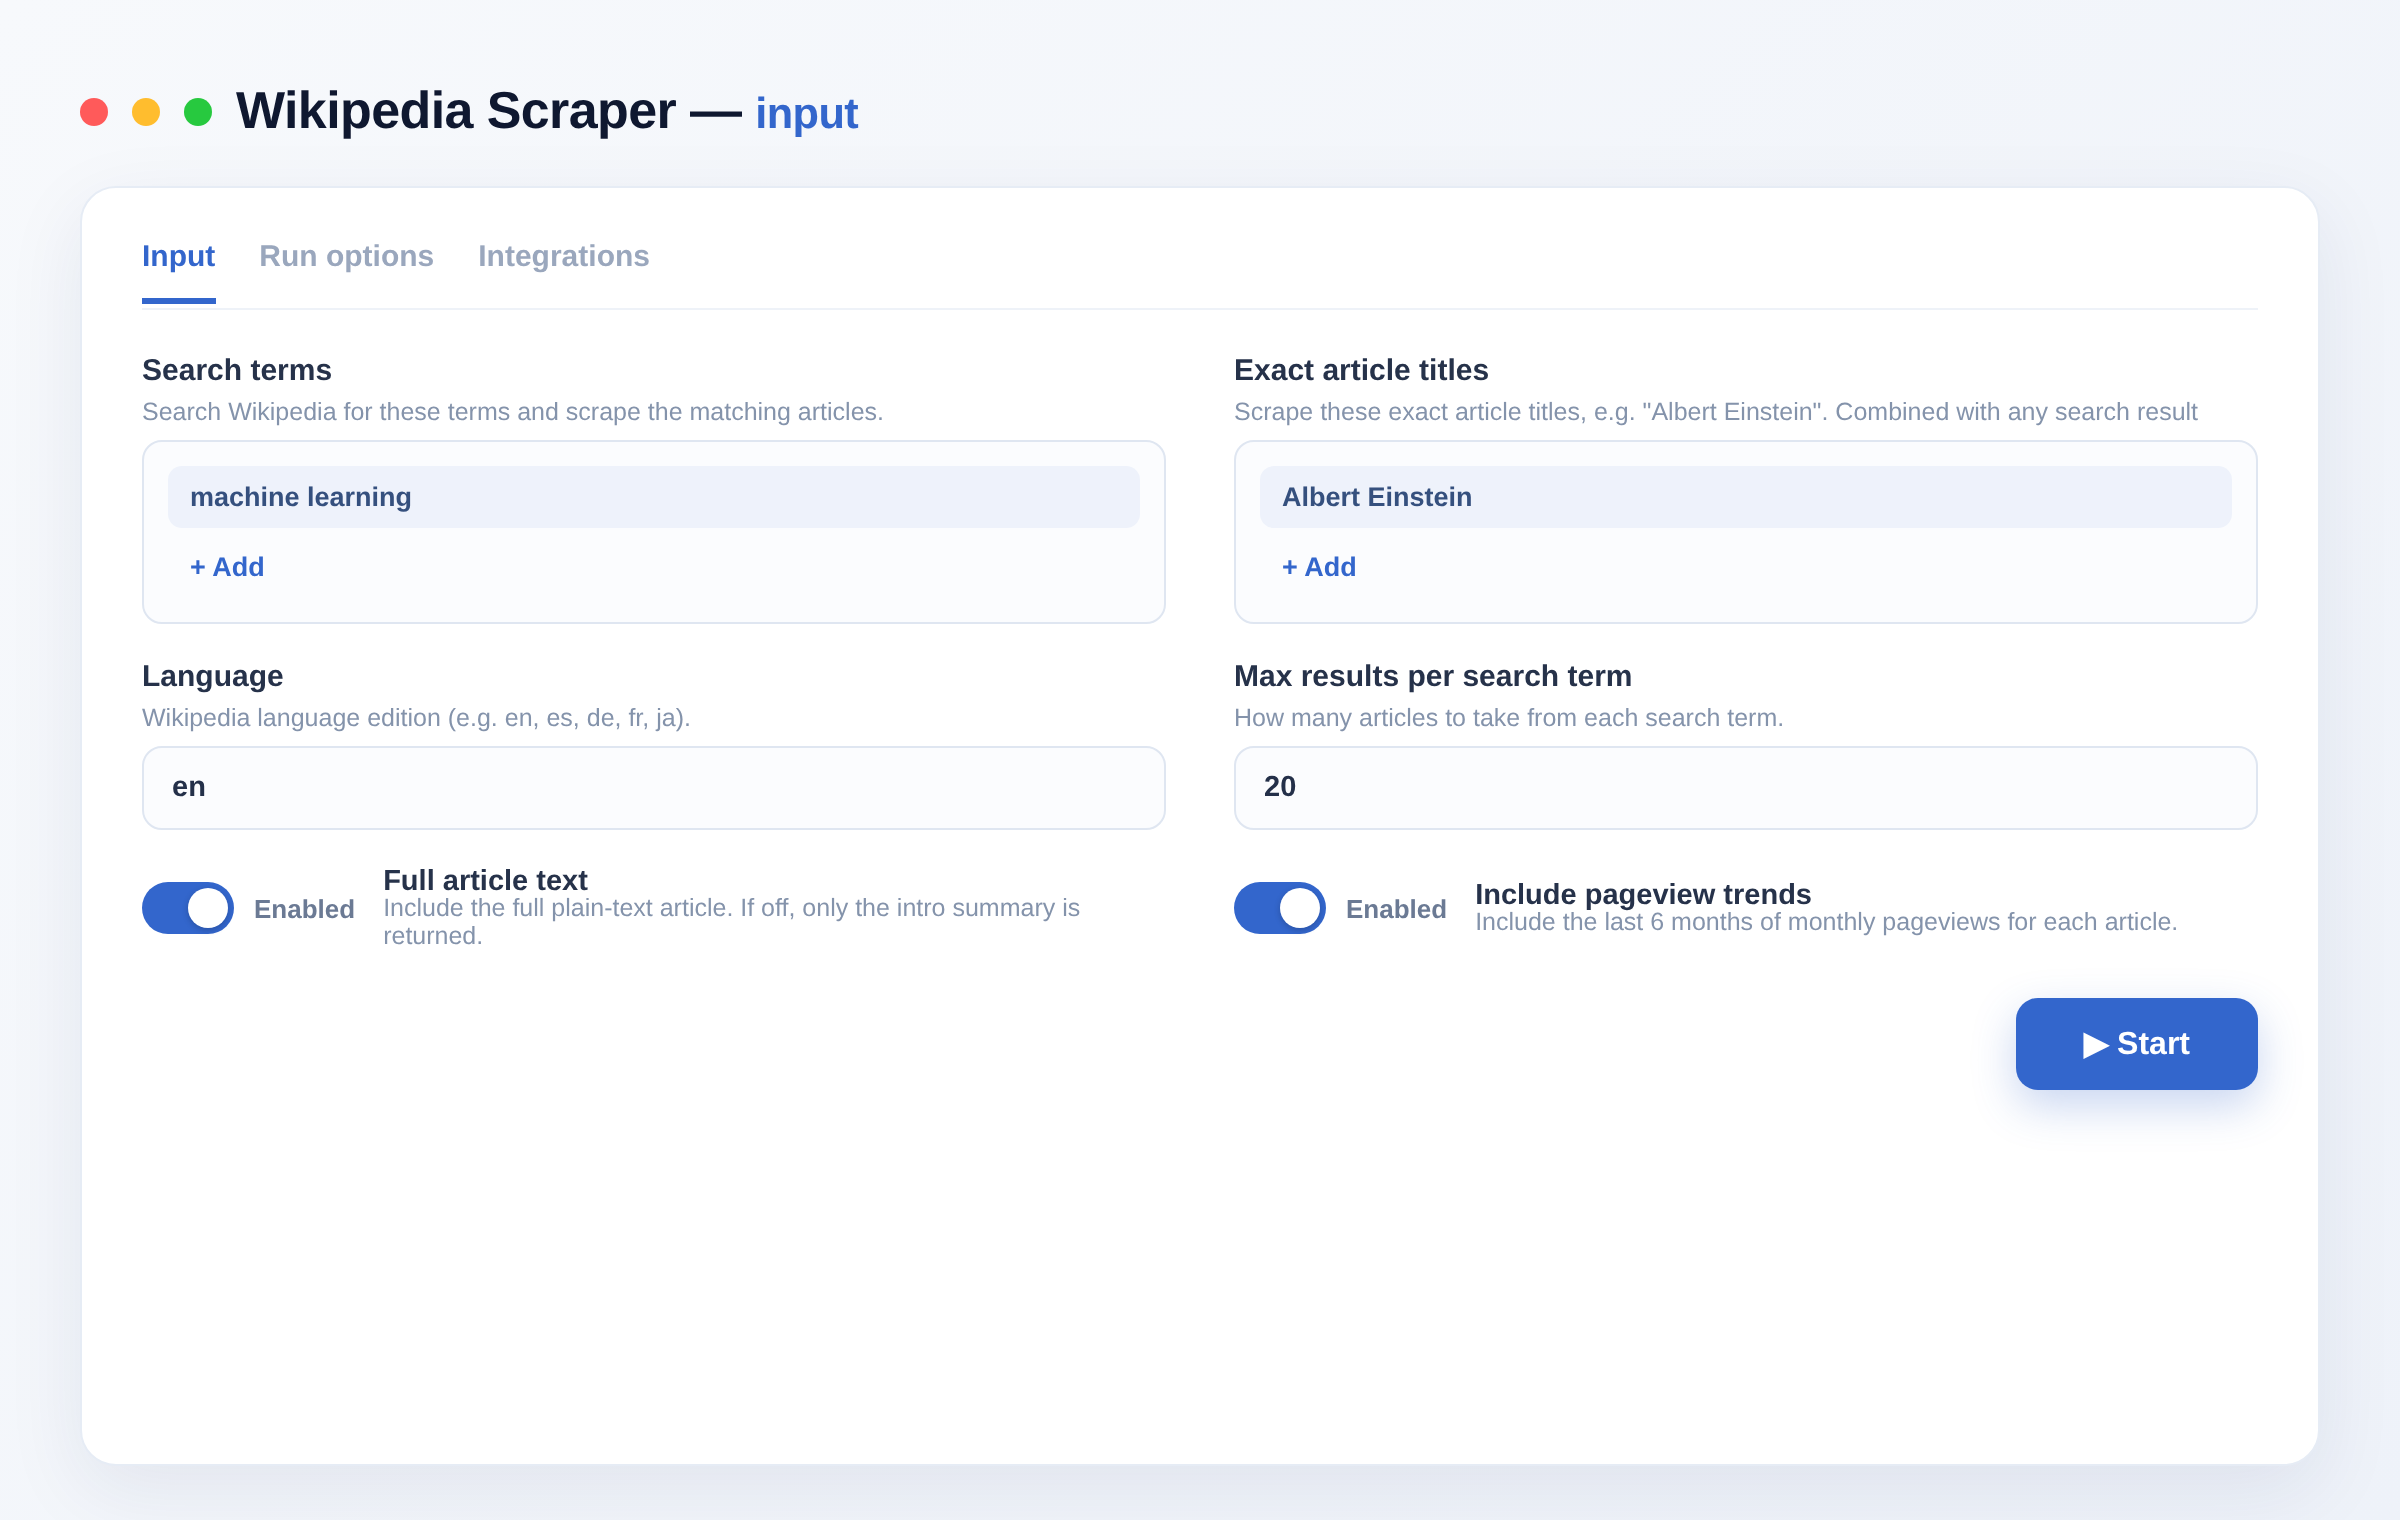
searchTermsSearch terms | array | Search Wikipedia for these terms and scrape the matching articles. |
titlesExact article titles | array | Scrape these exact article titles, e.g. "Albert Einstein". Combined with any search results. |
languageLanguage | string | Wikipedia language edition (e.g. en, es, de, fr, ja). Default: "en" |
maxResultsPerSearchMax results per search term | integer | How many articles to take from each search term. Default: 20 |
fullTextFull article text | boolean | Include the full plain-text article. If off, only the intro summary is returned. Default: true |
includePageviewsInclude pageview trends | boolean | Include the last 6 months of monthly pageviews for each article. Default: true |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~wikipedia-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "searchTerms": [
    "machine learning"
  ],
  "titles": [
    "Alan Turing",
    "Python (programming language)"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/wikipedia-scraper").call(run_input={
"searchTerms": [
"machine learning"
],
"titles": [
"Alan Turing",
"Python (programming language)"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/wikipedia-scraper').call({
"searchTerms": [
"machine learning"
],
"titles": [
"Alan Turing",
"Python (programming language)"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Article scraped One Wikipedia article with full text, summary, categories, image, Wikidata ID and pageview trends | $0.001 | $0.0005 |
| Search request One Wikipedia search request | $0.0005 | $0.0005 |
| API request One article-content or pageviews fetch | $0.0003 | $0.0003 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Europe PMC Scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
325 runs · 5 users · $0.001 / article scraped
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
Letterboxd Scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
139 runs · 7 users · $0.0042 / film scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
OpenAlex Scholarly Works Scraper
Search 250M+ academic papers via OpenAlex: title, abstract, authors, institutions, venue, citation count, DOI, open-access status and topics. Filter by year, type and open access. For research, R&D and lit reviews. No setup.
118 runs · 1 users · $0.001 / work scrapedSend the site and the fields. We build it and you get it first.